AI1 min read
Huawei moves Ascend 960DT chip launch to Q1 2027
Huawei plans to launch its new Ascend 960DT AI chip in the first quarter of 2027. This is earlier than its previous plan for the third quarter.
From TechCrunch AI
Blog
Daily notes on new models, LLM releases, agent frameworks and AI research, written from the sources we follow and delivered as a newsletter every day.
Get the morning and evening issues
Every new post of the day, in one email. Confirmation required.
AI1 min read
Huawei plans to launch its new Ascend 960DT AI chip in the first quarter of 2027. This is earlier than its previous plan for the third quarter.
From TechCrunch AI
AI1 min read
OpenAI released a new framework to track and disclose misalignment issues in its models. It includes three review tracks and six detailed incident reports from reinforcement learning training.
From MarkTechPost
How this blog is made
POST /api/v1/route with execute: true.Photo: Yan Krukau
Nunchux AI launched VC-Attention to speed up video diffusion models without retraining. It uses low-bit quantization and replaces the slow softmax stage.
From MarkTechPost
AI1 min read
Dario Amodei proposed embedding third-party evaluators inside Anthropic. Sam Altman confirmed OpenAI would commit to the same practice.
From TechCrunch AI
Agents1 min read
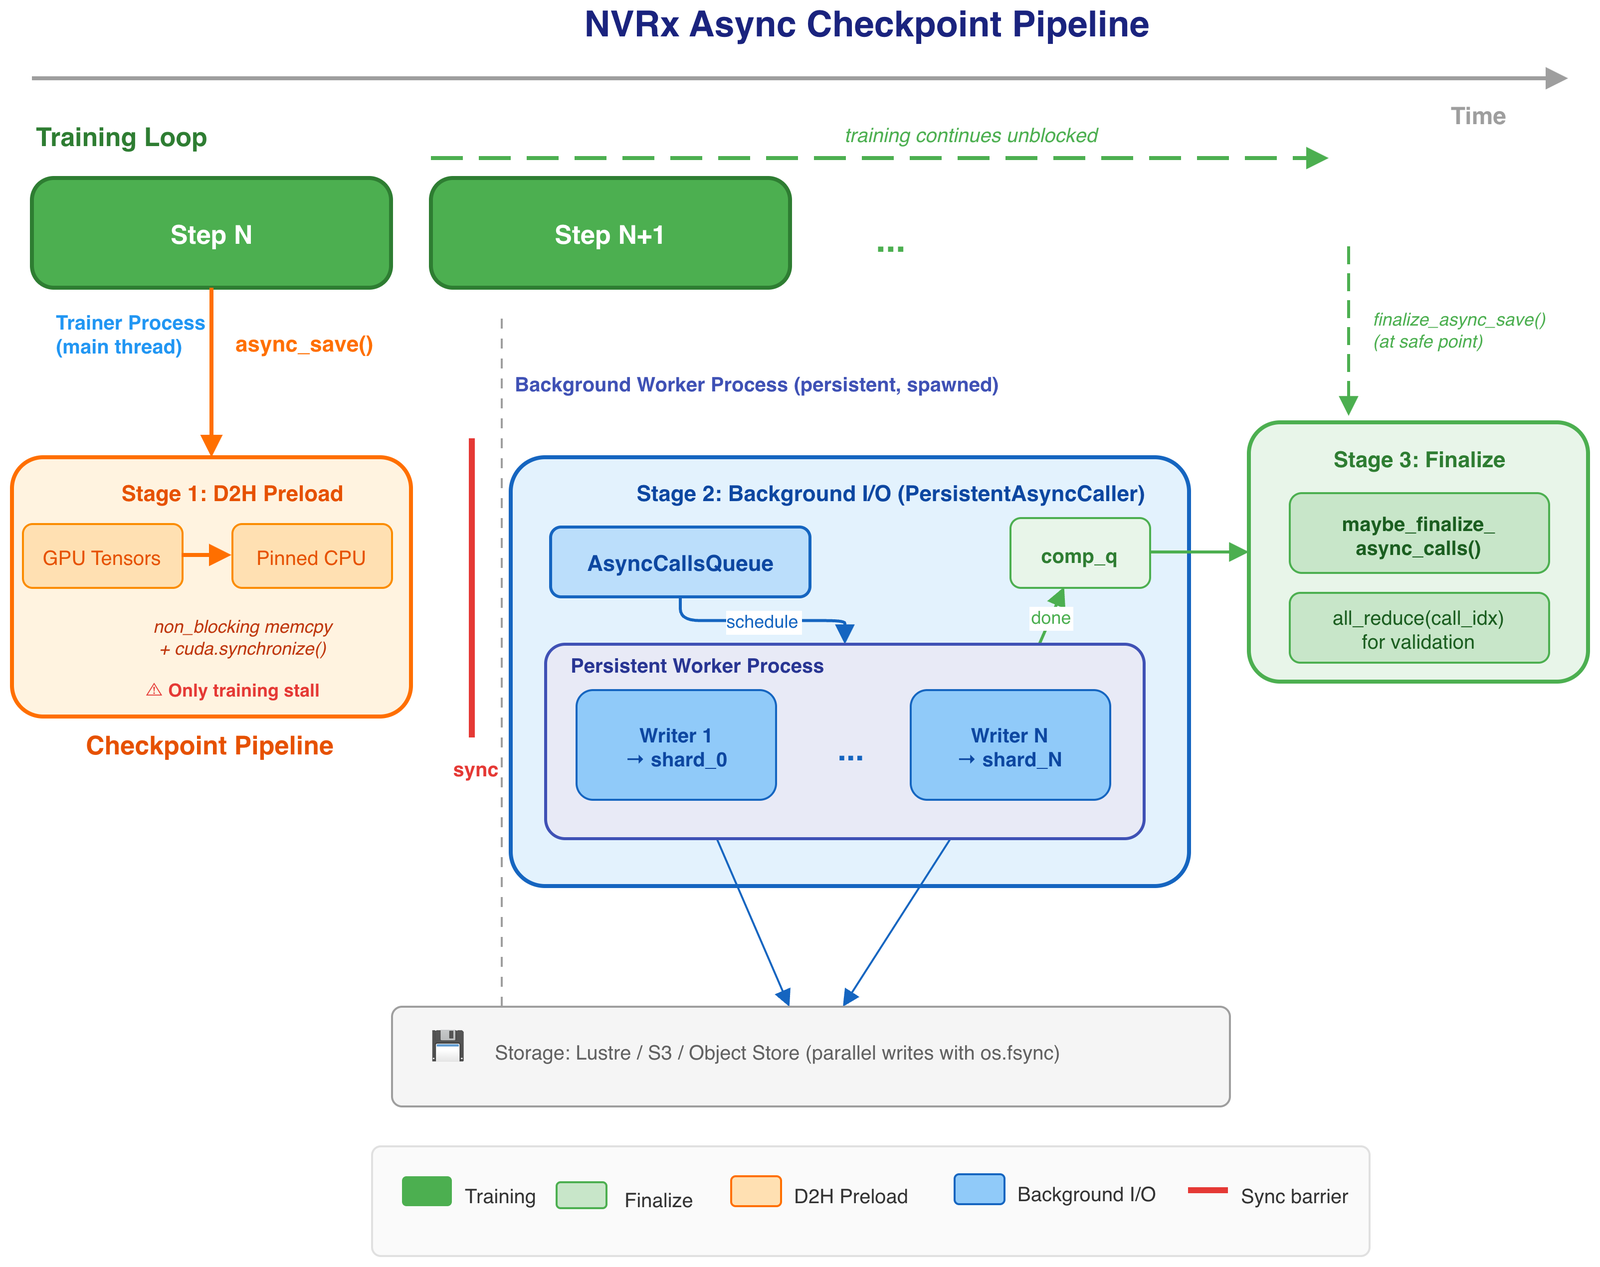
NVIDIA Resiliency Extension (NVRx) prevents GPU faults from stopping PyTorch training on Amazon EKS. Async checkpointing and automatic restarts save hours of wasted compute time.
From AWS machine learning blog
Agents1 min read
TypeSafe launched Jev, a model trained with RLCD for decisions. It is significantly faster and cheaper than small frontier models.
From Latent Space
LLMs1 min read
Researchers released NepLEGiT, a ~30 million parameter SLM pre-trained on 4 million tokens of Nepali legal text. The model achieves a perplexity of 1.8 and 82.9% next-token accuracy.
From arXiv cs.CL
LLMs1 min read
Researchers propose MIMIC, a framework using executable code to synthesize high-fidelity reasoning data. Training on this dataset improves accuracy across general reasoning and mathematical benchmarks.
From arXiv cs.CL
LLMs1 min read
A new pipeline synthesizes 90k multimodal samples to enable scalable Reinforcement Learning with Verifiable Rewards, improving instruction-following by 8.13%.
From arXiv cs.CL
Agents1 min read
Good Start Labs trained an AI on a railroad game — and one version improved at financial research. The difference was the training design.
From Latent Space
LLMs1 min read
For operators of large-scale AI factories, maximizing continuous output is essential for productivity. In massive-scale AI training, every GPU in the cluster...
From NVIDIA technical blog
Agents1 min read
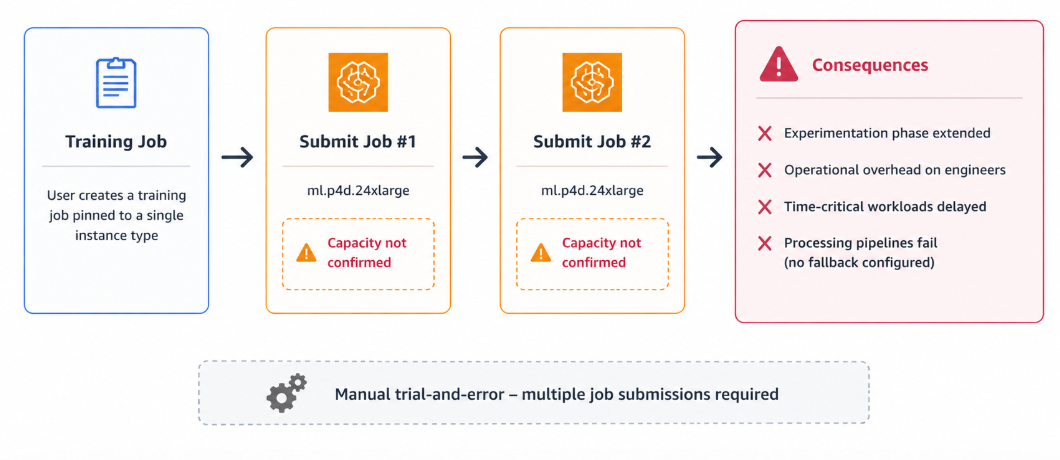
Amazon SageMaker AI now offers instance preference lists for training and processing jobs. Specify an ordered list of up to five instance types, and SageMaker AI automatically launches on the first type with available capacity, eliminati...
From AWS machine learning blog
LLMs1 min read
arXiv:2609.13151v1 Announce Type: new Abstract: Leading multilingual speech recognition models like Whisper transcribe diverse, low-resource languages without language-specific training but are computationally expensive to deploy. Token ...
From arXiv cs.CL
LLMs1 min read
arXiv:2609.13154v1 Announce Type: new Abstract: Recent advances in large language models (LLMs) have made prompts increasingly large and complex. Techniques such as chain-of-thought reasoning (Wei et al., 2022) and in-context learning (B...
From arXiv cs.CL
AI1 min read
Reward AI has released OM-1, a general-purpose manipulation policy trained exclusively on human demonstrations using a wearable glove. The system’s unique approach avoids teleoperation and robot data, offering a new path for robot control.
From MarkTechPost
AI1 min read
Sakana AI researchers introduced PC-ALM, a layer-local training method for deep networks that achieves performance comparable to backpropagation up to 1000 layers on MNIST. The research provides a JAX implementation for experimentation and benchmarking.
From MarkTechPost
LLMs1 min read
The NVIDIA Transformer Engine, when combined with JAX, delivers a 10.4x throughput improvement for Mixture of Experts training on NVIDIA GB200 GPUs, enabling DeepSeek-V3 to reach 1,068 TFLOPS/GPU. This achieves dropless MoE training by optimizing grouped GEMM kernels and NCCL EP for variable expert token counts.
From NVIDIA technical blog
Models1 min read
DevFest 2026, running from October 1 – December 31, 2026, offers nearly a million developers hands-on experience with Google’s AI technologies across a global network of events. The program focuses on building, securing, and scaling in the agentic era.
From Google AI blog
Agents2 min read
This post outlines a framework for customizing generative AI models on AWS, ranging from simple prompt engineering to training custom models. The spectrum guides engineers through the appropriate level of investment based on workload requirements and data needs.
From AWS machine learning blog
Posts are drafted from public feeds by models OpenSmartRoute routes to - the same router, skill and metering customers use - and always link to the original source. Corrections: support.
Archive (93)