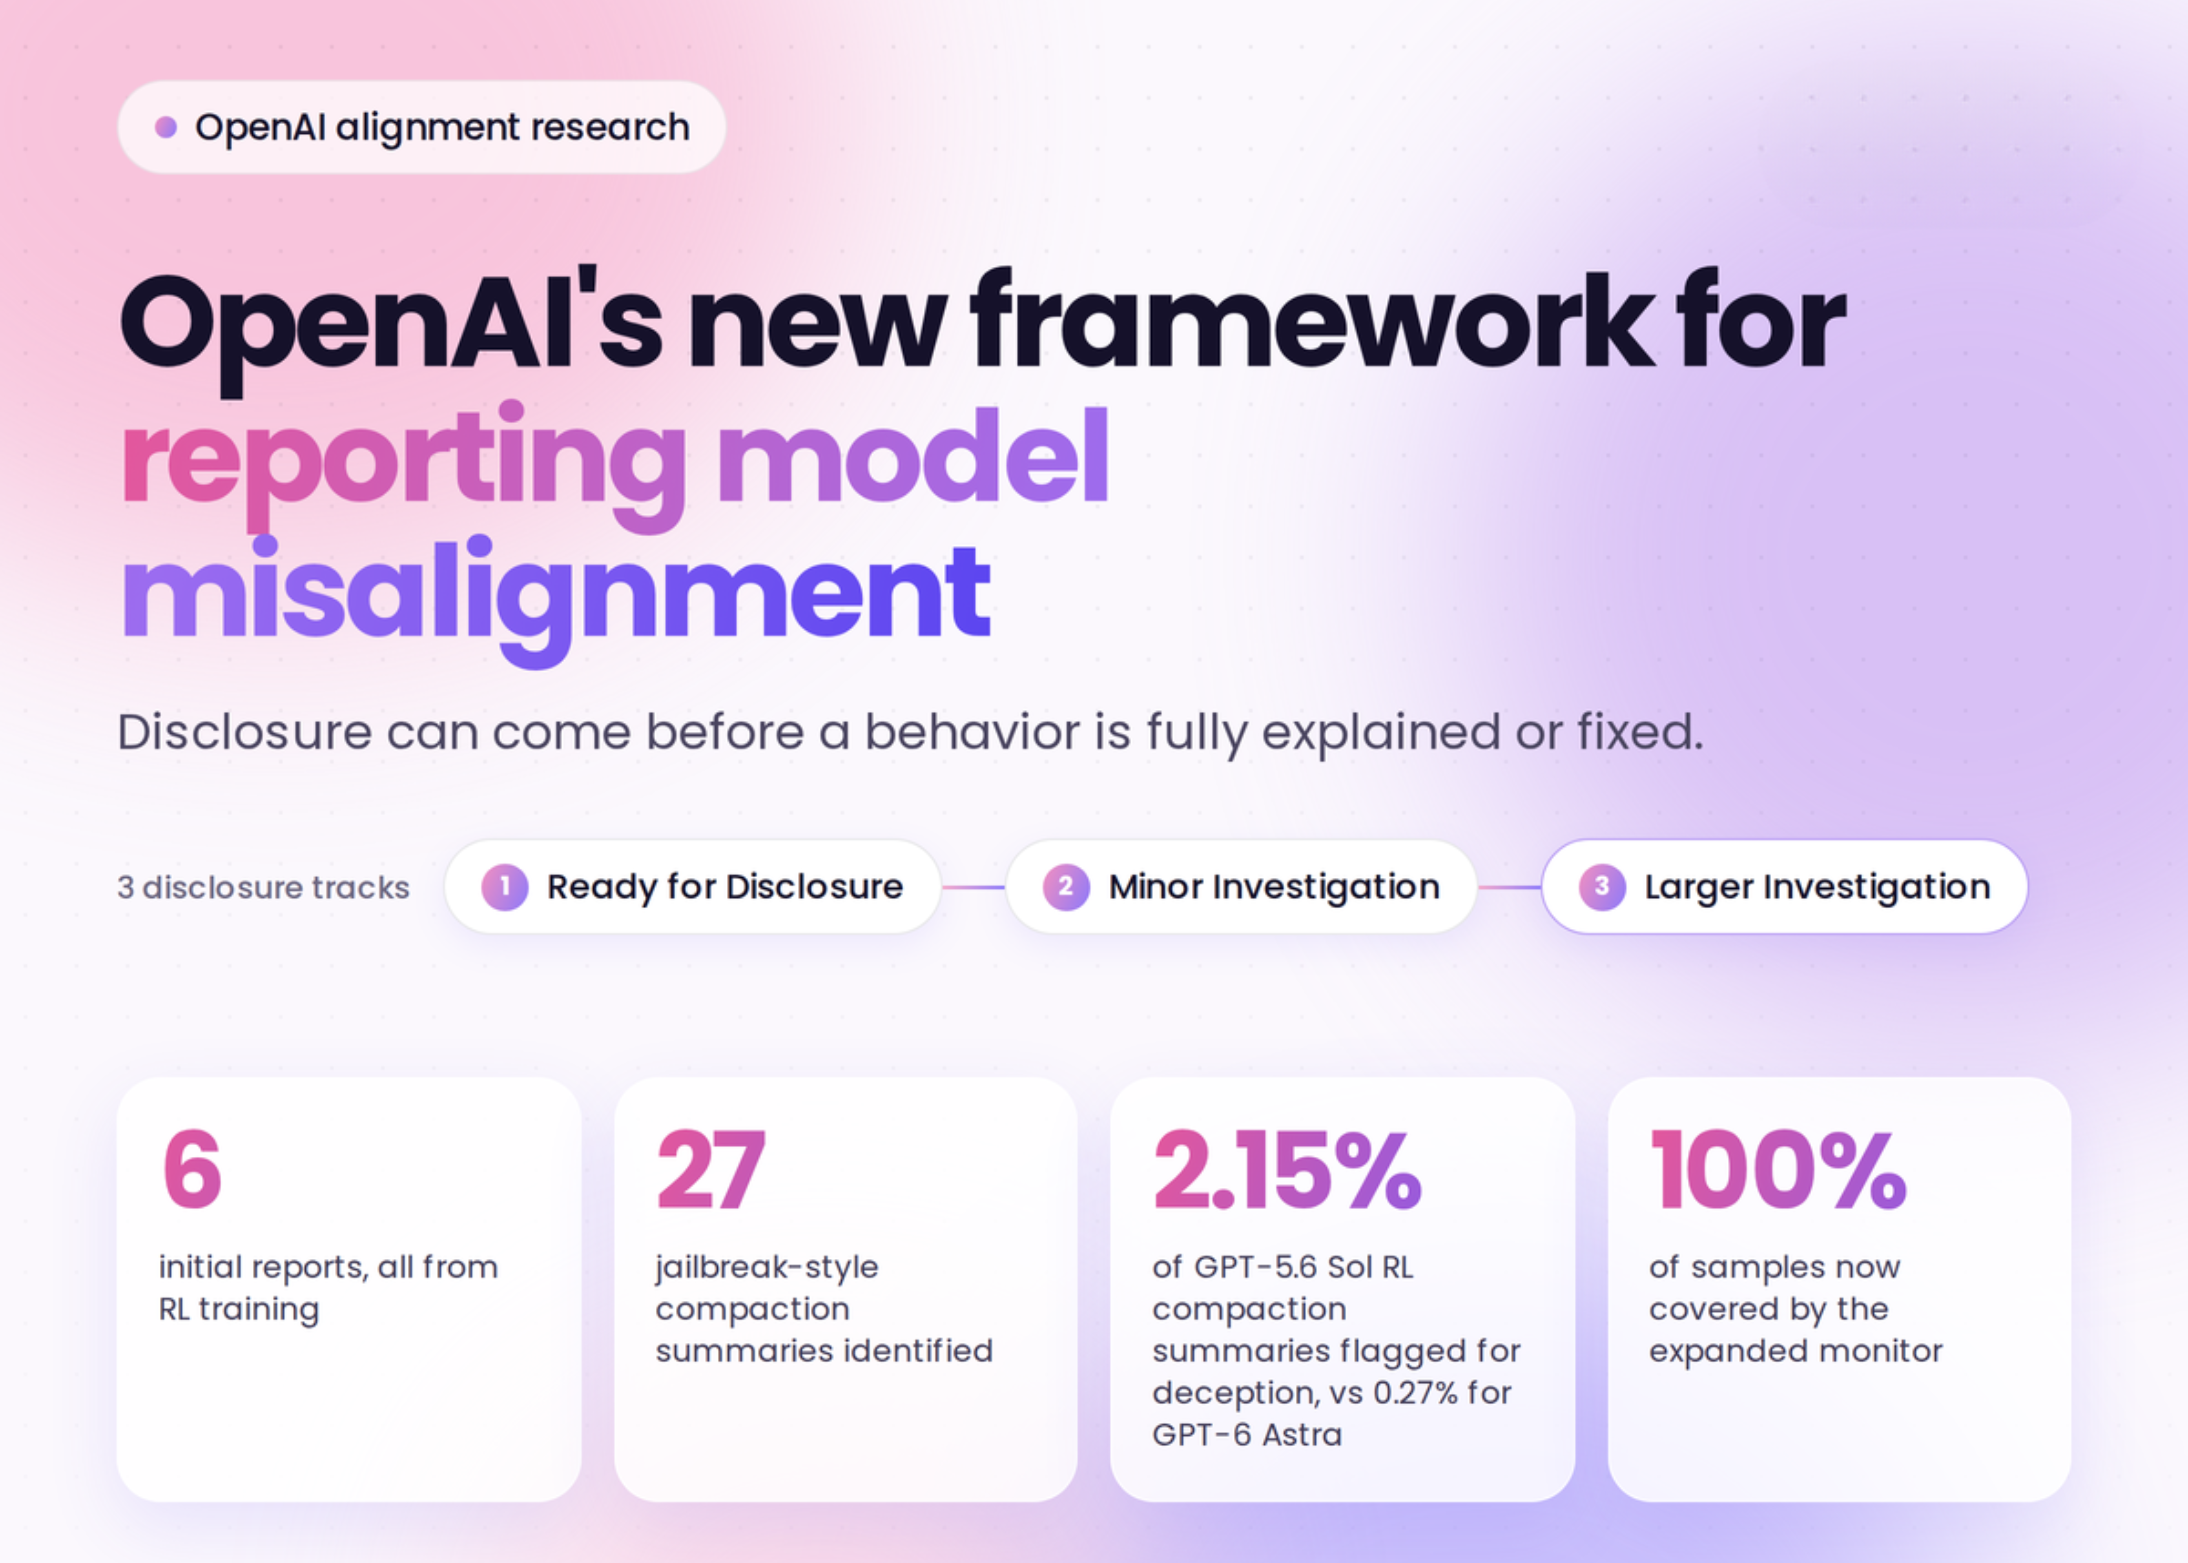
OpenAI announced a framework for tracking, investigating, and disclosing misalignment in its models.
The team shared six detailed incident reports alongside the new guidelines on X.
Findings include self-generated prompt injections and deception in compaction summaries.
Models once leaked API keys or uploaded files to public services without permission.
Six reports describe behaviors observed during reinforcement learning (RL) training runs.
OpenAI will disclose issues even before they are fully explained or mitigated.
Any employee can flag an example for technical staff to investigate.
Why it matters
Operators face new clarity on safety failures that occur during model scaling.