Agents2 min read
Build real-time voice apps with vLLM-Omni on SageMaker AI updates
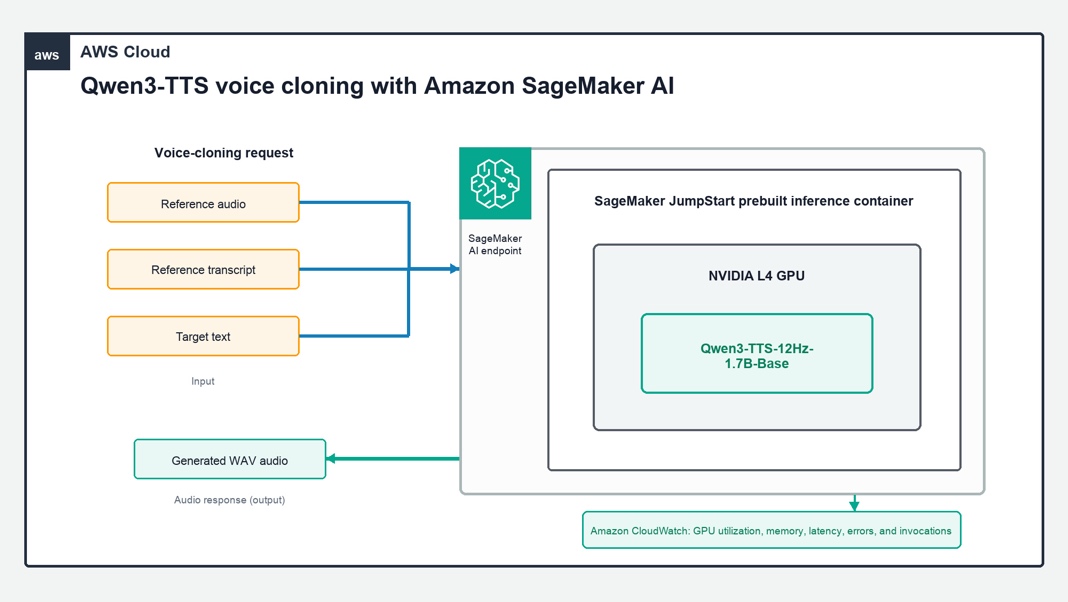
This update shows how to deploy a text-to-speech model on SageMaker AI using vLLM-Omni. It streams speech over a WebSocket connection.
From AWS machine learning blog
90 days of the enterprise, pro and team plans free, no card needed. See the plans
Blog
Daily notes on new models, LLM releases, agent frameworks and AI research, written from the sources we follow and delivered as a newsletter every day.
Get the morning and evening issues
Every new post of the day, in one email. Confirmation required.
Agents2 min read
This update shows how to deploy a text-to-speech model on SageMaker AI using vLLM-Omni. It streams speech over a WebSocket connection.
From AWS machine learning blog
Agents2 min read
Amazon SageMaker now supports deploying Qwen3-TTS for real-time voice cloning. Users can generate speech in a target speaker’s voice from a short reference.
From AWS machine learning blog
Photo: Yan Krukau
Research9 min read
Apple researchers compressed a speech tokenizer by 2.8 times while keeping error rates nearly identical to the original model.
From Apple machine learning research
LLMs1 min read
Researchers developed a scalable method using acoustic masking to quantify the contribution of individual consonants to word intelligibility. The study, employing ASR models across English, Spanish, German, and Czech, identified phoneme frequency and functional load as key factors influencing consonant disruption rates.
From arXiv cs.CL
LLMs1 min read
This research traces the evolution of algorithmic outputs, identifying three key mutations – speech as data, speech as engagement, and generative text – and their associated legal and social consequences. It provides a framework for understanding these changes and their impact on freedom of expression and informational privacy.
From arXiv cs.CL
LLMs1 min read
SEA-SpeechBench is a new large-scale benchmark evaluating speech understanding across 11 Southeast Asian languages. Initial evaluations of leading models reveal significant performance gaps, particularly in temporal understanding and low-resource language prompting.
From arXiv cs.CL
LLMs1 min read
A new dataset, TamilEOT, and two audio-only detectors are released for semantic end-of-turn detection in Tamil telephone speech. The models achieve accuracy improvements of 13.41% on a held-out test set, with inference times under 150ms.
From arXiv cs.CL
LLMs1 min read
TRILOGUE is a large-scale trilingual benchmark for spoken dialogue fact-checking, including audio, transcripts, and turn-level labels across English, Russian, and Kazakh.
From arXiv cs.CL
LLMs1 min read
The Open ASR Leaderboard has added a new model for Swahili, marking the first language from the Global South. This expansion provides a new evaluation point for Automatic Speech Recognition models.
From Hugging Face blog
Research1 min read
Gemini 3.5 Transcribe offers enhanced speech-to-text transcription capabilities, aiming to improve accuracy and intelligence in transcription tasks.
From Google DeepMind blog
LLMs1 min read
Hugging Face introduced the ASRA benchmark to evaluate and compare the optimization of speech recognition models. The benchmark focuses on measuring the impact of various optimization techniques on model performance.
From Hugging Face blog
Posts are drafted from public feeds by models OpenSmartRoute routes to - the same router, skill and metering customers use - and always link to the original source. Corrections: support.
Archive (100)