Amazon SageMaker now allows deploying the Qwen3-TTS-12Hz-1.7B-Base model for real-time voice cloning. This model can generate speech in a target speaker’s voice using only a few seconds of reference audio.
Qwen3-TTS supports 10 languages, including Chinese, English, and Japanese. It uses the Qwen3-TTS-Tokenizer-12Hz speech tokenizer and can stream audio for interactive uses.
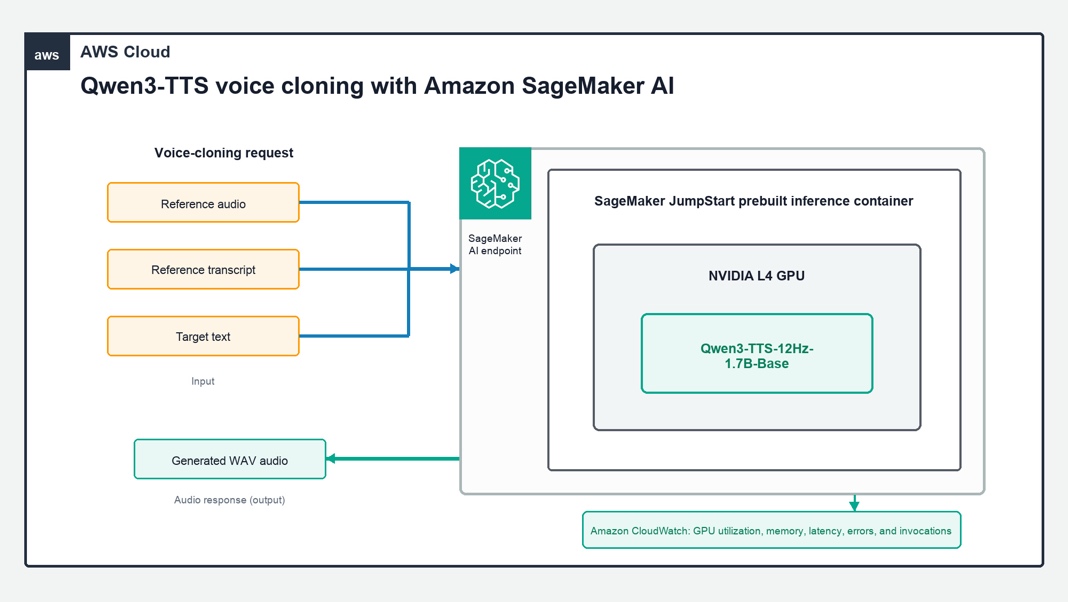
The deployment uses Amazon SageMaker JumpStart, which provides the model artifacts and a pre-built serving container. This setup eliminates the need for custom inference code. You create a model object, deploy it, and then call the endpoint.
The system routes requests to a GPU instance that generates speech tokens from the text and reference voice. It then converts tokens into waveform audio. The response is sent back as WAV audio.
This approach offers benefits like personalization at scale, multilingual support, cost savings, and data control. It is suitable for content localization, customer engagement, education, and conversational AI.
To use this, ensure you have an AWS account with SageMaker and S3 access, plus the necessary permissions. You also need a SageMaker environment or local setup.
This deployment makes voice cloning accessible for real-time applications without managing underlying GPU servers.