LLMs8 min read
Qwen3.8 27B Model Adds Large Numbers in Words
A test showed Qwen3.8-27B computes sums and returns the answer in English words. It succeeded when reasoning was enabled but failed without it.
From Simon Willison on LLMs
90 days of the enterprise, pro and team plans free, no card needed. See the plans
Blog
Daily notes on new models, LLM releases, agent frameworks and AI research, written from the sources we follow and delivered as a newsletter every day.
Get the morning and evening issues
Every new post of the day, in one email. Confirmation required.
LLMs8 min read
A test showed Qwen3.8-27B computes sums and returns the answer in English words. It succeeded when reasoning was enabled but failed without it.
From Simon Willison on LLMs
AI1 min read
AWS's Strands Agents team released Strands Decider 2B, an Apache-2.0 decision model built on Qwen3.5-2B-Base. It returns choices, yes/no probabilities and scores with calibrated confidence in one forward pass, never text. It runs at a 11...
From MarkTechPost
Photo: Yan Krukau
Agents2 min read
This update shows how to deploy a text-to-speech model on SageMaker AI using vLLM-Omni. It streams speech over a WebSocket connection.
From AWS machine learning blog
Agents2 min read
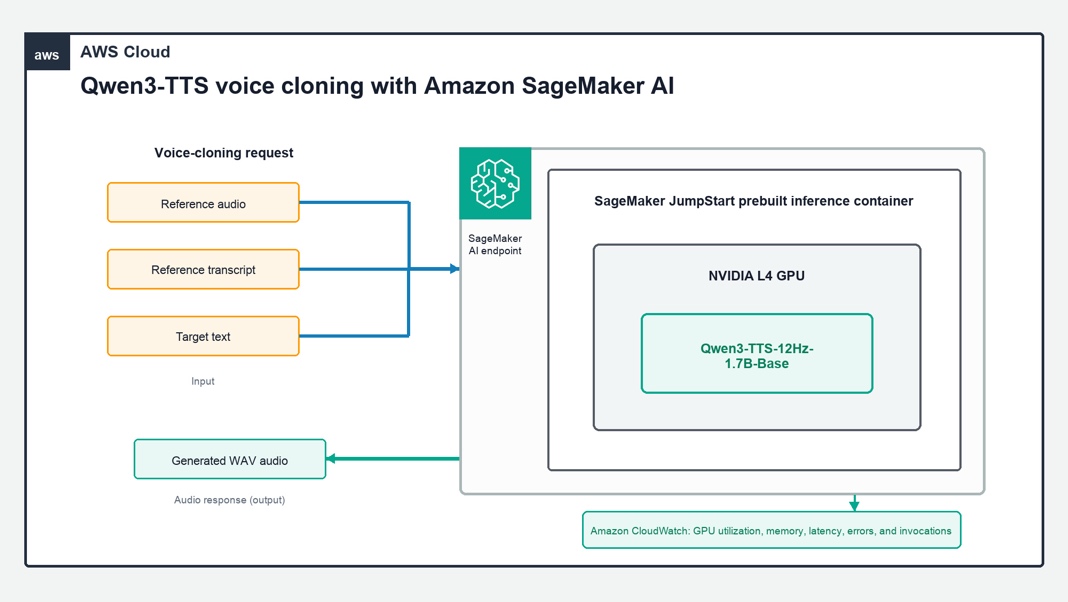
Amazon SageMaker now supports deploying Qwen3-TTS for real-time voice cloning. Users can generate speech in a target speaker’s voice from a short reference.
From AWS machine learning blog
AI1 min read
BottleCap AI has released ThinkingCap-Qwen3.8-27B, a fine-tune of Qwen3.8-27B that spends 37.2% fewer thinking tokens across 12 benchmarks. Macro accuracy moves from 86.65% to 85.79%, and long-context AA-LCR improves by 2.25pp. The model...
From MarkTechPost
AI1 min read
Contrastive-LM has released CLM-8B, an open System One model that scores candidate actions against a state instead of generating text. It adds 2 small projection heads to a frozen Qwen3-8B encoder and trains them with a contrastive InfoN...
From MarkTechPost
LLMs1 min read
We just launched our own Jev-like classifier, together/Tev1-4B-experimental, on top of Qwen3.5 4B on Together’s serverless platform. In this blog post we’ll show you how to fine-tune your own version!
From Together AI blog
AI2 min read
Qwen3.8-LiveTranslate is a new model that translates speech in real time with less delay. It supports 60 languages and adds features like speaker identification.
From MarkTechPost
AI1 min read
PrismML has released Ternary Bonsai 2 27B, a ternary-weight version of Qwen3.8 27B. The language model occupies 5.93 GB, against 53.80 GB in FP16. PrismML reports that it keeps 98.2% of the parent model’s average across 20 benchmarks. Th...
From MarkTechPost
AI1 min read
Alibaba's Qwen3.8-Omni-Flash understands audio and video, plans tasks, calls tools, and reports about 45.7% fewer tokens on OmniVideoBench. The post Alibaba Qwen Releases Qwen3.8-Omni-Flash: A 1M-Context Omni-Modal Model Built Around Age...
From MarkTechPost
AI1 min read
PrismML launched Bonsai 2, a 5.9 GB model based on Qwen3.8. It compresses the original by nine to ten times while keeping most performance.
From TechCrunch AI
LLMs2 min read
TensorRT Edge-LLM ran Qwen3.6-27B on a Jetson AGX Thor. It finished the MLPerf Edge Agentic benchmark 6.4 times faster than the reference run.
From NVIDIA technical blog
Agents1 min read
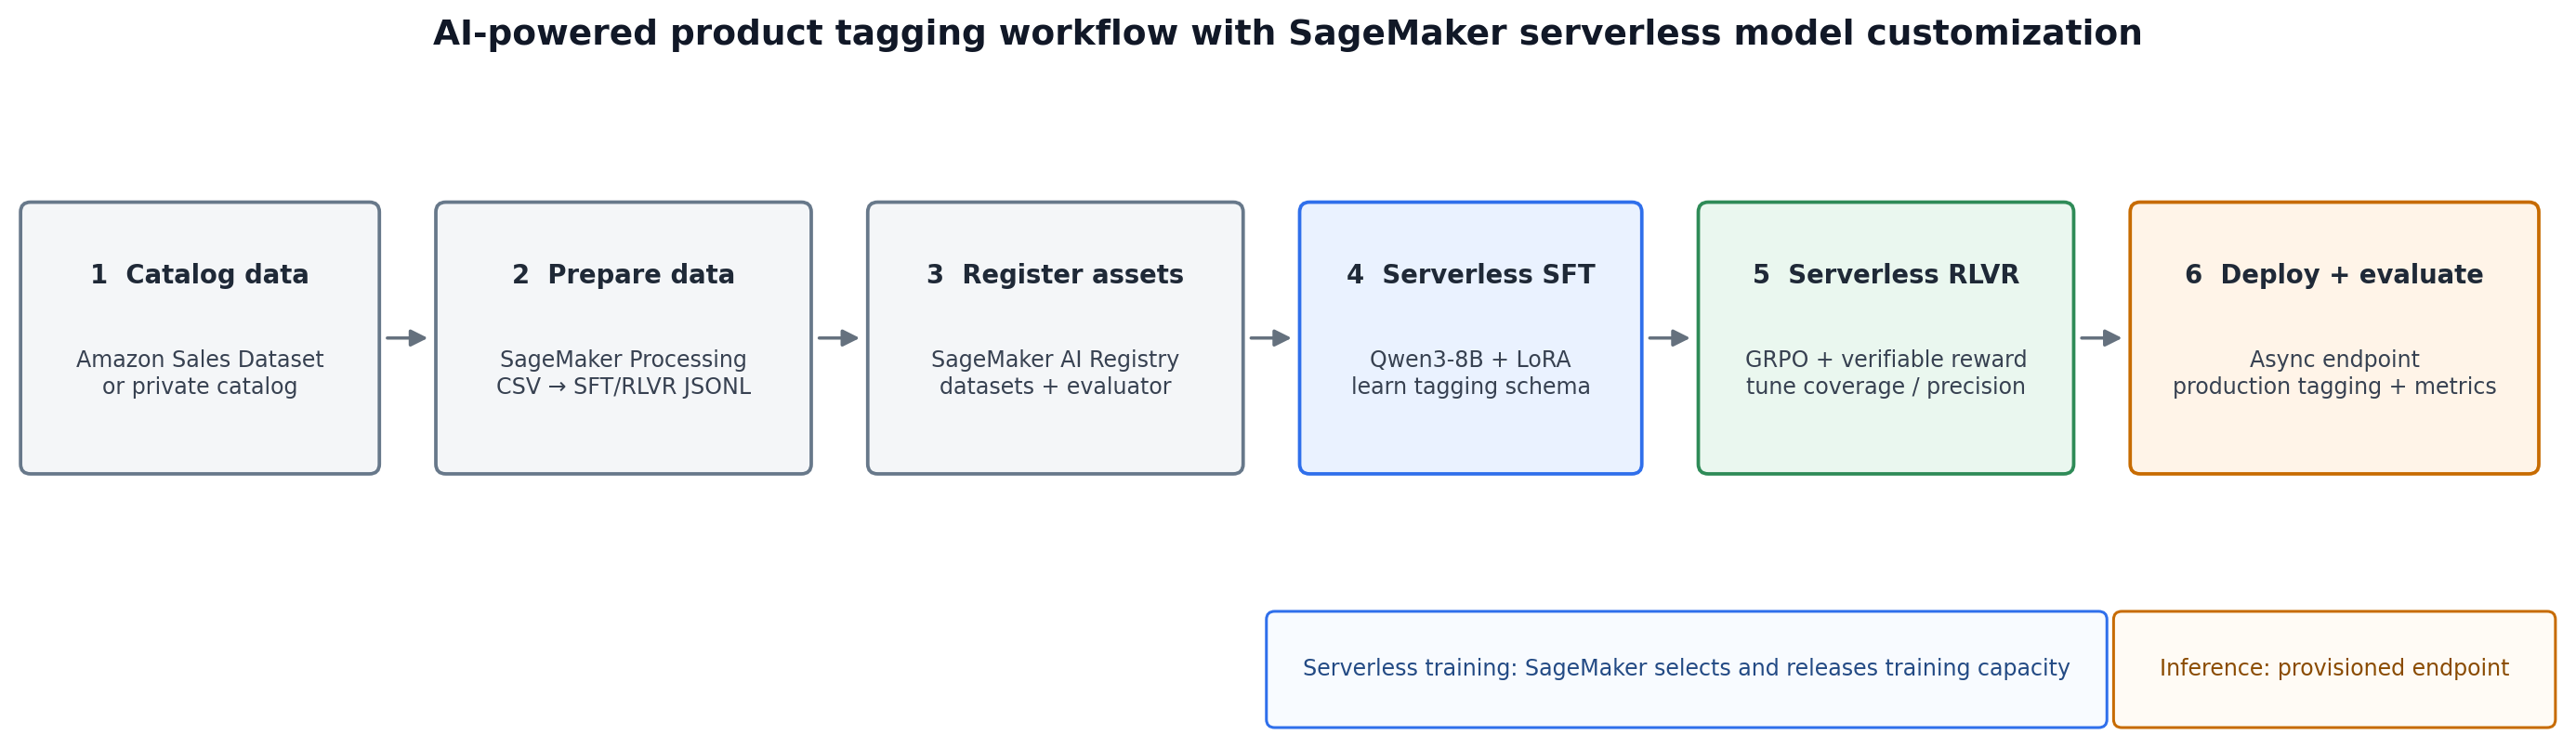
Manually tagging thousands of catalog products is slow and inconsistent. This walkthrough shows how to customize Qwen3-8B with supervised fine-tuning (SFT) and reinforcement learning with verifiable rewards (RLVR) on Amazon SageMaker ser...
From AWS machine learning blog
LLMs1 min read
Researchers introduced AMDKernelVault, a large dataset and training framework for AMD GPU kernel optimization using HIP and Triton. Qwen3-8B achieved high correctness on PyTorch-to-HIP, TritonBench-G, and ROCmBench benchmarks, demonstrating the corpus's utility.
From arXiv cs.CL
LLMs1 min read
Researchers developed a training framework for multi-hop question answering using Qwen3-14B, augmenting knowledge graphs with surrounding context. This approach, incorporating a repair pipeline and reinforcement learning, consistently improved multi-hop performance compared to KG-only supervision.
From arXiv cs.CL
Research1 min read
Researchers released Occamy-1.0, a 35 billion parameter model trained on a Qwen3.6-35B checkpoint. Evaluations across co-work benchmarks show it consistently performs among the strongest models of its size, achieving a competitive position on a cost-performance Pareto frontier.
From arXiv cs.AI
LLMs1 min read
TEFM is a new framework for applying LLMs to critical domains by reducing token consumption and maintaining faithfulness. Experiments across Qwen3, Gemma-2, and Phi-4 show significant token reduction with competitive accuracy and faithful rationales.
From arXiv cs.CL
Agents1 min read
This post details deploying the 2.4-trillion parameter Qwen3.8-2.4T-A95B model on Amazon SageMaker HyperPod using vLLM. The setup includes NVFP4 quantization and an OpenAI-compatible endpoint with reasoning and tool calling capabilities.
From AWS machine learning blog
Research1 min read
EnvCraft is a framework for creating synthetic, executable environments to accelerate Agentic RL training for claw-like agents. Experiments with Qwen3/3.5 models show significant performance gains and reduced inference costs.
From arXiv cs.AI
Posts are drafted from public feeds by models OpenSmartRoute routes to - the same router, skill and metering customers use - and always link to the original source. Corrections: support.
Archive (100)