Research1 min read
Introducing Gemini 3.8 Live and 3.8 Live Extended Thinking
Google DeepMind blog published Introducing Gemini 3.8 Live and 3.8 Live Extended Thinking.
From Google DeepMind blog
Blog
Daily notes on new models, LLM releases, agent frameworks and AI research, written from the sources we follow and delivered as a newsletter every day.
Get the daily issue
Every new post of the day, in one email. Confirmation required.
Research1 min read
Google DeepMind blog published Introducing Gemini 3.8 Live and 3.8 Live Extended Thinking.
From Google DeepMind blog
LLMs1 min read
For operators of large-scale AI factories, maximizing continuous output is essential for productivity. In massive-scale AI training, every GPU in the cluster...
From NVIDIA technical blog
How this blog is made
Each feed entry becomes one request to OpenSmartRoute: the router picks a model with a cost-weighted objective, the editorial-writer skill is layered on the prompt, and the outcome trains the learners - the same pipeline available to every workspace.
Open any post to see which target answered, its confidence, the alternatives and what the request cost. Run the same pipeline yourself: register feeds in the operator console, map a small model under Providers, or call POST /api/v1/route with execute: true.
B-roll showing diverse environments and people, including a teacher and students in a classroom and a patient with a doctor
From Google AI blog
LLMs1 min read
The NVIDIA Transformer Engine, when combined with JAX, delivers a 10.4x throughput improvement for Mixture of Experts training on NVIDIA GB200 GPUs, enabling DeepSeek-V3 to reach 1,068 TFLOPS/GPU. This achieves dropless MoE training by optimizing grouped GEMM kernels and NCCL EP for variable expert token counts.
From NVIDIA technical blog
Agents1 min read
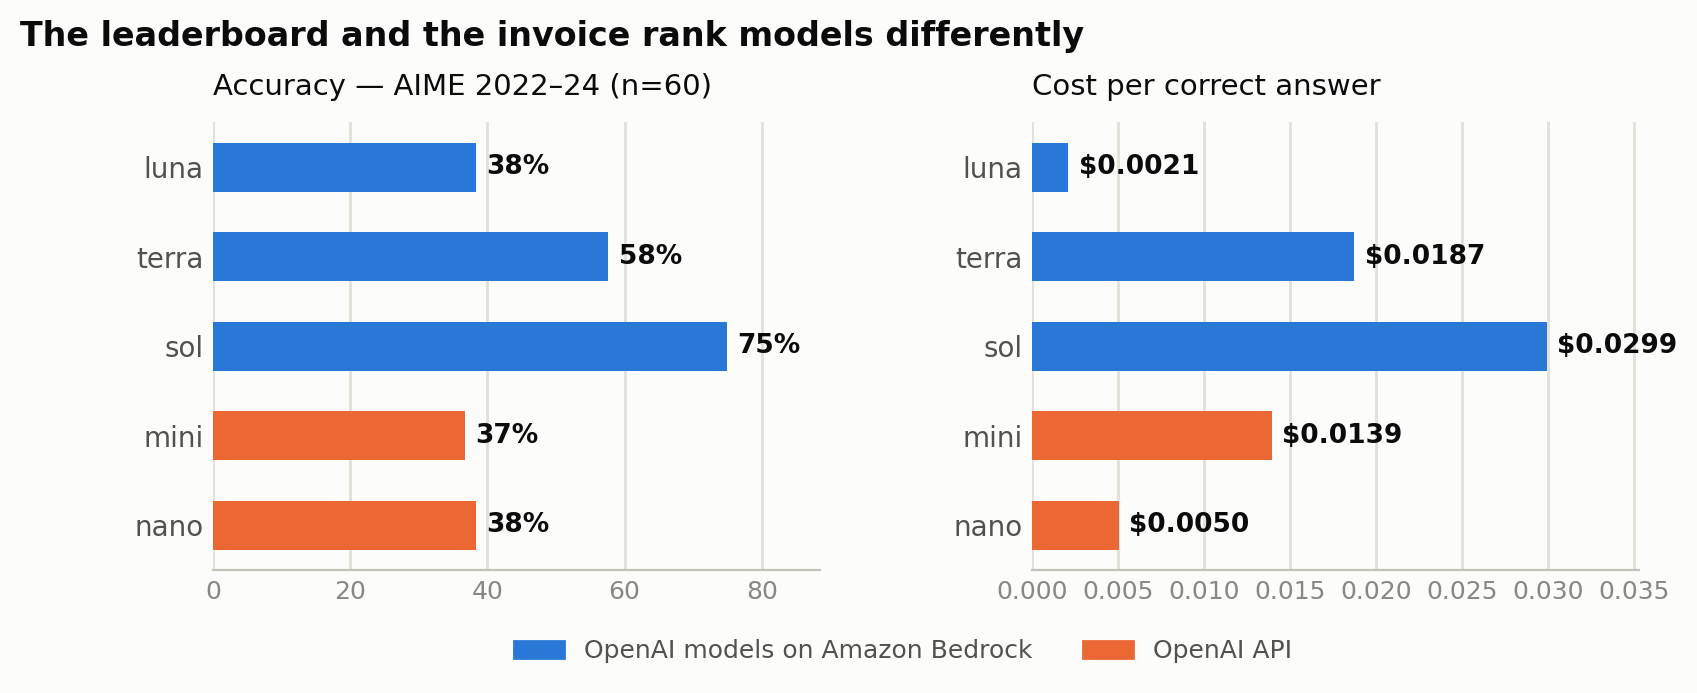
This post introduces a benchmarking harness to assess OpenAI models on Amazon Bedrock, focusing on cost per correct answer and deliverable quality rather than just price per token. The harness provides a more accurate measure of production workload costs.
From AWS machine learning blog
Agents1 min read
Amazon Bedrock AgentCore enables the creation of interactive MCP Apps with HTML widgets, providing a consistent experience across AI hosts like ChatGPT and Claude. This host-agnostic approach allows for seamless deployment and delivery of rich applications.
From AWS machine learning blog
Models1 min read
OpenAI’s GPT-6 Astra improves Devin’s ability to test software and verify functionality. This allows engineers to reduce code review efforts and accelerate software delivery.
From OpenAI news
LLMs1 min read
arXiv:2609.11131v1 Announce Type: new Abstract: Human simultaneous interpreting (SI) is commonly assessed with analytic rubrics separating meaning transfer, delivery quality, and temporal synchrony, yet no automatic metric is designed fo...
From arXiv cs.CL
LLMs1 min read
Together AI’s fine-tuning service now supports more open-weight models, offers live experiment tracking, and provides granular control over training processes. This expansion, alongside price reductions, enables faster, more efficient model development for a wider range of tasks.
From Together AI blog
LLMs1 min read
trynix.dev offers a web-based x86_64 Linux VM running Nix packages from the past 13 years, accessible through WebAssembly.
From Simon Willison
LLMs1 min read
Deploying a large language model is only the first step toward production-ready serving. Production teams also need to serve as many concurrent users as...
From NVIDIA technical blog
Models1 min read
Cloudera and Mistral AI are partnering to deliver specialized AI models tailored for enterprise use, focusing on sovereign AI solutions for regulated industries. This collaboration enables innovation within specific data environments.
From Mistral AI news
Models1 min read
GPT-Live-1 introduces full-duplex voice conversations to the OpenAI API, offering improved instruction following and telephony support. This allows for more natural and interactive voice experiences.
From OpenAI news
Agents1 min read
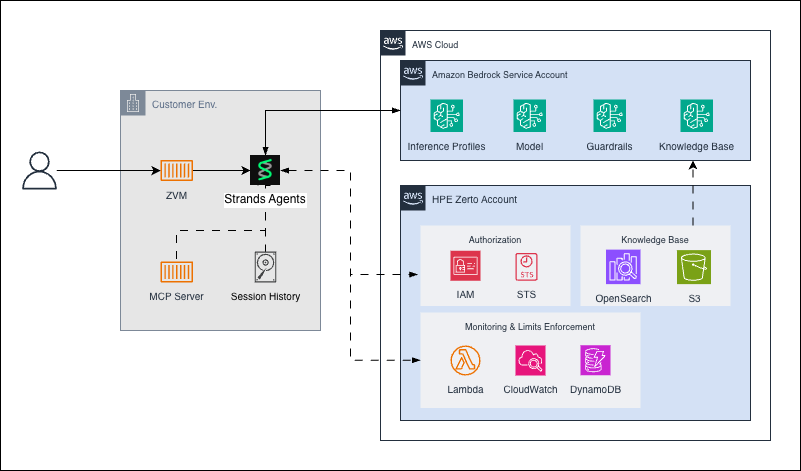
HPE Zerto created an agentic troubleshooting system using Amazon Bedrock, deployed on-premises with Strands Agents. This allows for grounding agents in live disaster recovery data for improved troubleshooting.
From AWS machine learning blog
Agents2 min read
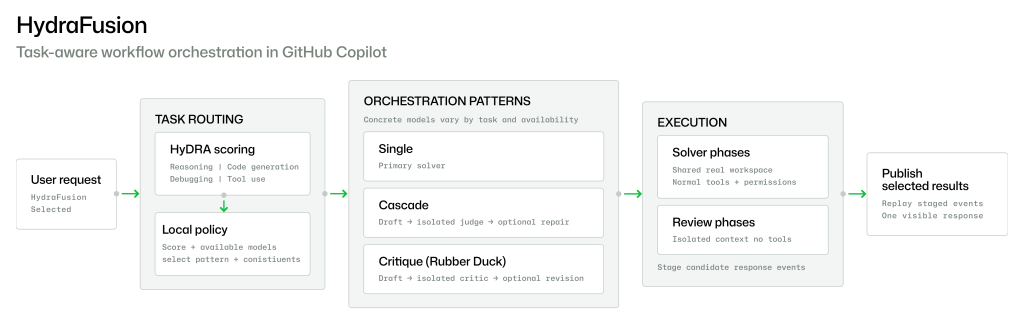
GitHub introduces HydraFusion, a research preview that dynamically orchestrates multiple models for coding tasks, optimizing for quality, cost, and latency. This runtime orchestration system leverages a selection of execution patterns to deliver frontier-level intelligence, reducing costs by up to 67% compared to models like Claude Opus 5.
From GitHub blog: AI & ML
Agents2 min read
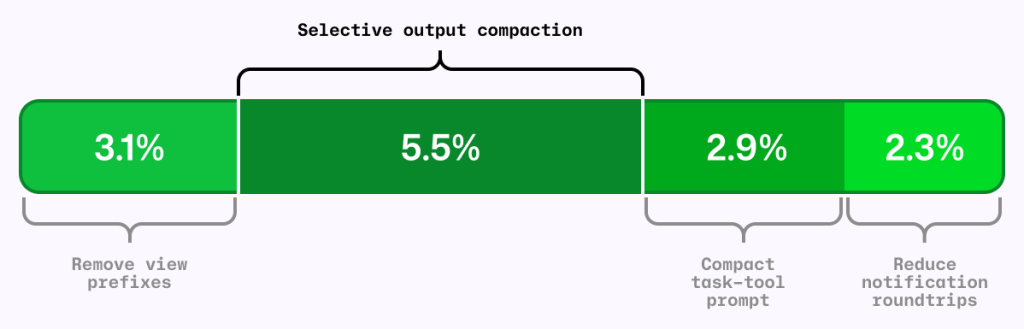
GitHub Copilot’s improvements focus on reducing unnecessary context and formatting, rather than simply minimizing token usage. This approach, validated through agentic coding benchmarks and controlled experiments, delivers cost savings without sacrificing task quality.
From GitHub blog: AI & ML
Agents2 min read
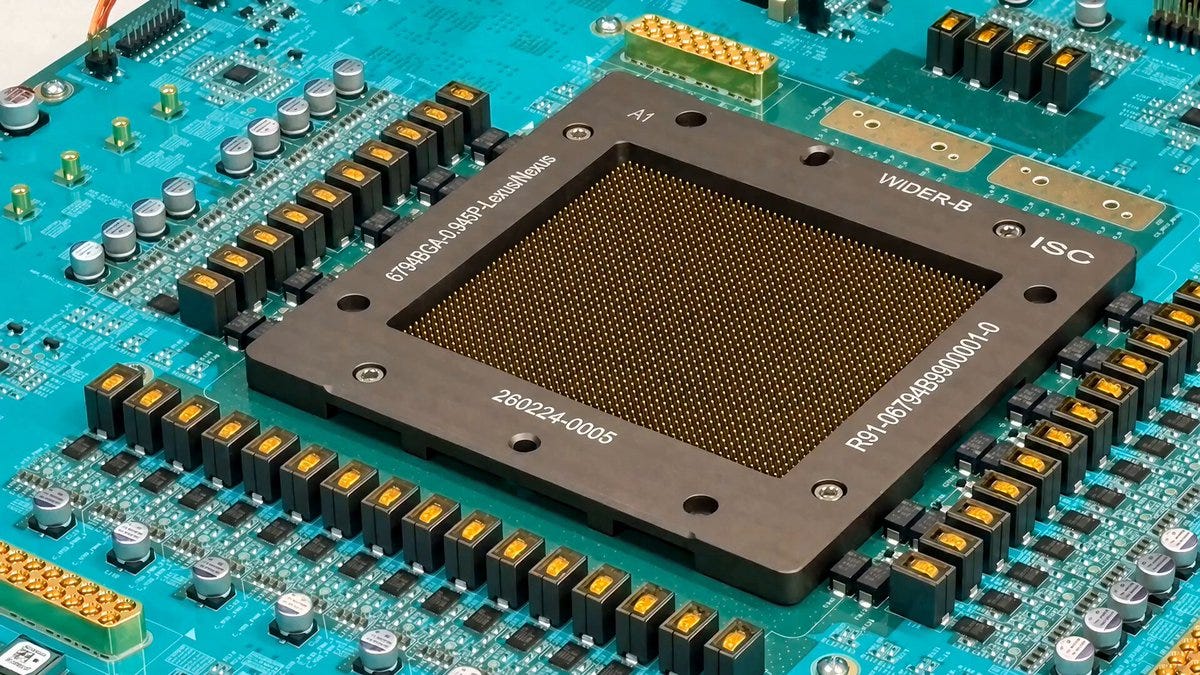
OpenAI’s Jalapeño inference chip delivers significantly improved performance and lower latency compared to NVIDIA GB200/GB300 systems, marking a shift in inference economics and highlighting the importance of system-level optimization.
From Latent Space
LLMs1 min read
We ran 900 DeepSWE rollouts on DeepSeek-V4 Flash and GPT-5.6 Luna. Luna leads pass@1 by 14 points; DeepSeek delivers 4.8x the solves per dollar.
From Together AI blog
Posts are drafted from public feeds by models OpenSmartRoute routes to - the same router, skill and metering customers use - and always link to the original source. Corrections: support.