LLMs8 min read
AI Code Volume Up But Productivity Stays Flat
A Harvard study shows AI tools increase code lines but fail to boost completed work due to review bottlenecks.
From InfoQ: AI, ML and data engineering
90 days of the enterprise, pro and team plans free, no card needed. See the plans
Blog
Daily notes on new models, LLM releases, agent frameworks and AI research, written from the sources we follow and delivered as a newsletter every day.
Get the morning and evening issues
Every new post of the day, in one email. Confirmation required.
LLMs8 min read
A Harvard study shows AI tools increase code lines but fail to boost completed work due to review bottlenecks.
From InfoQ: AI, ML and data engineering
AI12 min read
Researchers found Large Language Models frequently answer using search snippets without reading the actual web pages. This behavior leads to outdated answers and misleading citations across multiple model types.
From Unite.AI
Photo: Yan Krukau
Mirror Particle raises capital to create an AI engine that simulates changing human motivations. The company rejects large language models in favor of a foundation model trained on longitudinal data.
From TechCrunch AI
AI1 min read
One transformer ran candidate generation and ranking in Yandex Music's A/B test without hand-engineered features, lifting likes 11.42%. The post Yandex Introduces Sona: A Single Generative Recommender That Replaces Entire Recommendation ...
From MarkTechPost
AI1 min read
Cantina Security, with Yeta Labs, has released apex-flash-1, an open-weights model trained specifically for vulnerability research. It is a reinforcement learning fine-tune of Z.ai’s GLM-5.3-Flash, released on Hugging Face under the MIT ...
From MarkTechPost
AI10 min read
Prime Intellect introduced Prime Inference, a platform for serving open-source models with serverless endpoints and dedicated GPU capacity.
From MarkTechPost
Agents9 min read
Amazon SageMaker AI now supports fine-tuning search agents using multi-turn reinforcement learning, improving retrieval quality and reliability with minimal setup.
From AWS machine learning blog
AI2 min read
In this comprehensive coding guide, we explore Google Research's Kauldron—a JAX training library optimized for research velocity and modularity. Learn how konfig turns experiments into plain dictionaries, kontext wires components via str...
From MarkTechPost
Research1 min read
Recent autonomous machine learning engineering (MLE) agents have made significant progress on public leaderboards. Often motivated by progress stagnation over long-horizon cycles and limited Large Language Model (LLM) primitives, modern ...
From Apple machine learning research
AI1 min read
OpenAI released GPT-6.1 Sol on September 29, 2026, an upgrade to GPT-6 Sol. It reaches near-Astra results on agentic coding, computer use and professional work at one-fifth of Astra's token prices. It costs $2 input and $10 output per mi...
From MarkTechPost
Research2 min read
Google DeepMind announced Gemini 4 Argon, a new AI model with a 1 million token limit, designed for complex workflows in coding, finance, legal, and cybersecurity.
From Google DeepMind blog
Research1 min read
Controlling the output of Large Language Models (LLMs) is a central challenge for their reliable deployment, yet a clear understanding of the involved trade-offs remains elusive. Current approaches to conditioning are often evaluated wit...
From Apple machine learning research
AI1 min read
Anthropic has released Claude Sonnet 5.5, the second model in its Claude 5.5 family. It scores 70.6% on Terminal-Bench 4.0 and lands within 2 points of Opus 5.5 on GDPval-AA. It also generates output 30%+ faster than Sonnet 5 and keeps t...
From MarkTechPost
AI2 min read
Jev is TypeSafe AI’s first model that makes typed decisions with probabilities. It is faster and cheaper than some large language models for small judgments.
From MarkTechPost
Agents2 min read
Jev is a new decision model that is faster and cheaper than traditional large language models. LangGraph helps build reliable AI workflows.
From LangChain blog
Agents2 min read
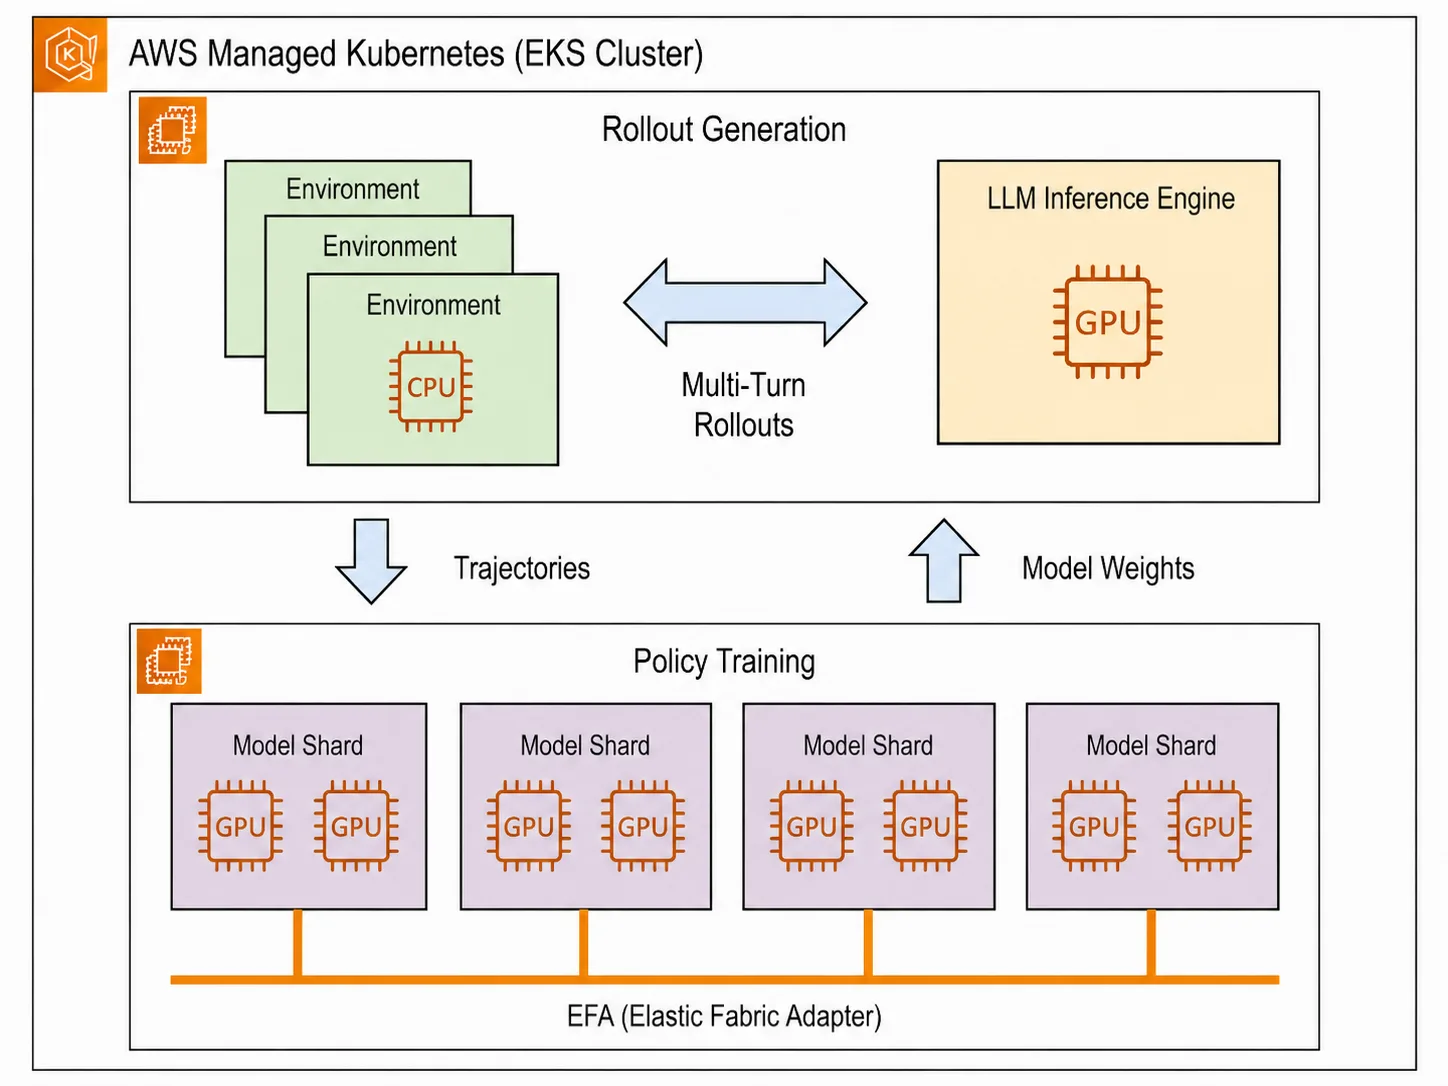
Amazon EKS, Elastic Fabric Adapter, and DeepEP boost large-scale MoE reinforcement learning training by 40% throughput.
From AWS machine learning blog
AI1 min read
Perplexity Research published a new post-training study. It trains a model inside Perplexity Computer on real user sessions, including failed ones. The method pairs rejection sampling fine-tuning with hint-guided self-distillation. In a ...
From MarkTechPost
AI1 min read
BottleCap AI has released ThinkingCap-Qwen3.8-27B, a fine-tune of Qwen3.8-27B that spends 37.2% fewer thinking tokens across 12 benchmarks. Macro accuracy moves from 86.65% to 85.79%, and long-context AA-LCR improves by 2.25pp. The model...
From MarkTechPost
AI1 min read
OpenAI has released GPT-6 Sol and GPT-6 Luna, 2 lower-cost models trained with methods similar to GPT-6 Astra. Sol costs $2/$10 and Luna $0.10/$0.50 per 1M tokens. Both are available now in the API, ChatGPT Work and Codex. They come with...
From MarkTechPost
Posts are drafted from public feeds by models OpenSmartRoute routes to - the same router, skill and metering customers use - and always link to the original source. Corrections: support.
Archive (100)