AI1 min read
Layoffs get a $75 ticket to TechCrunch Disrupt 2026 Expo+
People laid off can buy a $75 Expo+ Pass for TechCrunch Disrupt 2026. The offer is limited to 100 passes or until October 13.
From TechCrunch AI
90 days of the enterprise, pro and team plans free, no card needed. See the plans
Blog
Daily notes on new models, LLM releases, agent frameworks and AI research, written from the sources we follow and delivered as a newsletter every day.
Get the morning and evening issues
Every new post of the day, in one email. Confirmation required.
AI1 min read
People laid off can buy a $75 Expo+ Pass for TechCrunch Disrupt 2026. The offer is limited to 100 passes or until October 13.
From TechCrunch AI
LLMs1 min read
A GPU cluster can pass every health check and still fail to run an AI workload. Even when every GPU, network link, and pod reports healthy, a 512-GPU training...
From NVIDIA technical blog
Photo: Yan Krukau
Kubernetes manages what runs on your nodes. Managing the nodes themselves is the challenge: kernel settings, system packages, storage layouts, security agents,...
From NVIDIA technical blog
LLMs1 min read
AI factories are power-limited systems that deliver maximum value when fully optimized. GPU workload placement is a key optimization. Poor workload placement...
From NVIDIA technical blog
LLMs1 min read
The compute and memory demands of generative AI increasingly exceed what a single GPU can provide. NVIDIA TensorRT multi-device inference is a new capability...
From NVIDIA technical blog
AI1 min read
Ticket prices for TechCrunch Disrupt 2026 increase after September 25. Register early to save money and secure your spot at the event.
From TechCrunch AI
AI1 min read
Table reservations end at 11:59 p.m. PT on September 18, 2026. The Expo Hall opens October 13 in San Francisco for three days.
From TechCrunch AI
Agents1 min read
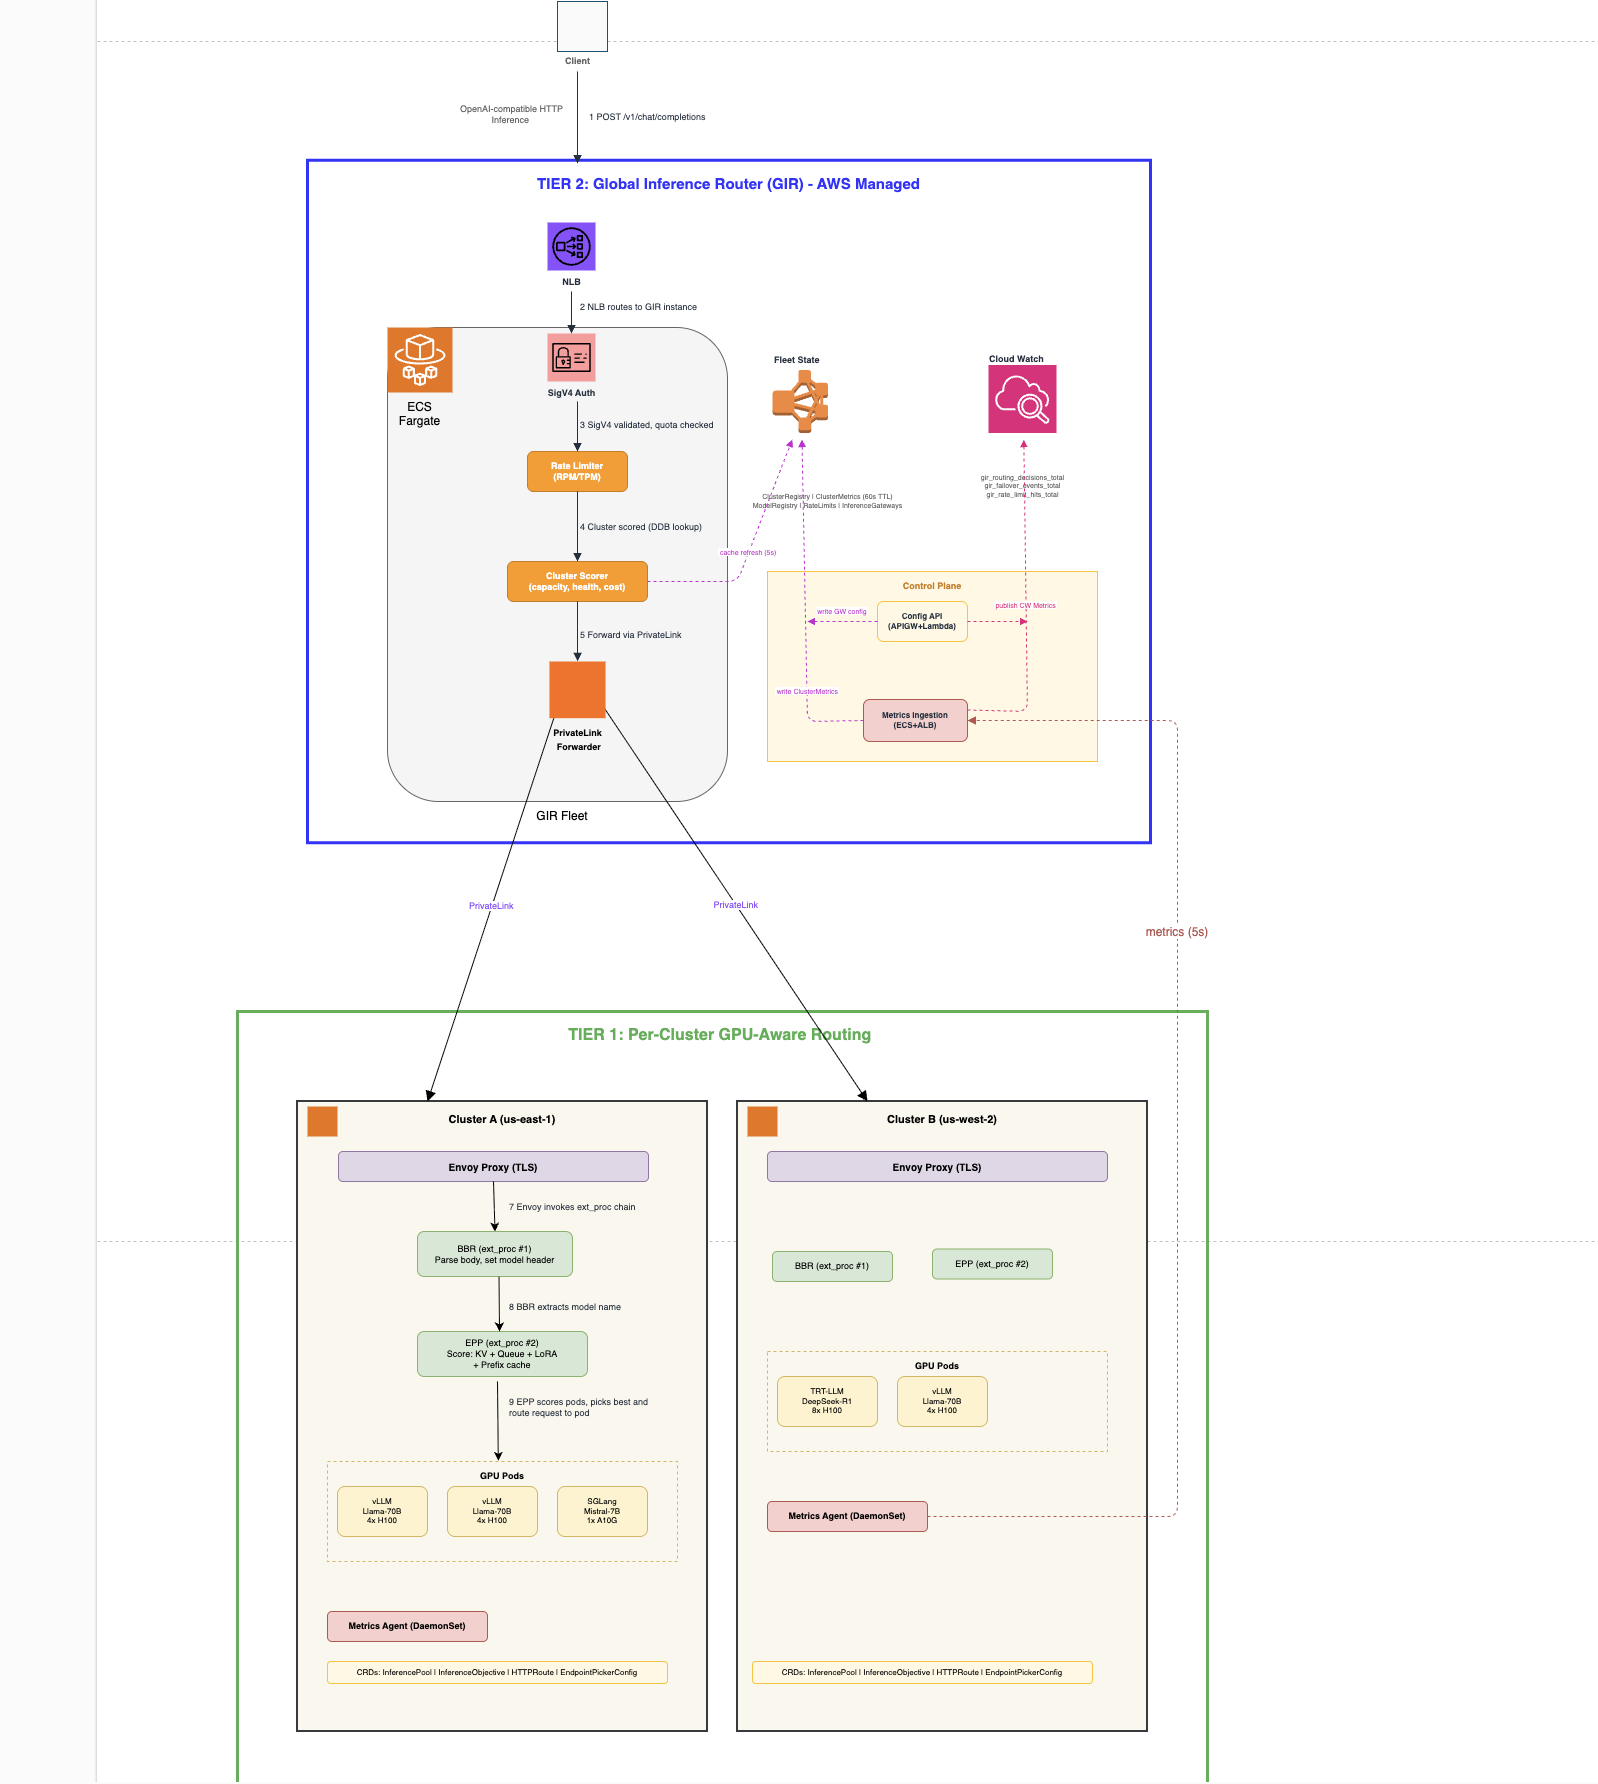
Amazon SageMaker HyperPod Inference Gateway is a Kubernetes-native, GPU-aware routing add-on for Amazon EKS. It uses real-time GPU signals to send each inference request to the best-suited pod, cutting first-token latency by up to 82% wi...
From AWS machine learning blog
AI1 min read
Microsoft released TauGrid to simplify running AI workloads on Kubernetes. It bundles five platform tools into one Helm install.
From MarkTechPost
Agents1 min read
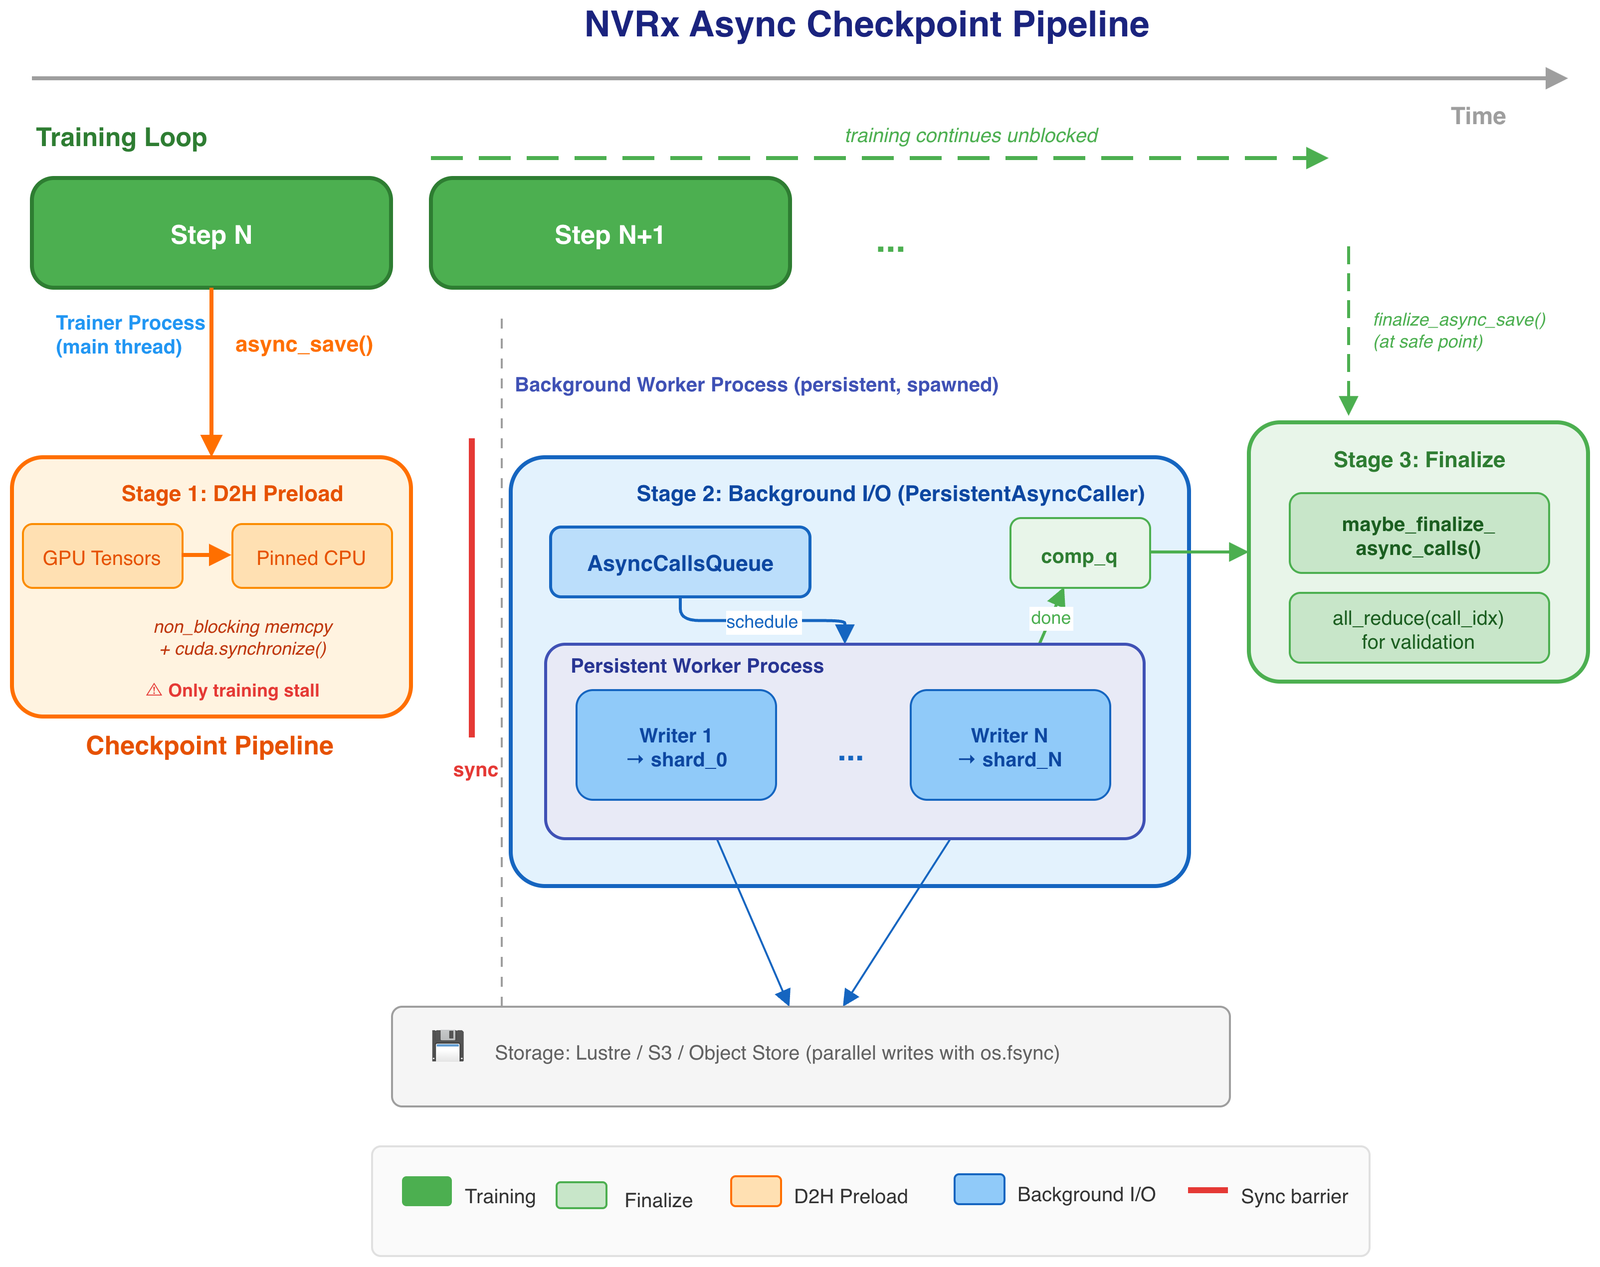
NVIDIA Resiliency Extension (NVRx) prevents GPU faults from stopping PyTorch training on Amazon EKS. Async checkpointing and automatic restarts save hours of wasted compute time.
From AWS machine learning blog
AI1 min read
Anthropic CEO Dario Amodei wants outside groups to audit AI safety. Experts say fixing network security basics is more effective.
From TechCrunch AI
AI1 min read
Registration for exhibit tables closes on September 18 at TechCrunch Disrupt 2026. The event runs from October 13 to 15 in San Francisco.
From TechCrunch AI
LLMs1 min read
Researchers propose inference networks that route queries to lower-cost models first, activating expensive experts only when confidence drops below a specific threshold.
From arXiv cs.CL
LLMs1 min read
For operators of large-scale AI factories, maximizing continuous output is essential for productivity. In massive-scale AI training, every GPU in the cluster...
From NVIDIA technical blog
AI1 min read
Agent-net, the team building an agent-to-agent marketplace where AI agents discover, trust, and pay each other, has released Webagent, an open source harness for standing up public-facing business agents. So, basically you give it your w...
From MarkTechPost
LLMs1 min read
arXiv:2609.13389v1 Announce Type: new Abstract: Mapping textual specifications into formal representations is essential for ensuring the correctness of protocol designs and implementations. LLM-generated mappings, used for networking sec...
From arXiv cs.CL
Research1 min read
arXiv:2609.13580v1 Announce Type: new Abstract: Large language models (LLMs) have demonstrated strong capabilities across a wide range of natural language processing tasks. However, conventional fine-tuning typically relies on centralize...
From arXiv cs.AI
LLMs1 min read
Federated learning (FL) projects often begin with a straightforward setup: one server, a few clients, and one dataset at each site. As those projects grow, the...
From NVIDIA technical blog
AI1 min read
Sakana AI researchers introduced PC-ALM, a layer-local training method for deep networks that achieves performance comparable to backpropagation up to 1000 layers on MNIST. The research provides a JAX implementation for experimentation and benchmarking.
From MarkTechPost
Posts are drafted from public feeds by models OpenSmartRoute routes to - the same router, skill and metering customers use - and always link to the original source. Corrections: support.
Archive (95)