Platform teams usually run many separate systems for GPU AI.
They manage queues, orchestration, health checks, and dashboards individually.
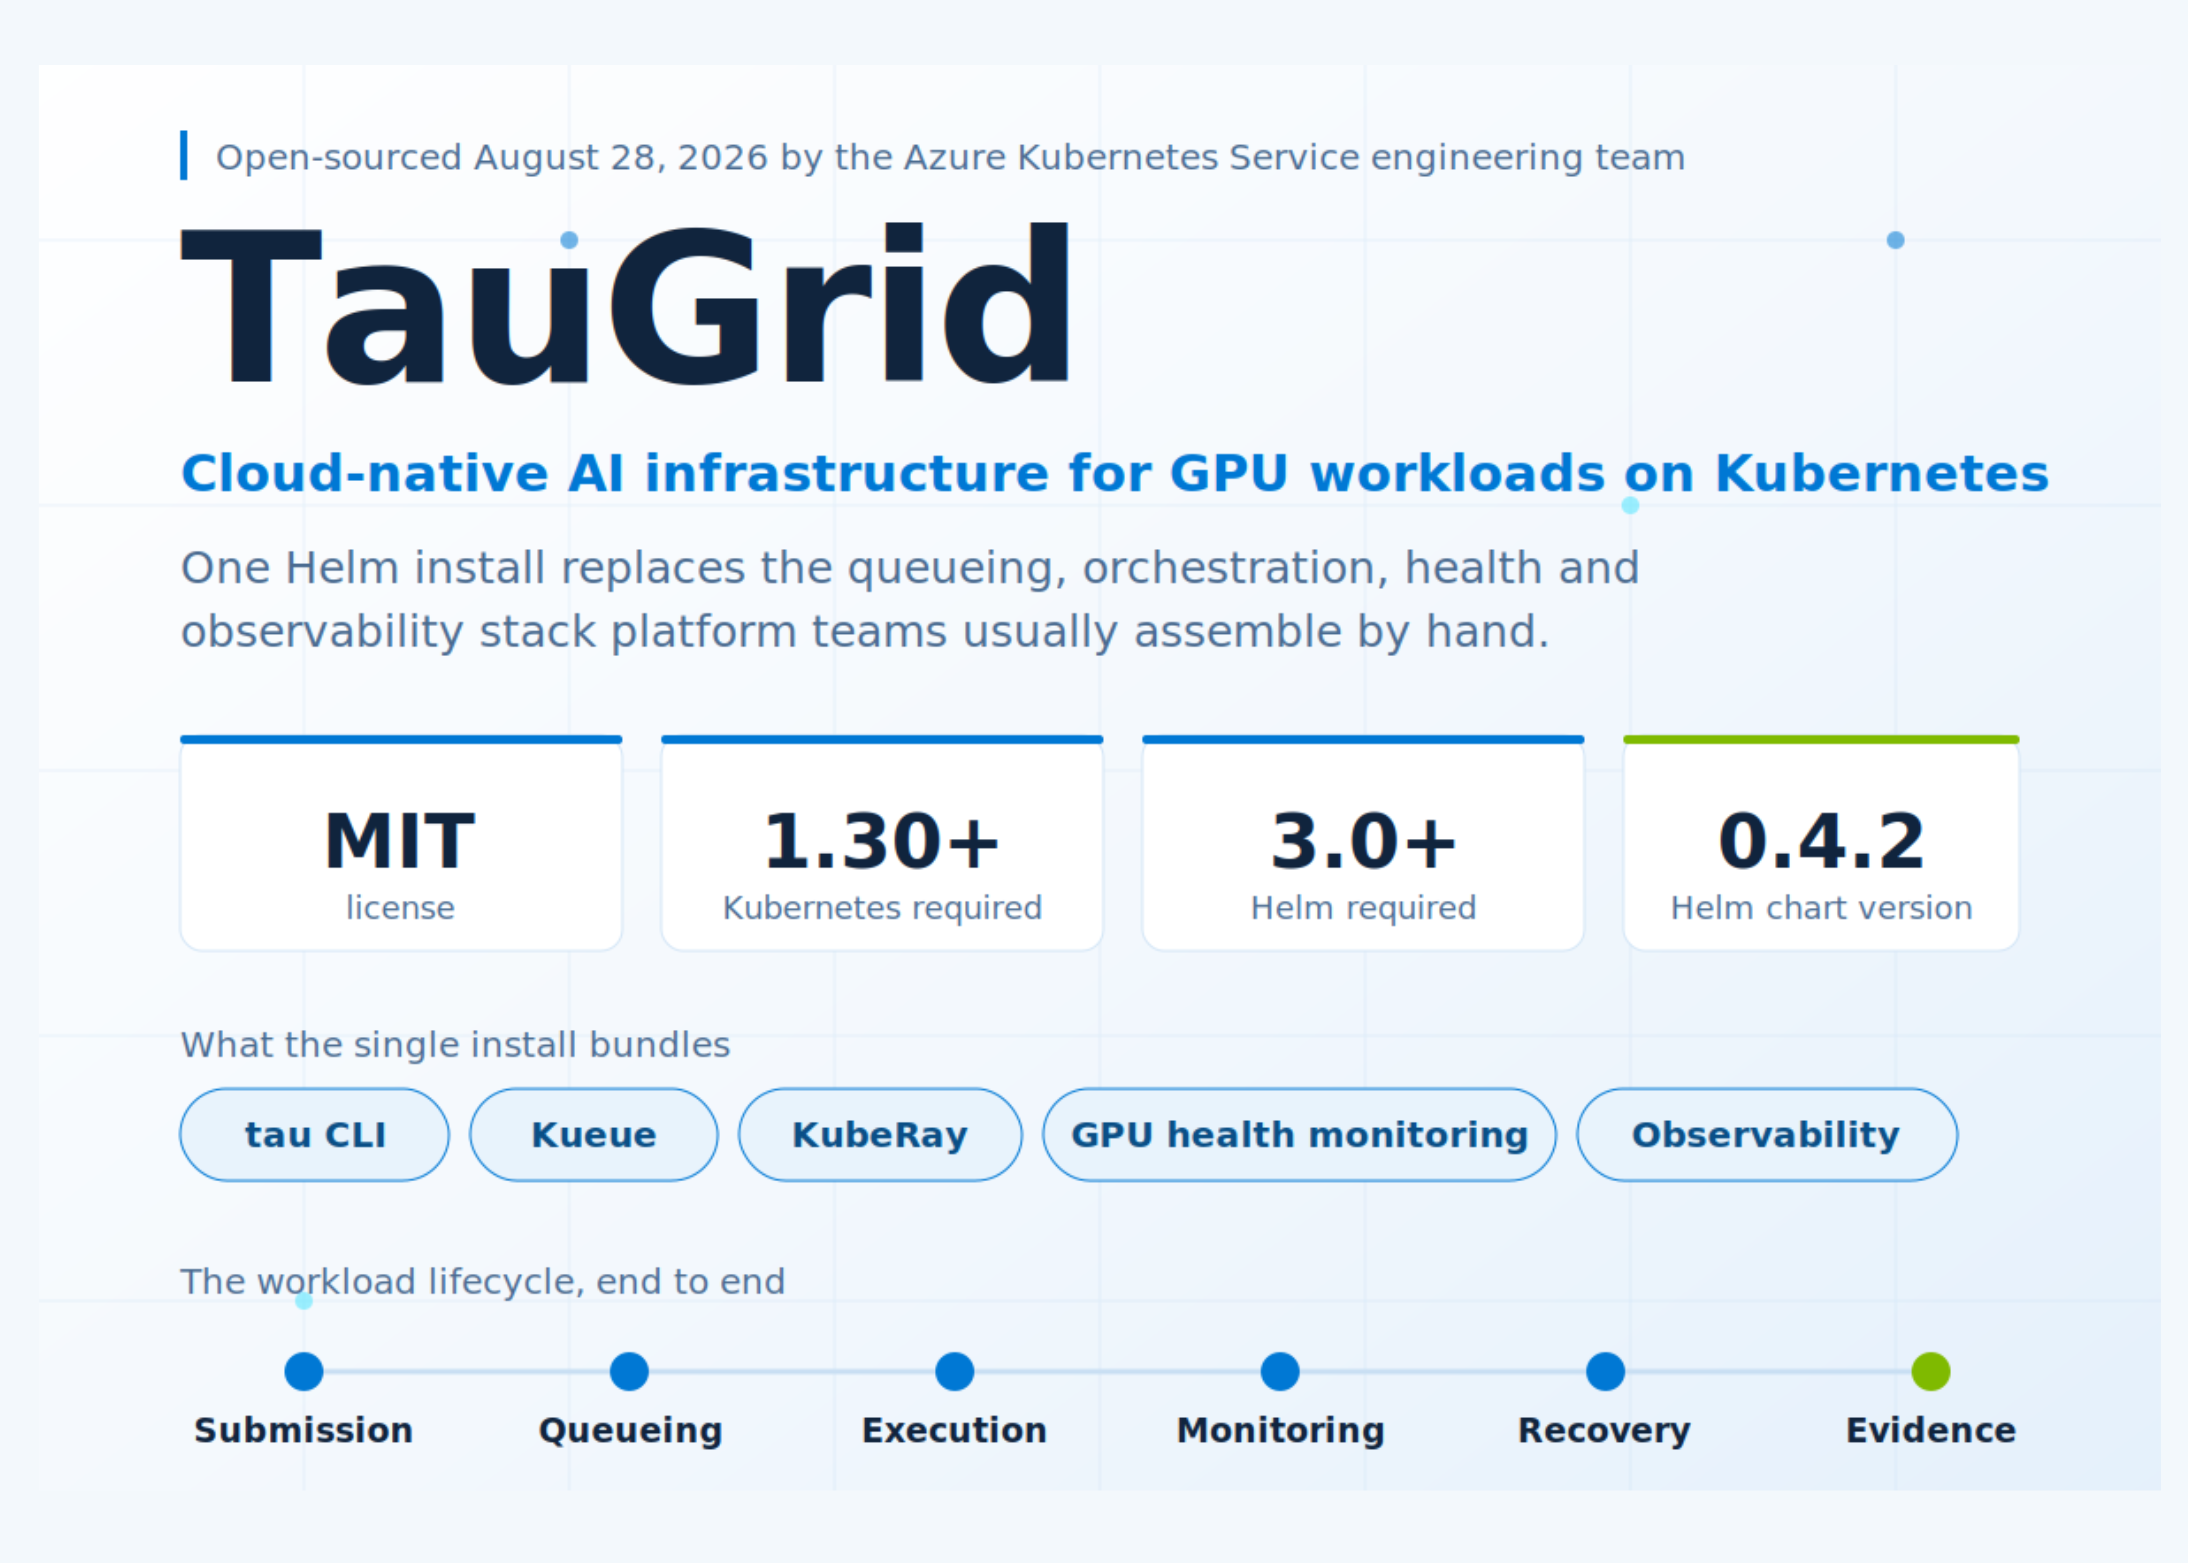
TauGrid combines these five components into one Helm chart.
The stack includes the tau CLI, Kueue queueing, KubeRay, GPU monitoring, and observability.
How it Works
A workload description lives in a tau.yaml file.
The system resolves policies and submits jobs through Kueue.
Six stages cover submission, execution, recovery, and evidence capture.
Evidence records ensure runs remain reproducible and auditable later.
Installation and Safety
Installation pulls images directly from Microsoft Container Registry.
The codebase uses Go for the core controller and CLI.
TauGrid sends no telemetry by default unless configured.
Some features like Azure Data Explorer observability remain specific to Azure.
Why it matters
One Helm install replaces complex manual integrations for teams.
It supports any Kubernetes 1.30+ cluster with GPU nodes.
Teams can deploy without configuring Kubernetes directly through the CLI.