AI16 min read
Anthropic stops hiring juniors as AI agents work six times more hours
Anthropic cut junior hires from 27% to 9% while its AI agents logged six times the work hours of humans since early 2025.
From The Decoder
90 days of the enterprise, pro and team plans free, no card needed. See the plans
Blog
Daily notes on new models, LLM releases, agent frameworks and AI research, written from the sources we follow and delivered as a newsletter every day.
Get the morning and evening issues
Every new post of the day, in one email. Confirmation required.
AI16 min read
Anthropic cut junior hires from 27% to 9% while its AI agents logged six times the work hours of humans since early 2025.
From The Decoder
Agents2 min read
Google partnered with Speakeasy to open source an OpenAPI code generation suite. This move follows a previous provider's shutdown and aims to reduce platform risk.
From Google AI developers blog
Photo: Yan Krukau
Agents1 min read
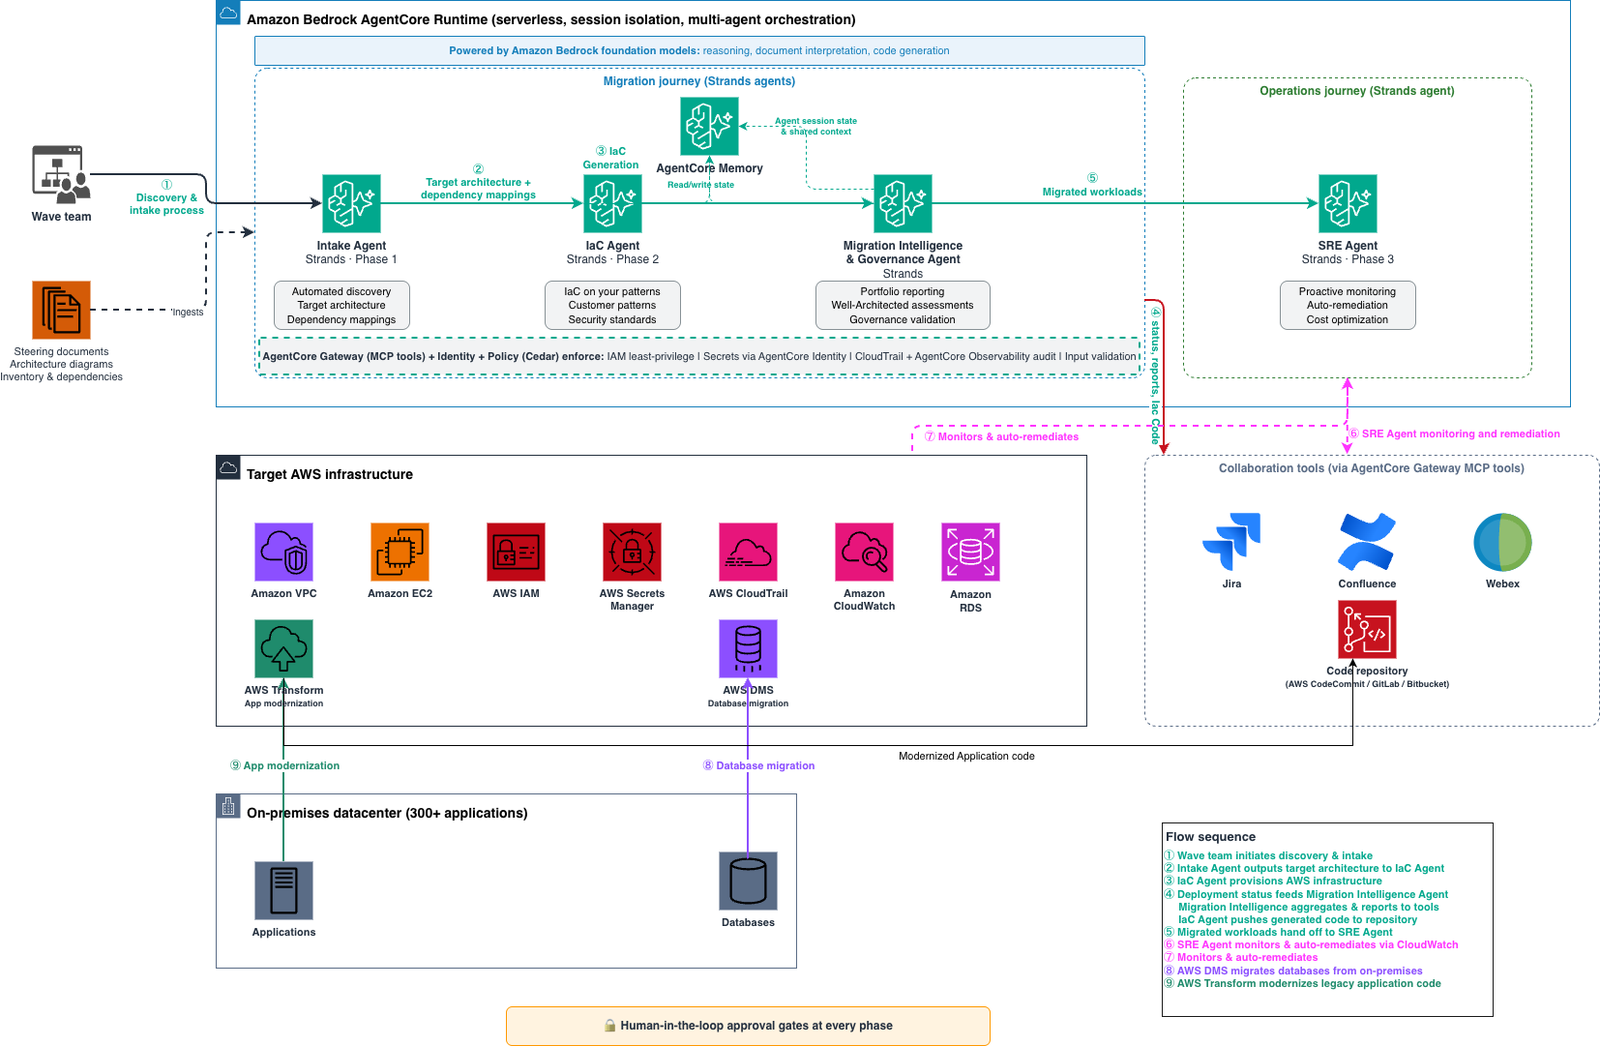
Learn how AWS Professional Services uses a multi-agent framework built on Amazon Bedrock AgentCore to automate enterprise cloud migrations end to end. Purpose-built AI agents handle discovery, infrastructure as code generation, portfolio...
From AWS machine learning blog
Agents2 min read
GPT-6.1 Sol is now generally available on Amazon Bedrock. It offers stronger reasoning for coding, documents, and workflows at lower cost.
From AWS machine learning blog
AI4 min read
AI is accelerating software development at an unprecedented pace. But as code generation scales, so do the challenges of securing the code, especially emerging AI-based vulnerability exploitations. To meet these challenges, the Google AI...
From Google Cloud AI blog
Research1 min read
A new method, belief-shift branching, uses model belief divergence to strategically place forks in tree-structured reinforcement learning chains. This approach, validated against multiple models and benchmarks, achieves significant performance gains, particularly in code generation tasks.
From arXiv cs.AI
Research1 min read
PerfReasoning assesses LLMs as performance reasoners and code generators, with models achieving up to 90% accuracy on reasoning tasks. Construction of models remains challenging, especially for smaller configurations.
From arXiv cs.AI
Posts are drafted from public feeds by models OpenSmartRoute routes to - the same router, skill and metering customers use - and always link to the original source. Corrections: support.
Archive (100)