LLMs1 min read
ViCo: Visual-oriented Coding for Chart Replication with Self-Reflection
A new framework uses an 8B model to generate charts matching human visual standards through iterative self-reflection and reinforcement learning.
From arXiv cs.CL
90 days of the enterprise, pro and team plans free, no card needed. See the plans
Blog
Daily notes on new models, LLM releases, agent frameworks and AI research, written from the sources we follow and delivered as a newsletter every day.
Get the morning and evening issues
Every new post of the day, in one email. Confirmation required.
LLMs1 min read
A new framework uses an 8B model to generate charts matching human visual standards through iterative self-reflection and reinforcement learning.
From arXiv cs.CL
LLMs1 min read
A new study maps 22 LLMs across closed-source and open-source categories using self-reported personality traits projected into a six-dimensional archetype space.
From arXiv cs.CL
Photo: Yan Krukau
LLMs2 min read
A study of ten frontier models using ten extrinsic audit instruments found that while all tools detected bias, their rankings were statistically indistinguishable from chance.
From arXiv cs.CL
LLMs2 min read
A new study finds few-shot prompting effects vary by task and are driven by demonstration content rather than prompt length. Replacing demonstrations with random text isolates the impact of representation shifts caused by content.
From arXiv cs.CL
LLMs2 min read
arXiv:2609.16340v1 Announce Type: new Abstract: Machine translation systems are periodically upgraded to stronger models, but the available preference signal is human post-edits of an older system's outputs, which the newer model may alr...
From arXiv cs.CL
LLMs2 min read
Research shows ordinary typos rotate hidden state vectors by 43 to 56 degrees, causing prompt injection probes to drop true positive rates by up to 12 percentage points.
From arXiv cs.CL
LLMs2 min read
A new paradigm named State of Thought (SoT) uses a compact controller to activate historical reasoning support based on internal model states, improving accuracy while reducing tokens and latency.
From arXiv cs.CL
LLMs1 min read
Researchers propose NarraLite, a framework for multimodal generative recommendation that compresses visual contexts and uses latent reasoning tokens. The system improves narrative coherence in short-form drama continuation while reducing redundant computation.
From arXiv cs.CL
LLMs2 min read
Researchers released NepLEGiT, a ~30 million parameter SLM pre-trained on 4 million tokens of Nepali legal text. The model achieves a perplexity of 1.8 and 82.9% next-token accuracy.
From arXiv cs.CL
LLMs2 min read
Researchers propose inference networks that route queries to lower-cost models first, activating expensive experts only when confidence drops below a specific threshold.
From arXiv cs.CL
LLMs1 min read
Together AI released a playbook to help companies migrate from closed to open source models.
From Together AI blog
LLMs1 min read
Tool: Gemini Live audio Google released Gemini 3.8 Live and 3.8 Live Extended Thinking today - two new speech-to-speech models that are a similar shape to OpenAI's GPT-Live family. I pointed GPT-6 Astra Extra High at the documentation an...
From Simon Willison on LLMs
AI1 min read
Learn how to leverage NVIDIA’s cuDNN Frontend Graph API to build custom kernel fusions, autotuning engine configurations, FP8-style epilogues, scaled dot-product attention, dynamic shapes, and CUDA graph captures. This practical tutorial...
From MarkTechPost
AI1 min read
Google has released Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking, its most advanced live dialogue models to date. The models execute tools and API calls in the background while the conversation keeps flowing, process live visual...
From MarkTechPost
Research1 min read
Algorithms & Theory
From Google Research blog
LLMs1 min read
How can a 30B-parameter model activate only 3B parameters per token, and still use the capacity of the larger model? Nemotron 3.5 Lightning illustrates the...
From NVIDIA technical blog
Agents1 min read
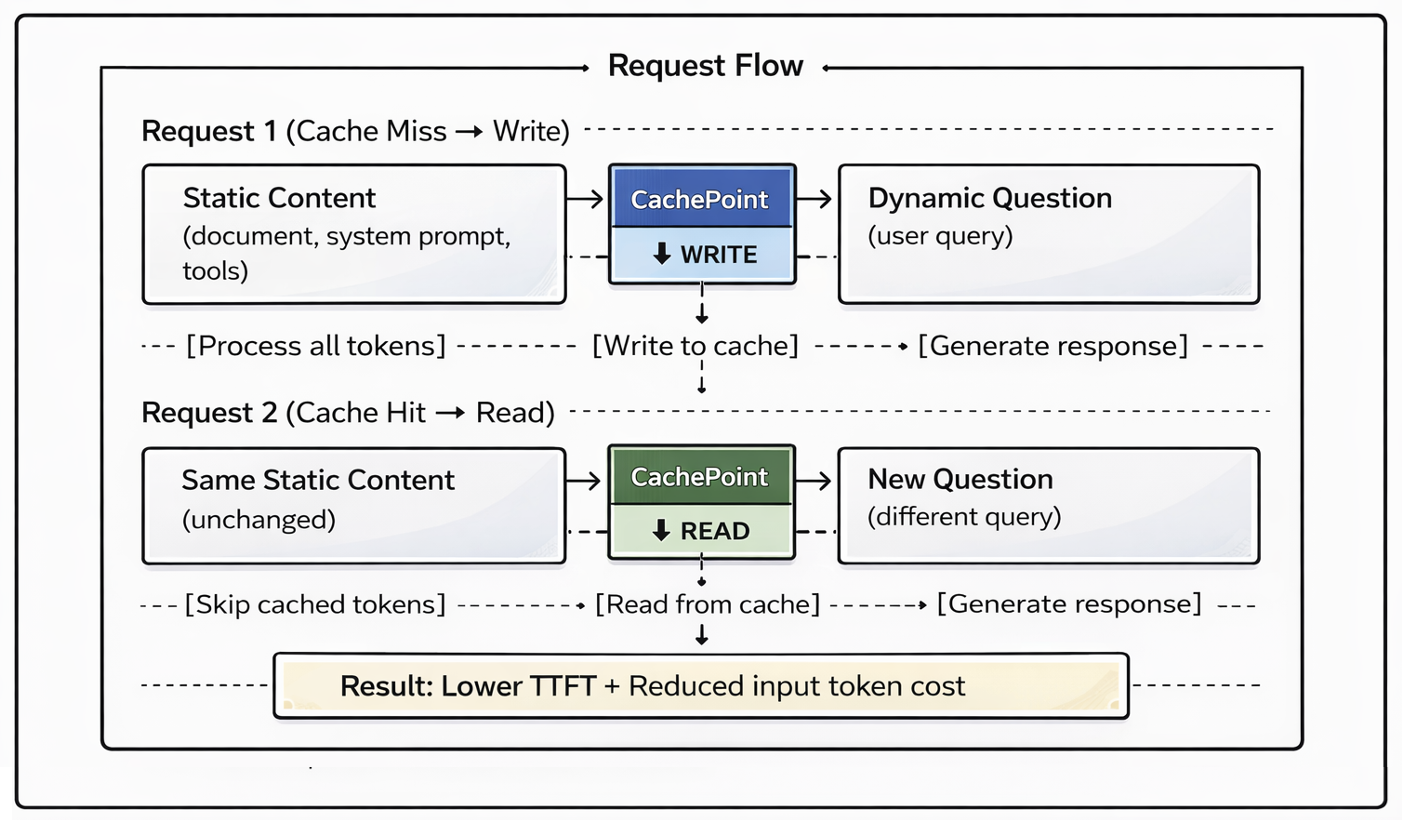
Prompt caching in Amazon Bedrock can cut input token costs by up to 90% when you repeatedly send the same context to foundation models. This post walks through six practical prompt caching scenarios using the Converse API: message conten...
From AWS machine learning blog
Agents1 min read
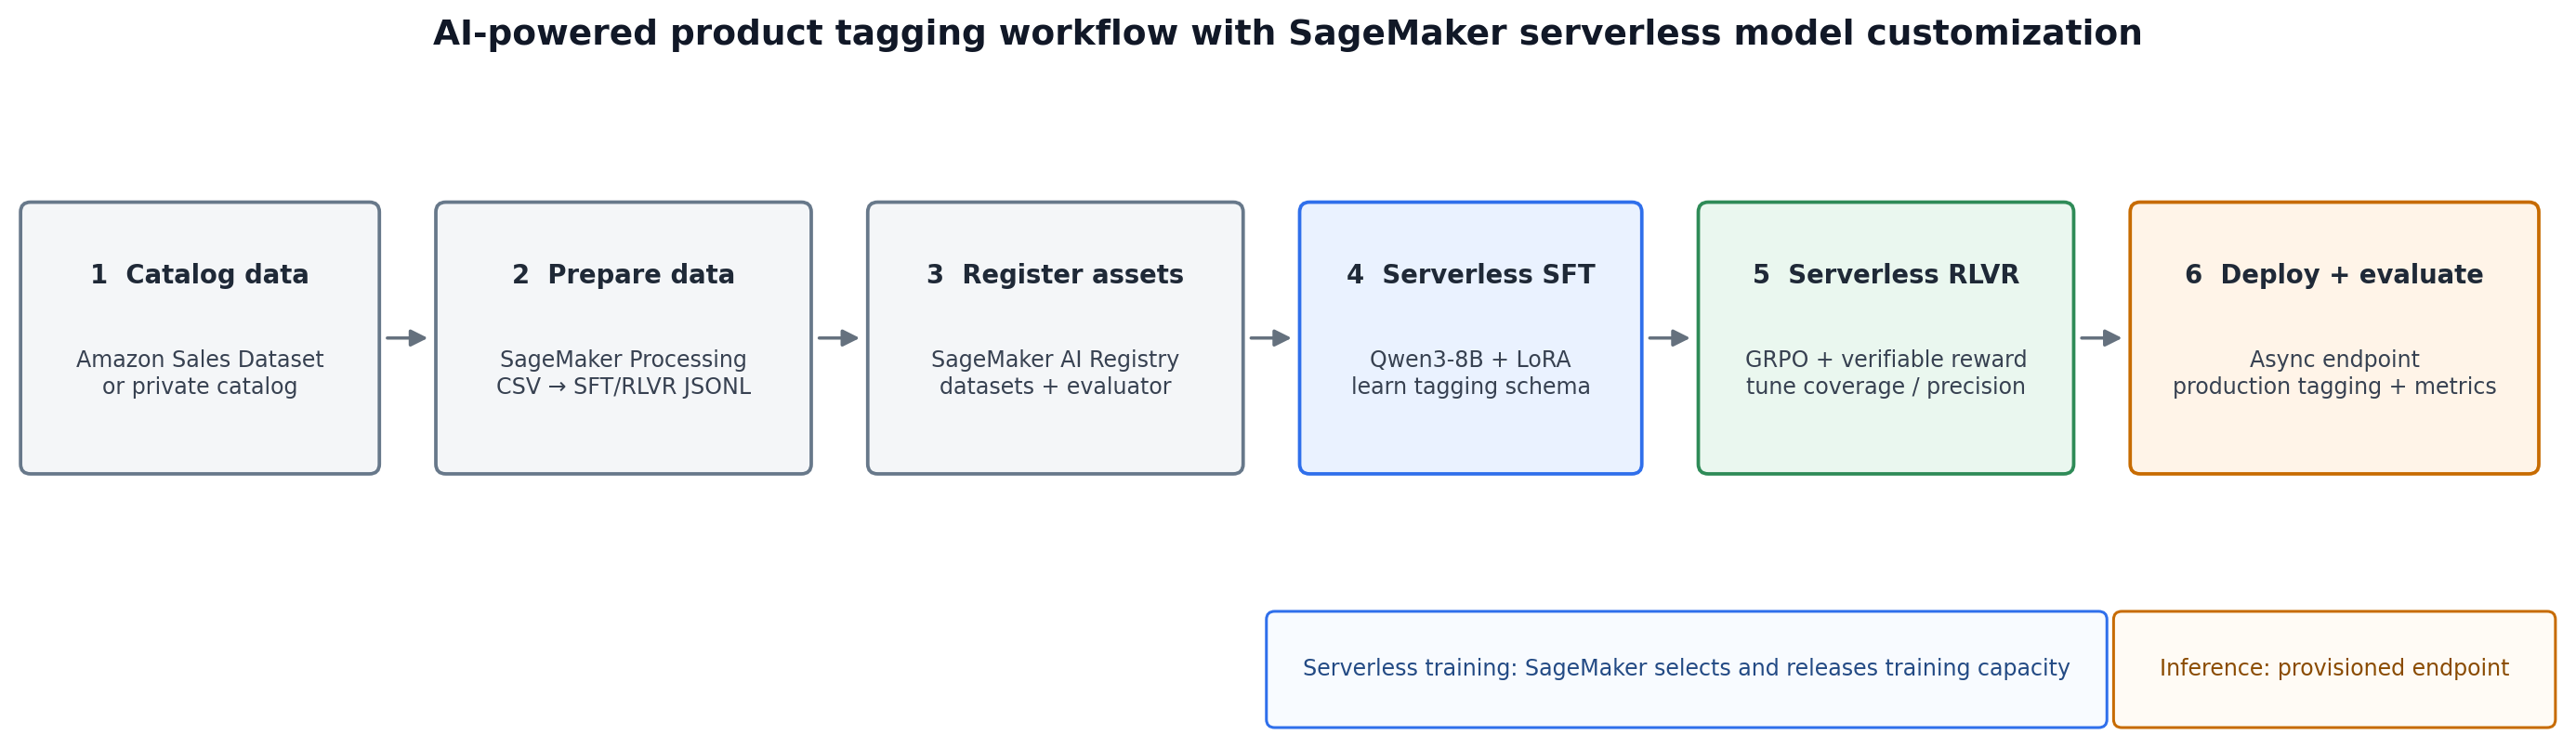
Manually tagging thousands of catalog products is slow and inconsistent. This walkthrough shows how to customize Qwen3-8B with supervised fine-tuning (SFT) and reinforcement learning with verifiable rewards (RLVR) on Amazon SageMaker ser...
From AWS machine learning blog
Models1 min read
B-roll showing diverse environments and people, including a teacher and students in a classroom and a patient with a doctor
From Google AI blog
Posts are drafted from public feeds by models OpenSmartRoute routes to - the same router, skill and metering customers use - and always link to the original source. Corrections: support.
Archive (100)