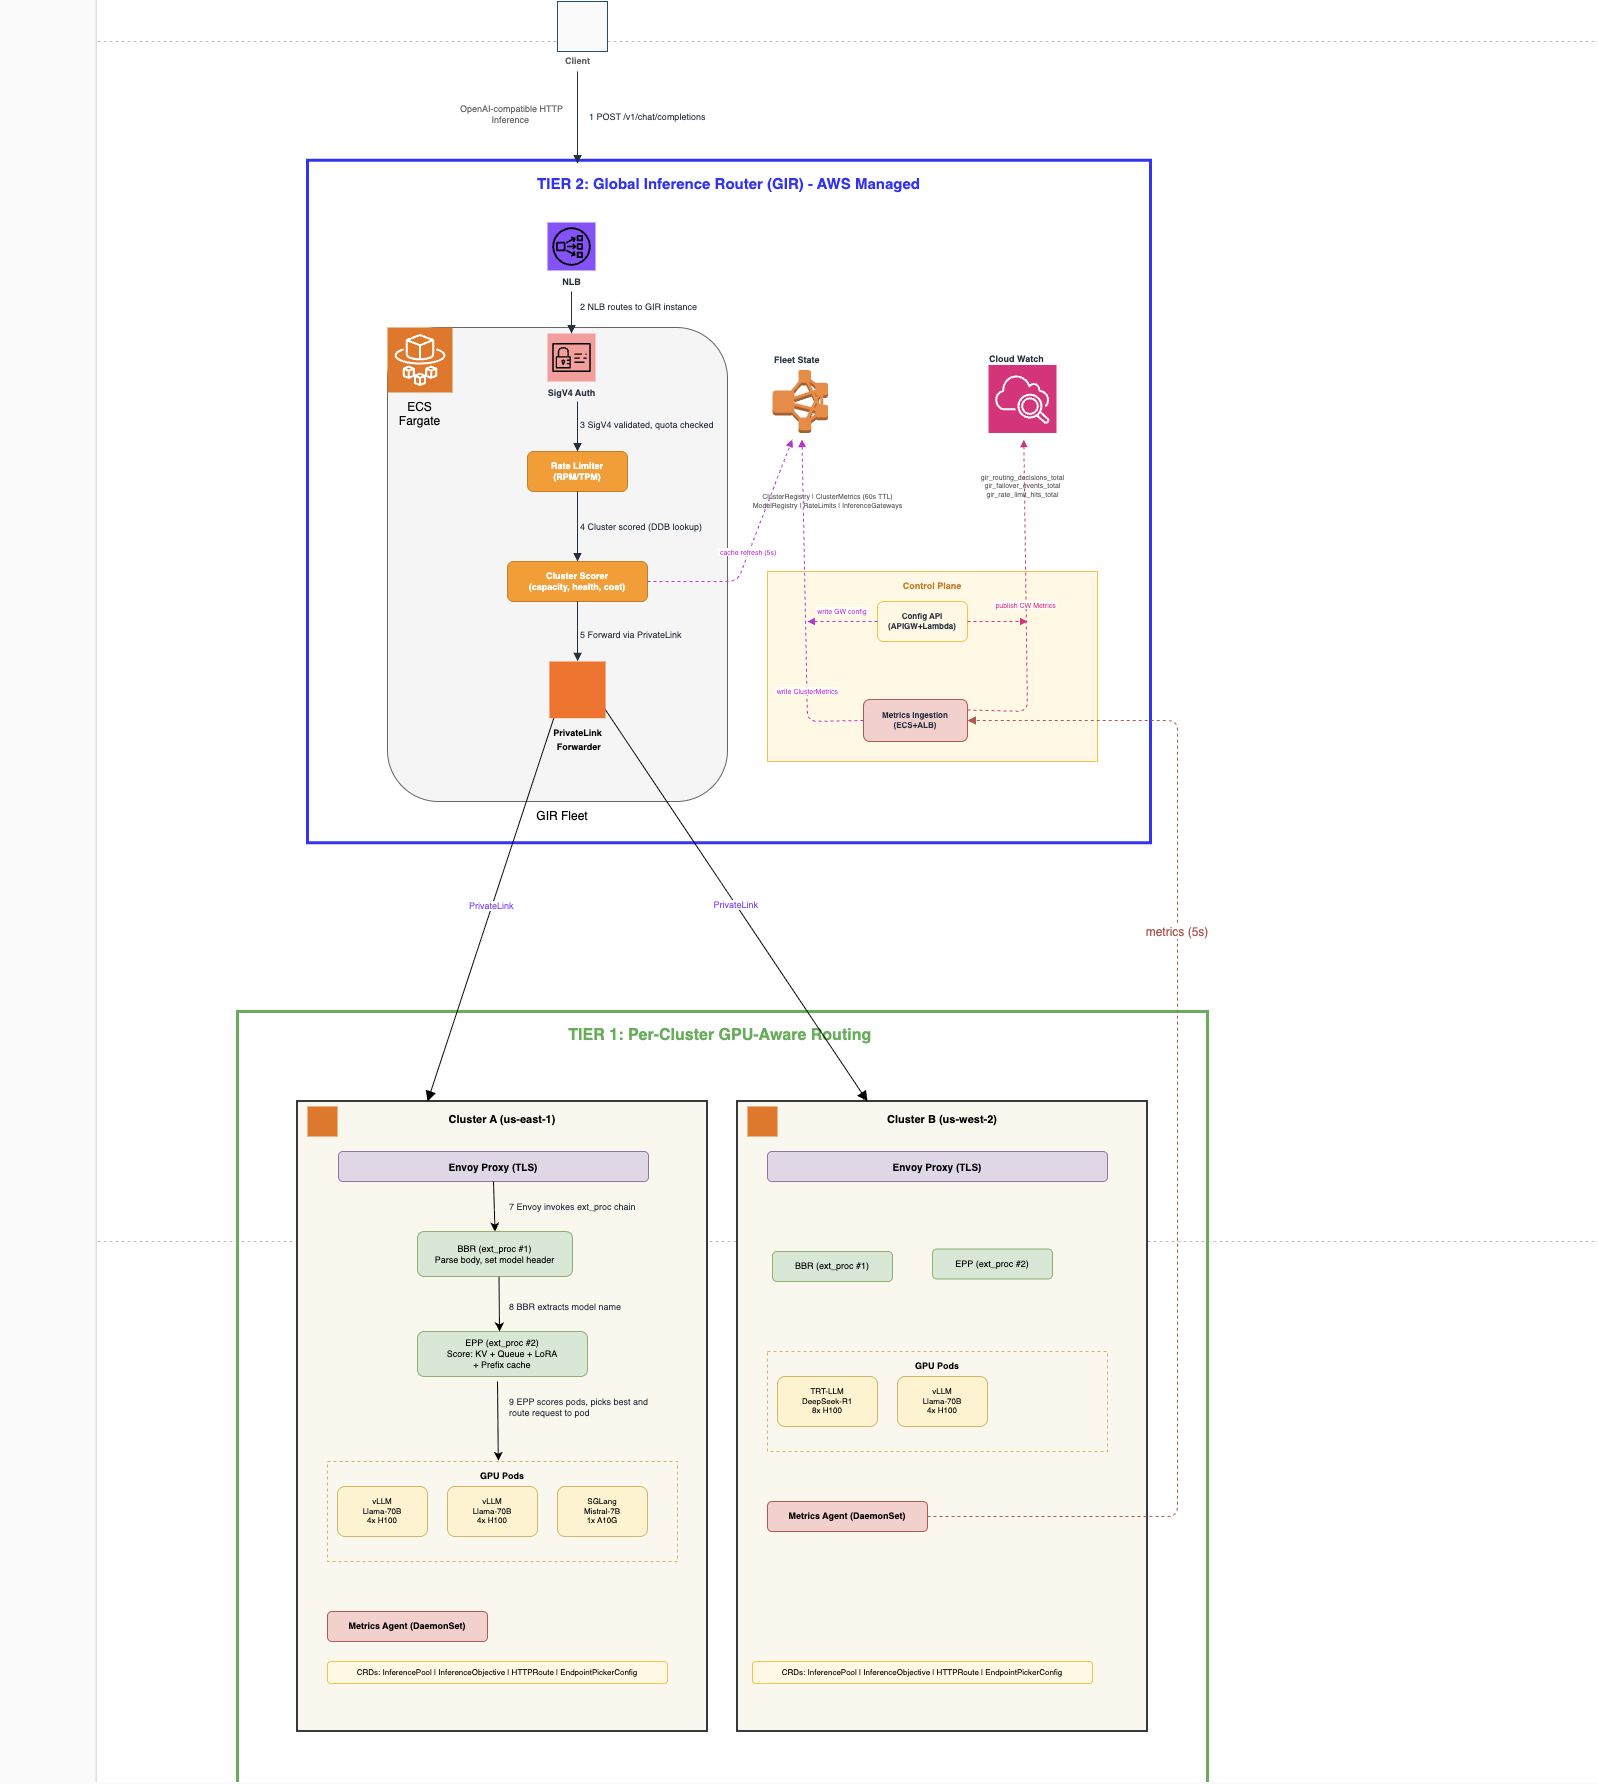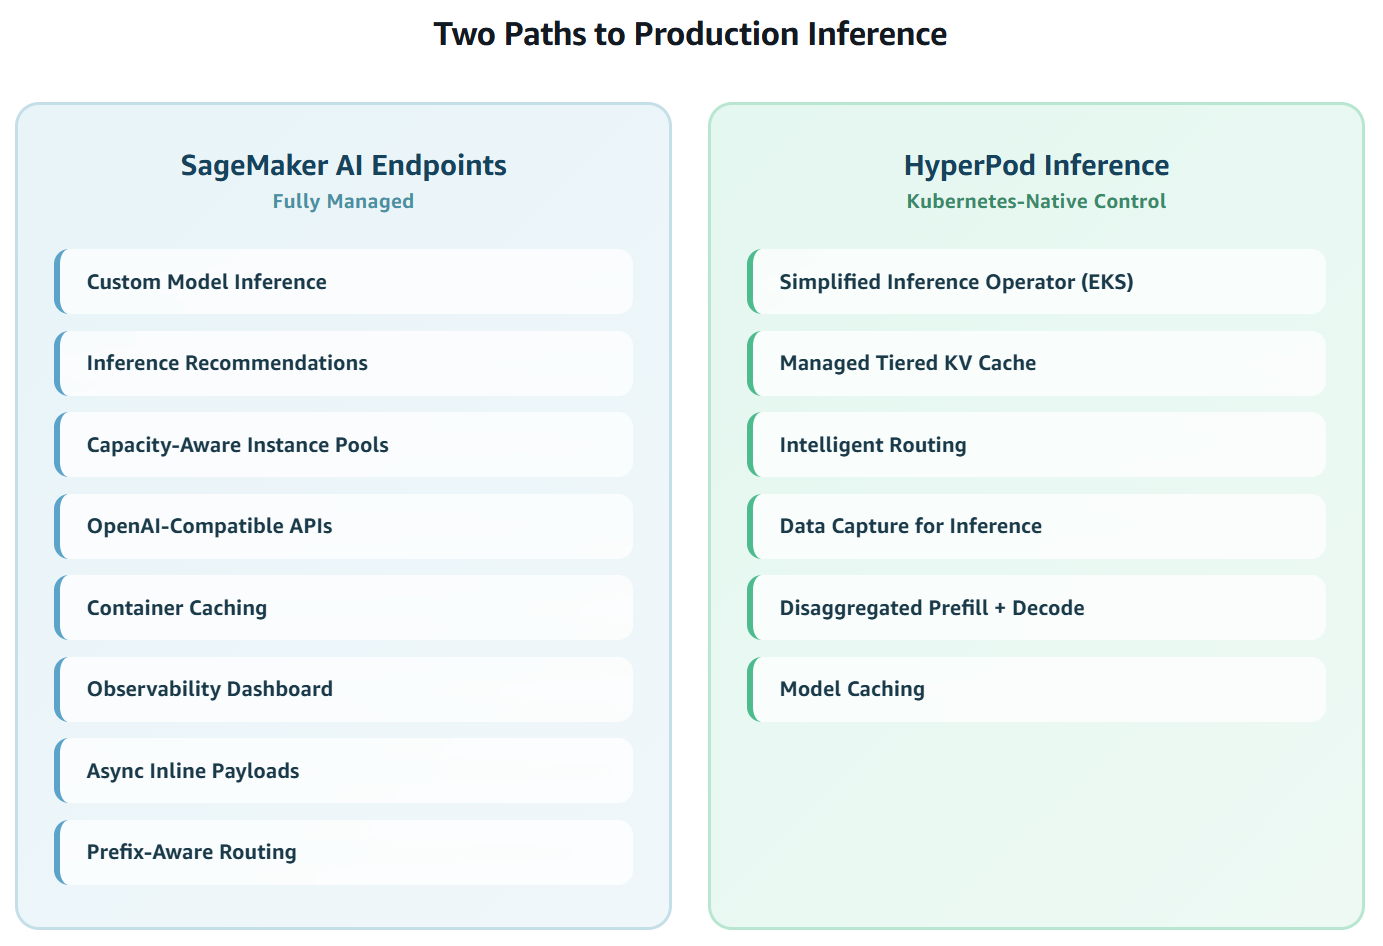
Amazon SageMaker AI shipped 13 inference launches in year-to-date across two deployment paths: fully managed endpoints and Amazon SageMaker HyperPod Inference. This post reviews each launch, from inference recommendations and capacity-aware instance pools to tiered KV caching and disaggregated prefill and decode.
Read the original at AWS machine learning blog: Amazon SageMaker Inference: 2026 year-to-date launches in review