AI1 min read
Google Paused Open Source Bug Bounty Over AI Spam
Google froze its open source bug bounty program after a surge in automated AI submissions. The company paused rewards for finding vulnerabilities in October 2026.
From TechCrunch AI
Blog
Daily notes on new models, LLM releases, agent frameworks and AI research, written from the sources we follow and delivered as a newsletter every day.
Get the morning and evening issues
Every new post of the day, in one email. Confirmation required.
AI1 min read
Google froze its open source bug bounty program after a surge in automated AI submissions. The company paused rewards for finding vulnerabilities in October 2026.
From TechCrunch AI
Research1 min read
The common paradigm of reinforcement learning with verifiable rewards (RLVR) is to let agents make multiple attempts at a task, and optimize towards the successful ones. This becomes problematic in the realms of self-improvement, where t...
From Apple machine learning research
How this blog is made
POST /api/v1/route with execute: true.Photo: Yan Krukau
AI3 min read
Reinforcement learning (RL) has been a keystone of modern LLM post-training, but it demands large training clusters and access to model internals that external customers can't have with proprietary models like Gemini. So here at Google C...
From Google Cloud AI blog
LLMs1 min read
A new pipeline synthesizes 90k multimodal samples to enable scalable Reinforcement Learning with Verifiable Rewards, improving instruction-following by 8.13%.
From arXiv cs.CL
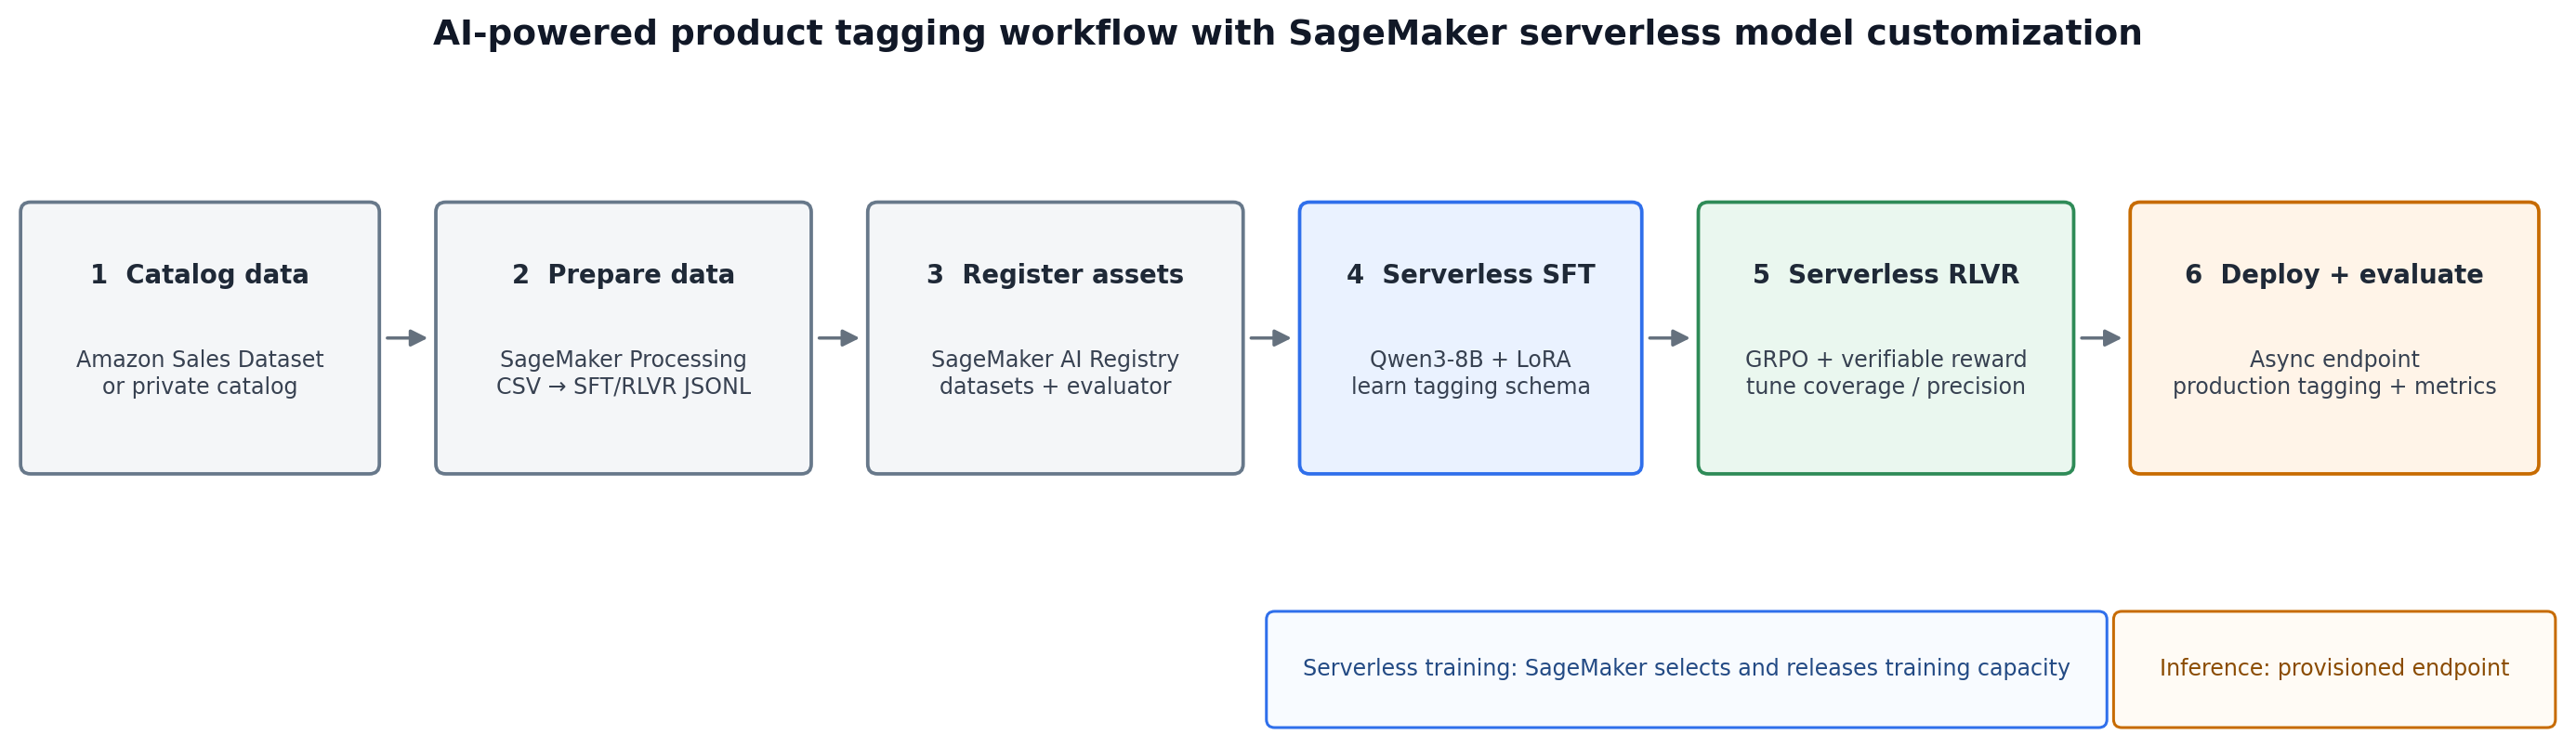
Agents1 min read
Manually tagging thousands of catalog products is slow and inconsistent. This walkthrough shows how to customize Qwen3-8B with supervised fine-tuning (SFT) and reinforcement learning with verifiable rewards (RLVR) on Amazon SageMaker ser...
From AWS machine learning blog
AI1 min read
Reward AI has released OM-1, a general-purpose manipulation policy trained exclusively on human demonstrations using a wearable glove. The system’s unique approach avoids teleoperation and robot data, offering a new path for robot control.
From MarkTechPost
Research1 min read
GLARE, a generative model, achieves high utility and human-likeness scores (0.66 and 0.70 respectively) in forecasting meeting continuations. The model utilizes an adversarial imitation learning approach with a KL-regularized reward signal, outperforming SFT and SPIN while remaining below human performance on the Meeting Dynamic Forecasting Benchmark.
From arXiv cs.AI
LLMs1 min read
SocialRL improves language model social intelligence through multi-turn reinforcement learning and a nuanced reward design. The framework achieves a 9.2% average improvement in goal achievement across benchmarks, demonstrating effective long-horizon planning and relationship management.
From arXiv cs.CL
LLMs1 min read
Edu-QuRating is a pipeline for scoring educational data using LLM judgments and distilled rater models. It enables filtering and reward shaping for language model pre-training and post-training, achieving competitive results compared to GPT-4.1-mini.
From arXiv cs.CL
LLMs1 min read
Researchers introduced UniRRM, a multilingual reasoning reward model and dataset, to improve reward model reliability in open-ended tasks. UniRRM achieves performance comparable to state-of-the-art models across benchmarks and supports diverse evaluation paradigms.
From arXiv cs.CL
Research1 min read
Microsoft Research introduced CARE-X, a new approach to radiology VLMs using auxiliary supervision, reward-aligned learning, and tool-augmented measurement for chest X-ray interpretation. This system aims to create clinically useful models with calibrated predictions and flexible reasoning.
From Microsoft Research
Posts are drafted from public feeds by models OpenSmartRoute routes to - the same router, skill and metering customers use - and always link to the original source. Corrections: support.
Archive (93)