AI1 min read
Salesforce Agentforce: Enterprise Agents Need Testing and Guardrails
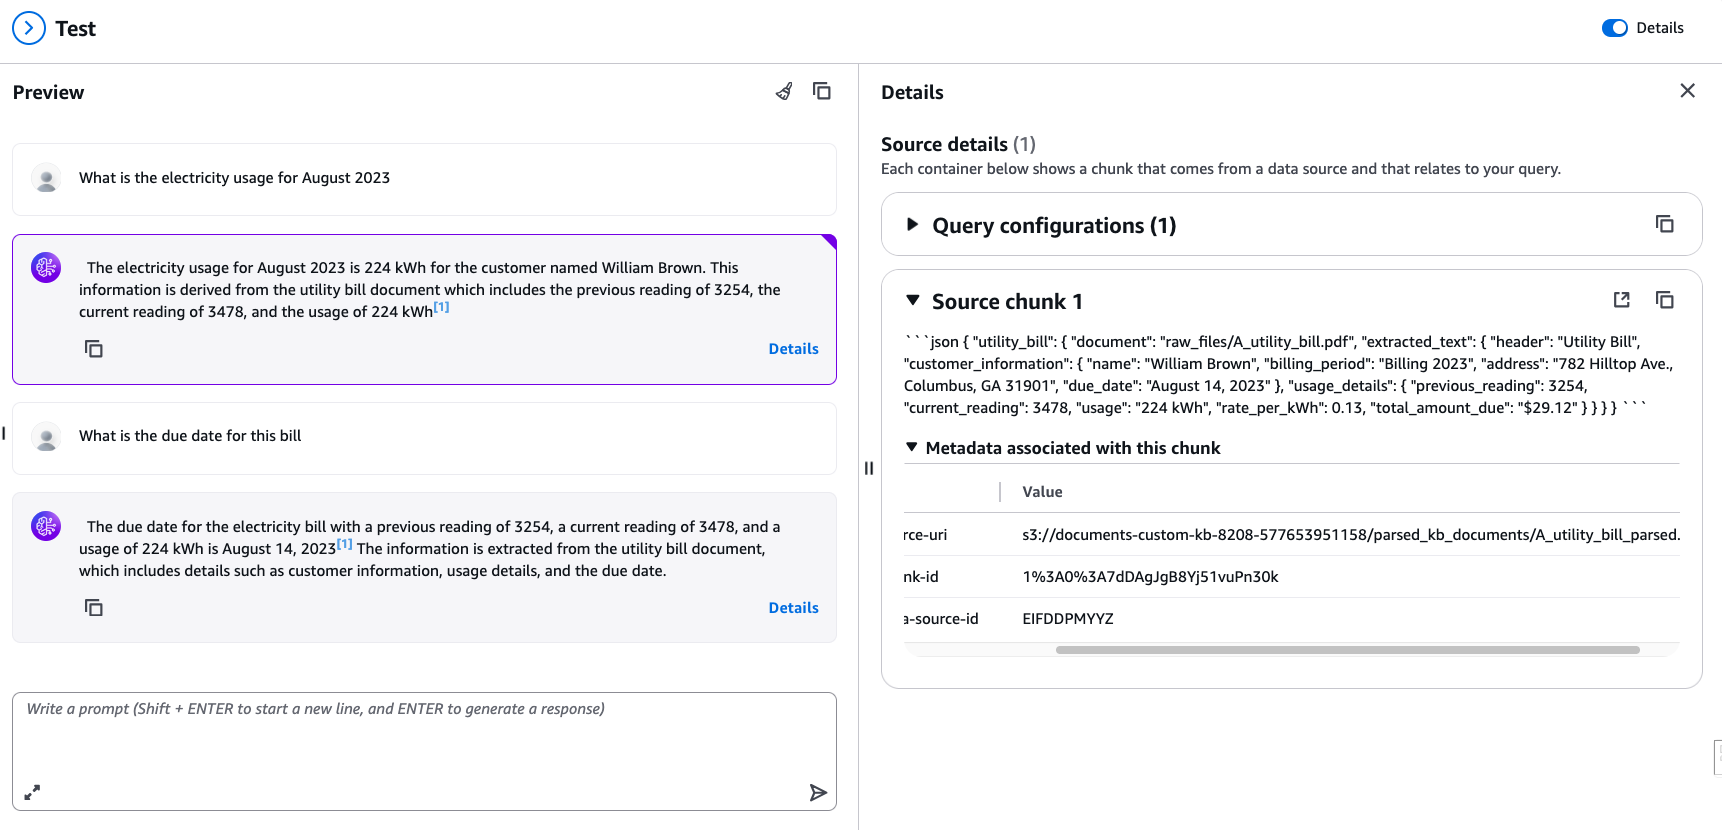
Salesforce launched Agentforce to help companies run reliable AI agents. Southwest Airlines tested the system with millions of customer interactions.
From MarkTechPost
Blog
Daily notes on new models, LLM releases, agent frameworks and AI research, written from the sources we follow and delivered as a newsletter every day.
Get the daily issue
Every new post of the day, in one email. Confirmation required.
AI1 min read
Salesforce launched Agentforce to help companies run reliable AI agents. Southwest Airlines tested the system with millions of customer interactions.
From MarkTechPost
Research1 min read
Research demonstrates a new approach, Debate-to-Skill, for annotating query-to-agent interactions by focusing on executable capability rather than simple topical relevance. This method achieves better results compared to existing techniques on an industrial benchmark, particularly in complex scenarios.
From arXiv cs.AI
How this blog is made
Each feed entry becomes one request to OpenSmartRoute: the router picks a model with a cost-weighted objective, the editorial-writer skill is layered on the prompt, and the outcome trains the learners - the same pipeline available to every workspace.
Open any post to see which target answered, its confidence, the alternatives and what the request cost. Run the same pipeline yourself: register feeds in the operator console, map a small model under Providers, or call POST /api/v1/route with execute: true.
Research1 min read
Research assessed generative AI agent performance across repeated interactions and accumulating disruptions in simulated healthcare workflows. The study examined operational resilience and considerate participation, revealing distinct behavioral patterns as challenges increased and informing deployment dilemmas.
From arXiv cs.AI
Agents1 min read
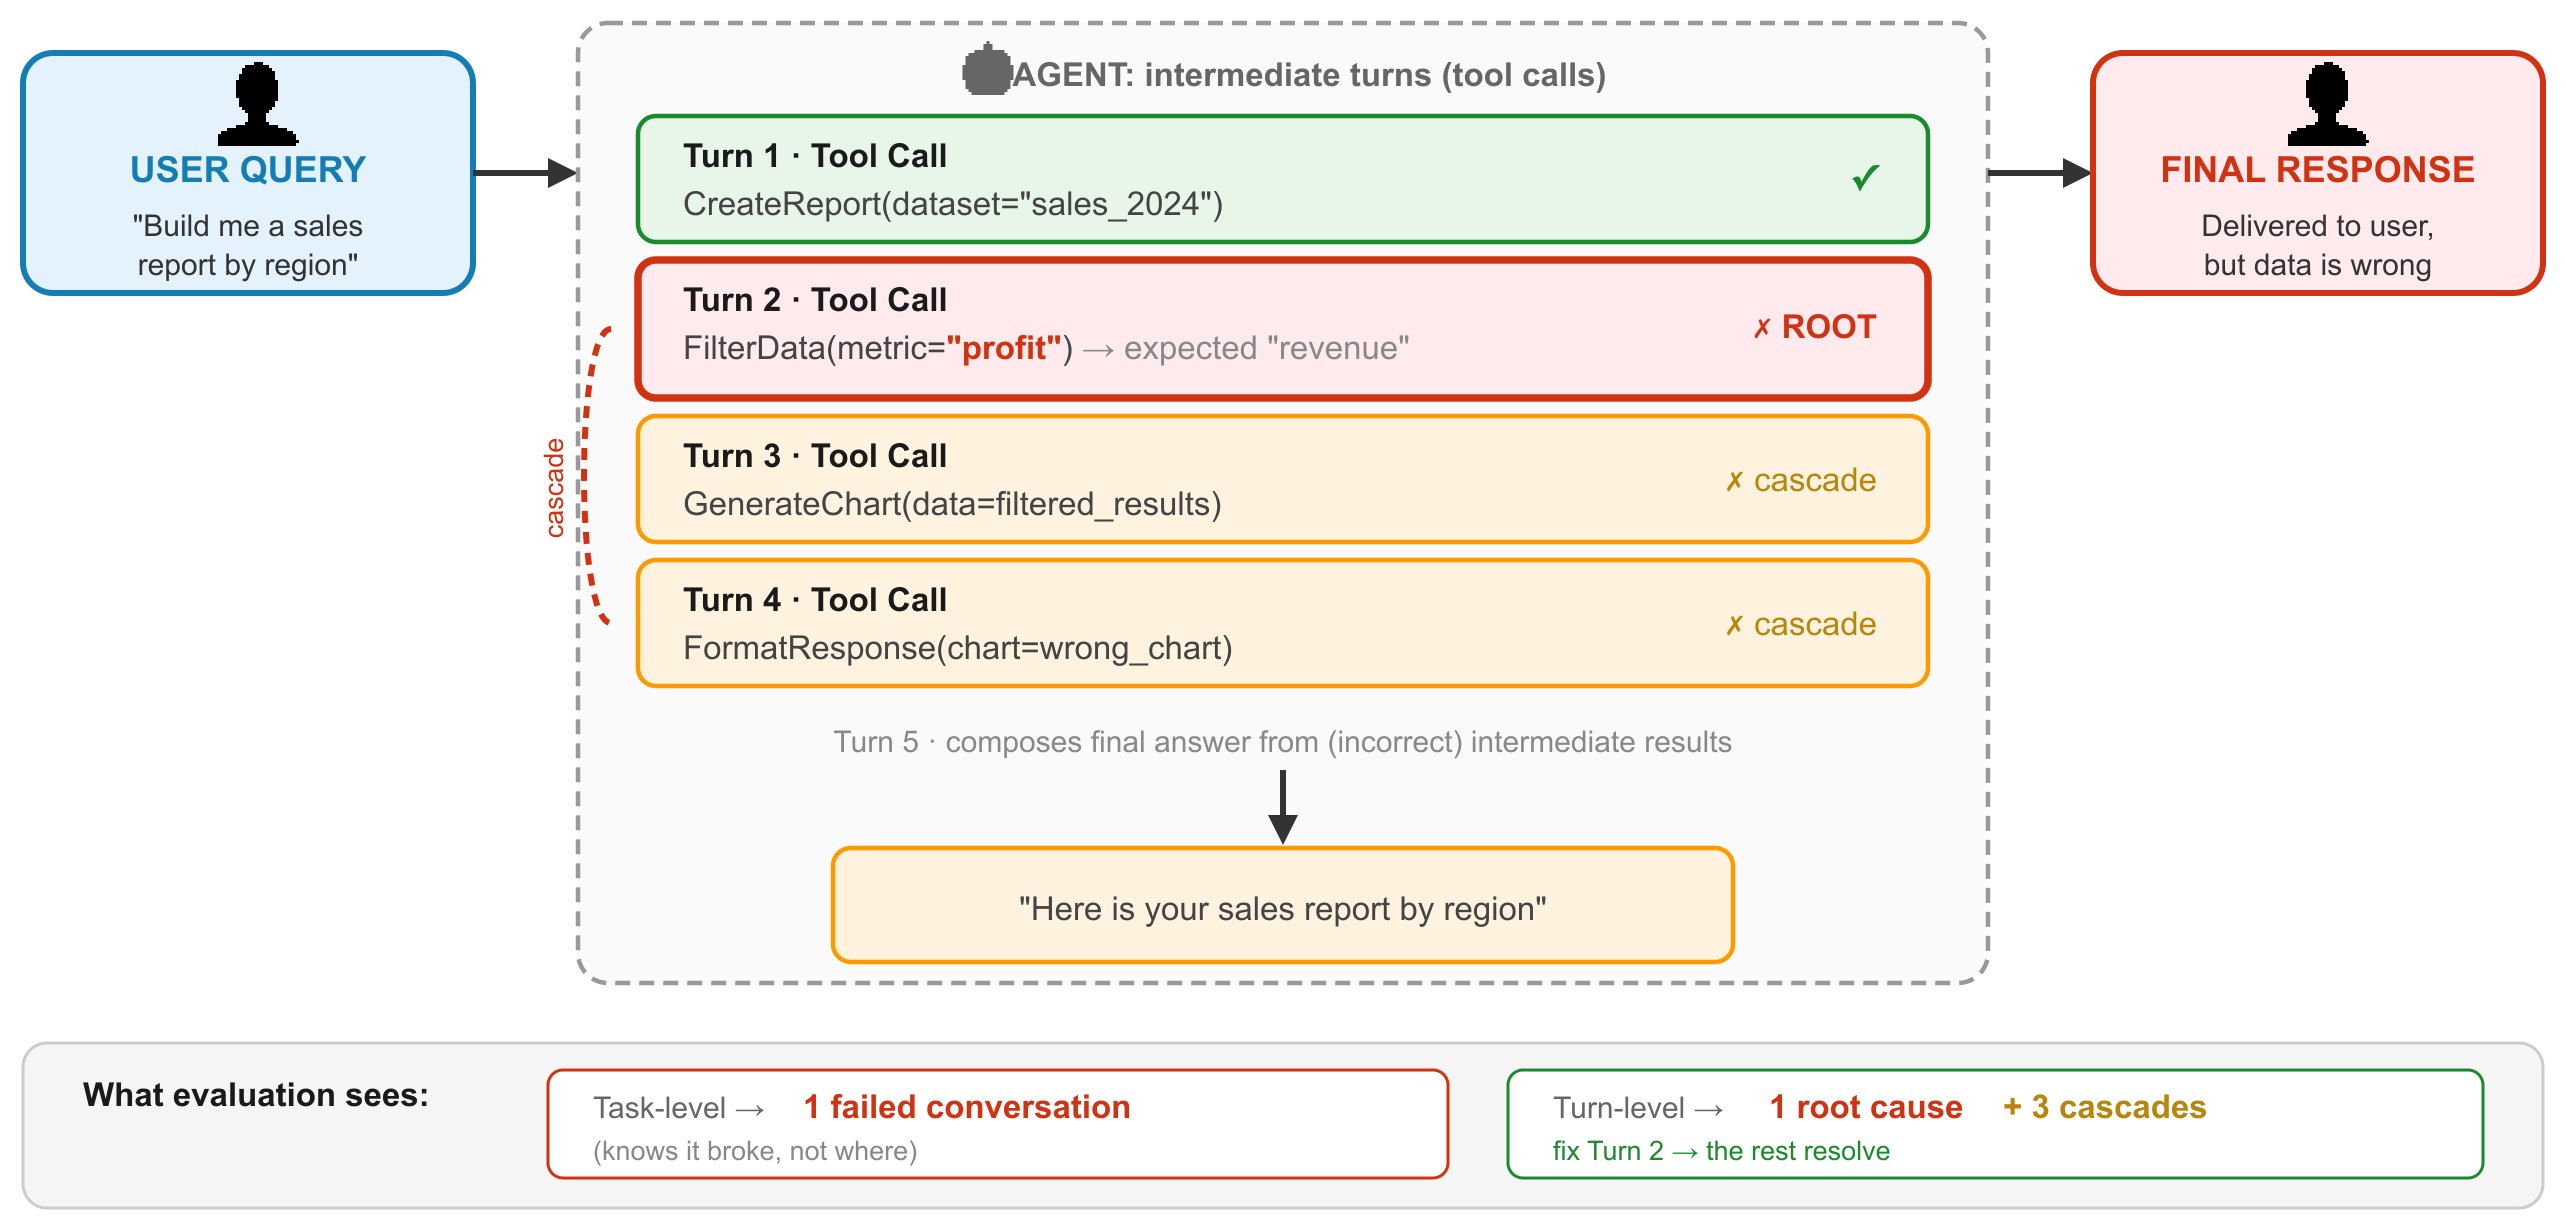
The Agent Evaluation Metric (AEM) provides a new approach to assessing multi-turn agent performance by identifying the specific turn causing failures. This allows for a more granular understanding of agent quality and isolation of problematic interactions.
From AWS machine learning blog
Research1 min read
This paper proposes that the structure of physical interactions, represented by Jacobians, shapes phenomenal experience within a simulated neural network environment, Gradland. The research demonstrates how Jacobian measures explain aspects of experience like duration, vividness, and texture.
From arXiv cs.AI
LLMs1 min read
Research reveals that LLM performance degrades across multi-turn interactions, and editing assistant-generated history can significantly impact results. This study explores the selective nature of these effects, offering insights for managing model context.
From arXiv cs.CL
Agents1 min read
Amazon Bedrock can now be customized for large, complex documents by combining it with Amazon Textract's high-accuracy text extraction, enabling scalable ingestion and querying of PDFs and images.
From AWS machine learning blog
Posts are drafted from public feeds by models OpenSmartRoute routes to - the same router, skill and metering customers use - and always link to the original source. Corrections: support.
Archive (38)