AI1 min read
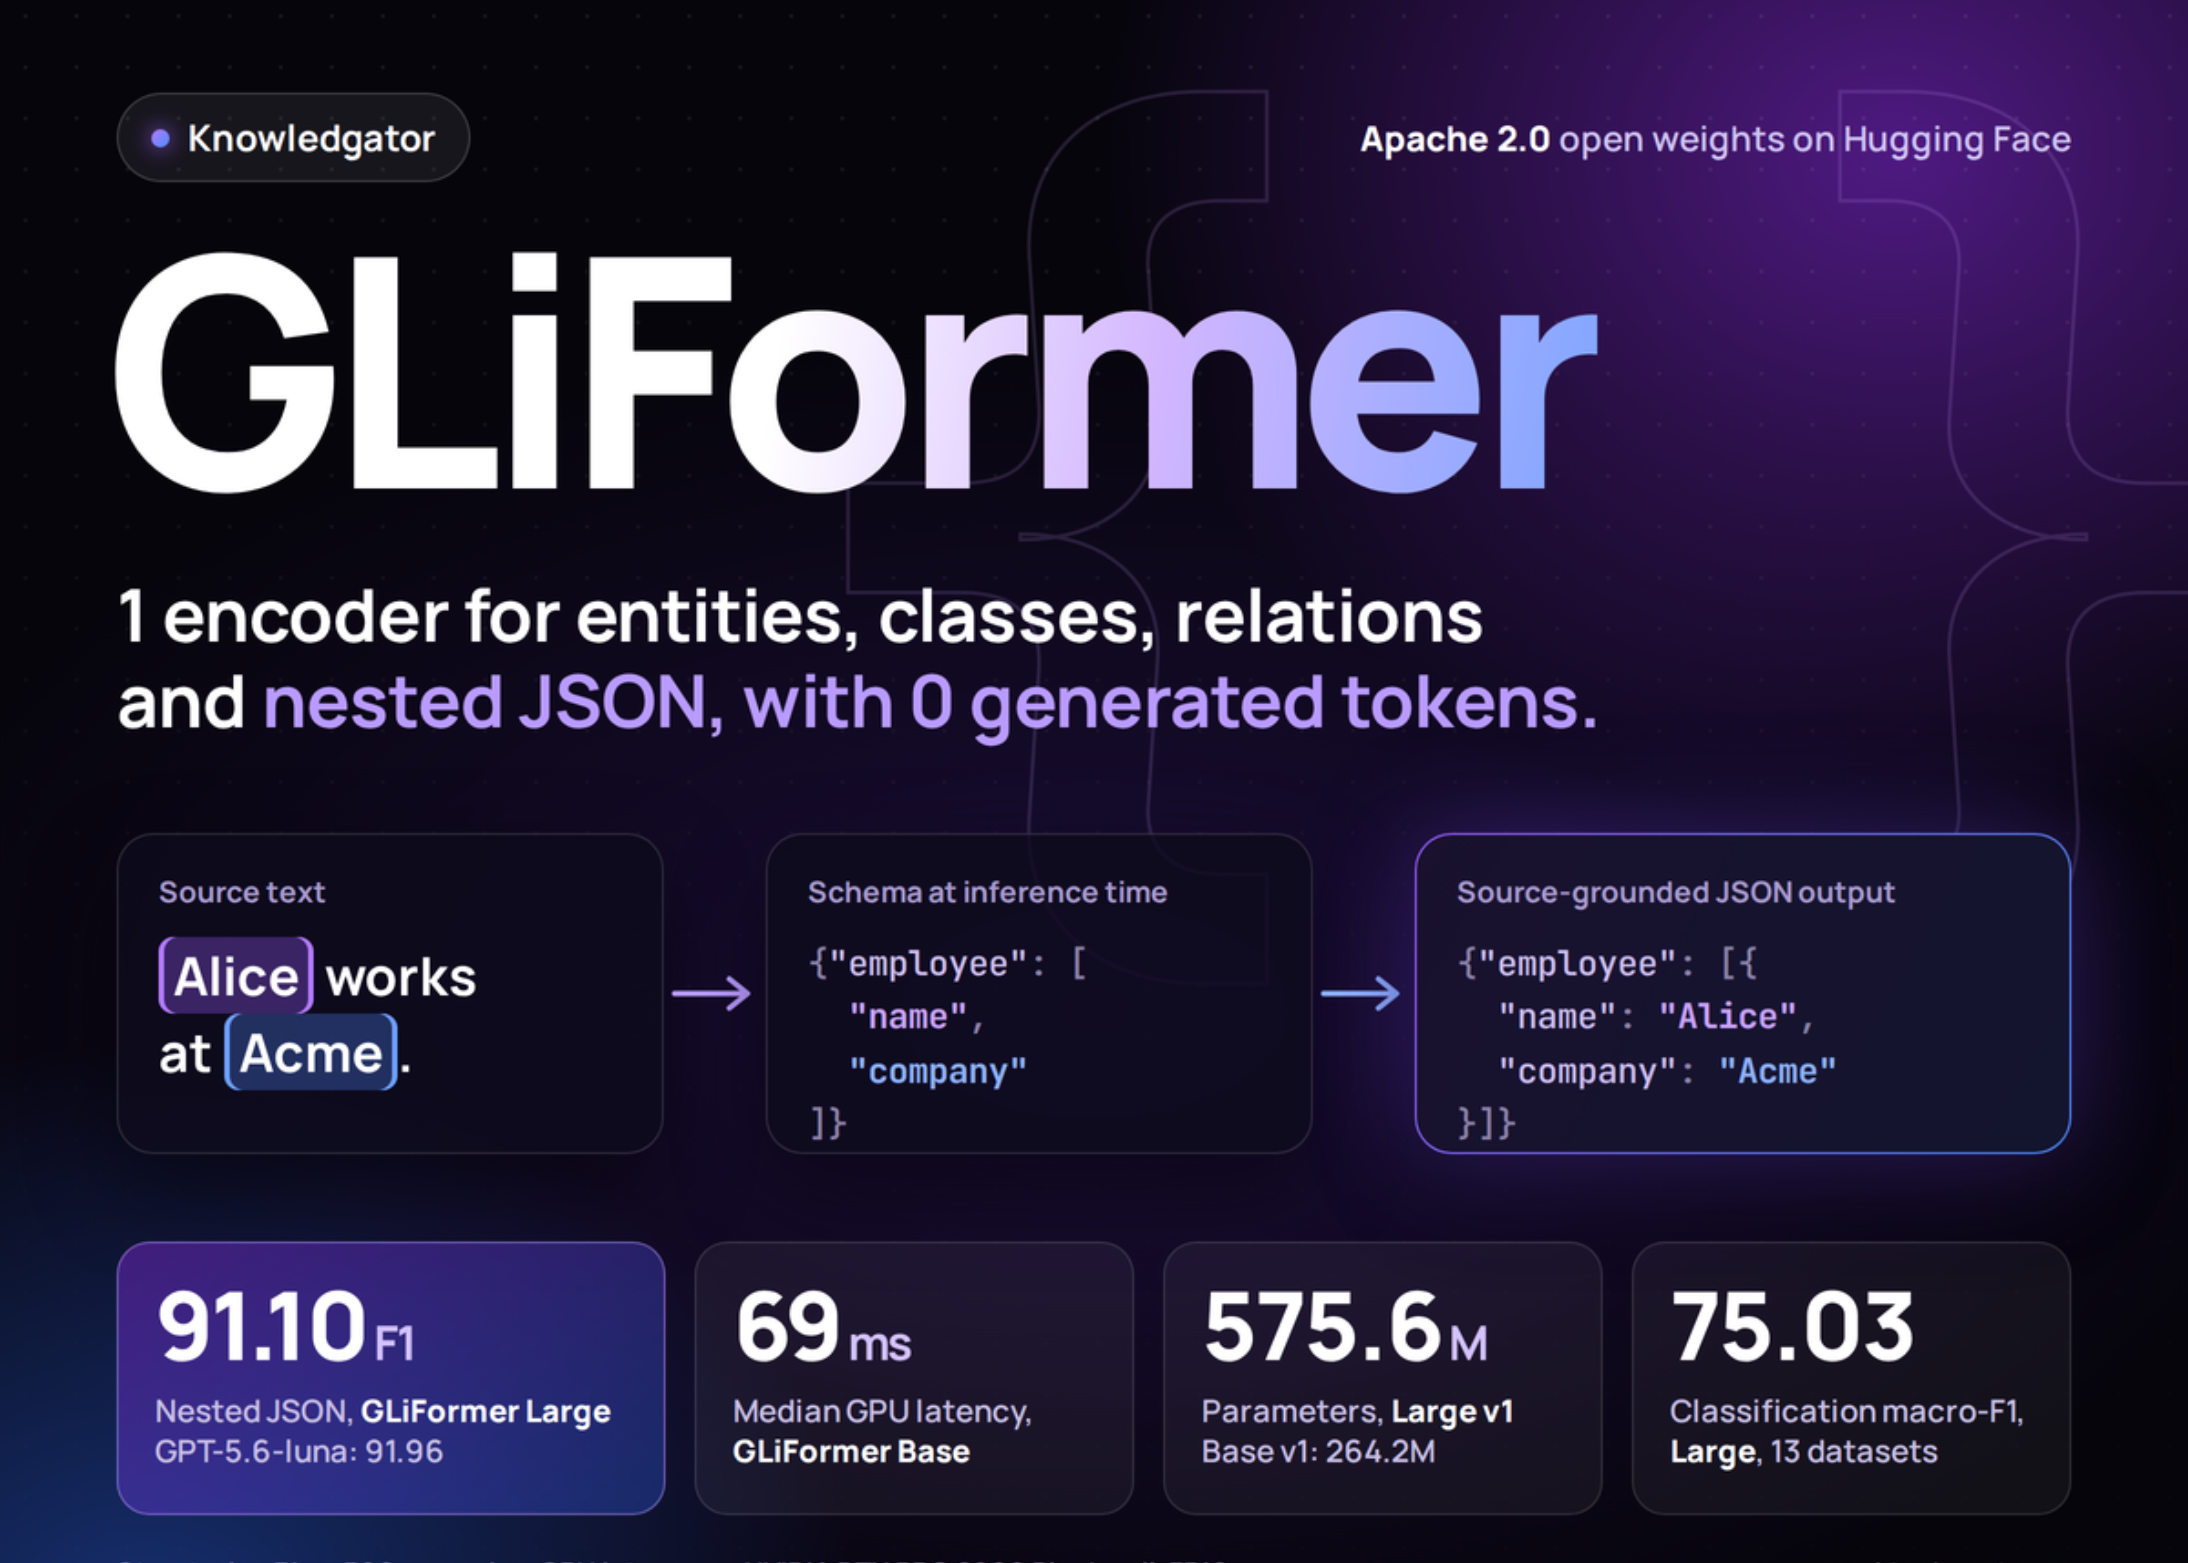
Knowledgator Releases GLiFormer Encoder for JSON Extraction
Knowledgator released GLiFormer, an encoder that extracts nested JSON without generating tokens.
From MarkTechPost
Blog
Daily notes on new models, LLM releases, agent frameworks and AI research, written from the sources we follow and delivered as a newsletter every day.
Get the daily issue
Every new post of the day, in one email. Confirmation required.
AI1 min read
Knowledgator released GLiFormer, an encoder that extracts nested JSON without generating tokens.
From MarkTechPost
LLMs1 min read
Researchers propose RAG-CT to detect malicious queries and reduce Personally Identifiable Information leakage in Retrieval-Augmented Generation systems without modifying the underlying LLM or retriever.
From arXiv cs.CL
How this blog is made
Each feed entry becomes one request to OpenSmartRoute: the router picks a model with a cost-weighted objective, the editorial-writer skill is layered on the prompt, and the outcome trains the learners - the same pipeline available to every workspace.
Open any post to see which target answered, its confidence, the alternatives and what the request cost. Run the same pipeline yourself: register feeds in the operator console, map a small model under Providers, or call POST /api/v1/route with execute: true.
arXiv:2609.13737v1 Announce Type: new Abstract: As large language models (LLMs) are increasingly deployed, the generation of harmful content has become a critical safety concern. Existing safeguards operate at the input, output, or strea...
From arXiv cs.CL
LLMs1 min read
A modular AI framework was developed to automatically identify and structure evidence of social tipping points within climate-related documents. The system utilizes a combination of transformer models and a vector store to achieve high accuracy and facilitate systematic analysis of this critical information.
From arXiv cs.CL
Research1 min read
The Agent Incident Registry (AIR) is a new, source-linked catalog containing over 10,000 records of AI agent failures. It provides detailed information and labels for agent-related events, supporting case retrieval and evaluation-scope auditing.
From arXiv cs.AI
LLMs1 min read
arXiv:2609.10722v1 Announce Type: new Abstract: Structured extraction from Chinese military news supports intelligence analysis, decision-making, and knowledge base construction. However, existing resources provide limited support for jo...
From arXiv cs.CL
LLMs1 min read
arXiv:2609.10950v1 Announce Type: new Abstract: Recent multimodal sentiment analysis studies increasingly adopt text-centric fusion approaches to exploit the rich sentiment information inherent in the textual modality. However, these app...
From arXiv cs.CL
LLMs1 min read
arXiv:2609.11128v1 Announce Type: new Abstract: In disinformation datasets, narratives are often understood as recurring interpretive patterns that group texts under narrative labels. Recent work formalized narrative mining as inductivel...
From arXiv cs.CL
LLMs1 min read
arXiv:2609.11029v1 Announce Type: new Abstract: Large language models are typically trained under uniform token weighting, which allows frequent and low-information tokens to dominate learning and can increase the tendency to memorize su...
From arXiv cs.CL
Agents1 min read
A new detector on Amazon Bedrock allows any large language model to identify Personally Identifiable Information (PII). This configurable detector adapts to new entity types without retraining and surpasses existing tools in performance.
From AWS machine learning blog
Models1 min read
Google’s Search is integrating Gemini to provide runners with personalized training plans and real-time insights, leveraging AI to optimize running performance. This allows users to access detailed information and guidance directly within the Search interface.
From Google AI blog
LLMs1 min read
ROAM improves answer accuracy in long-term language model agents by organizing atomic memories using semantic relations. The framework’s fusion process and role organization enhance recall and reduce irrelevant information, demonstrating consistent gains across model scales.
From arXiv cs.CL
LLMs1 min read
This research traces the evolution of algorithmic outputs, identifying three key mutations – speech as data, speech as engagement, and generative text – and their associated legal and social consequences. It provides a framework for understanding these changes and their impact on freedom of expression and informational privacy.
From arXiv cs.CL
Models1 min read
Google Search now integrates AI Mode with enhanced football features, providing users with play diagrams and scoreboards. This allows for deeper analysis and information retrieval related to American football.
From Google AI blog
Research1 min read
Research demonstrates that language model embeddings capture structured temporal and geographic information through a projection-based method. This black-box approach allows for analyzing embedding spaces without model access, offering a tool for interpretability and information retrieval tasks.
From arXiv cs.AI
Research1 min read
AlphaGenome Atlas details a comprehensive map of single-letter DNA variants across the human genome, predicting molecular effects for 9 billion changes. This resource offers detailed information for engineers working with genomic models and agents.
From Google DeepMind blog
LLMs1 min read
The study examines internal changes in Audio LLMs when trained on data that requires audio for answer determination, highlighting how acoustic information impacts model representations and predictions.
From arXiv cs.CL
Research1 min read
Enhanced capabilities in large language models may lead to more correlated behaviors, increasing systemic risk, especially when models share reasoning or misinformation environments.
From arXiv cs.AI
LLMs1 min read
Hugging Face announced new memory capabilities for coding agents, enabling them to retain information across sessions. This enhancement aims to improve agent performance and context handling.
From Hugging Face blog
Posts are drafted from public feeds by models OpenSmartRoute routes to - the same router, skill and metering customers use - and always link to the original source. Corrections: support.
Archive (38)