AI1 min read
Nunchux AI Releases Training-Free Low-Bit Attention Kernel
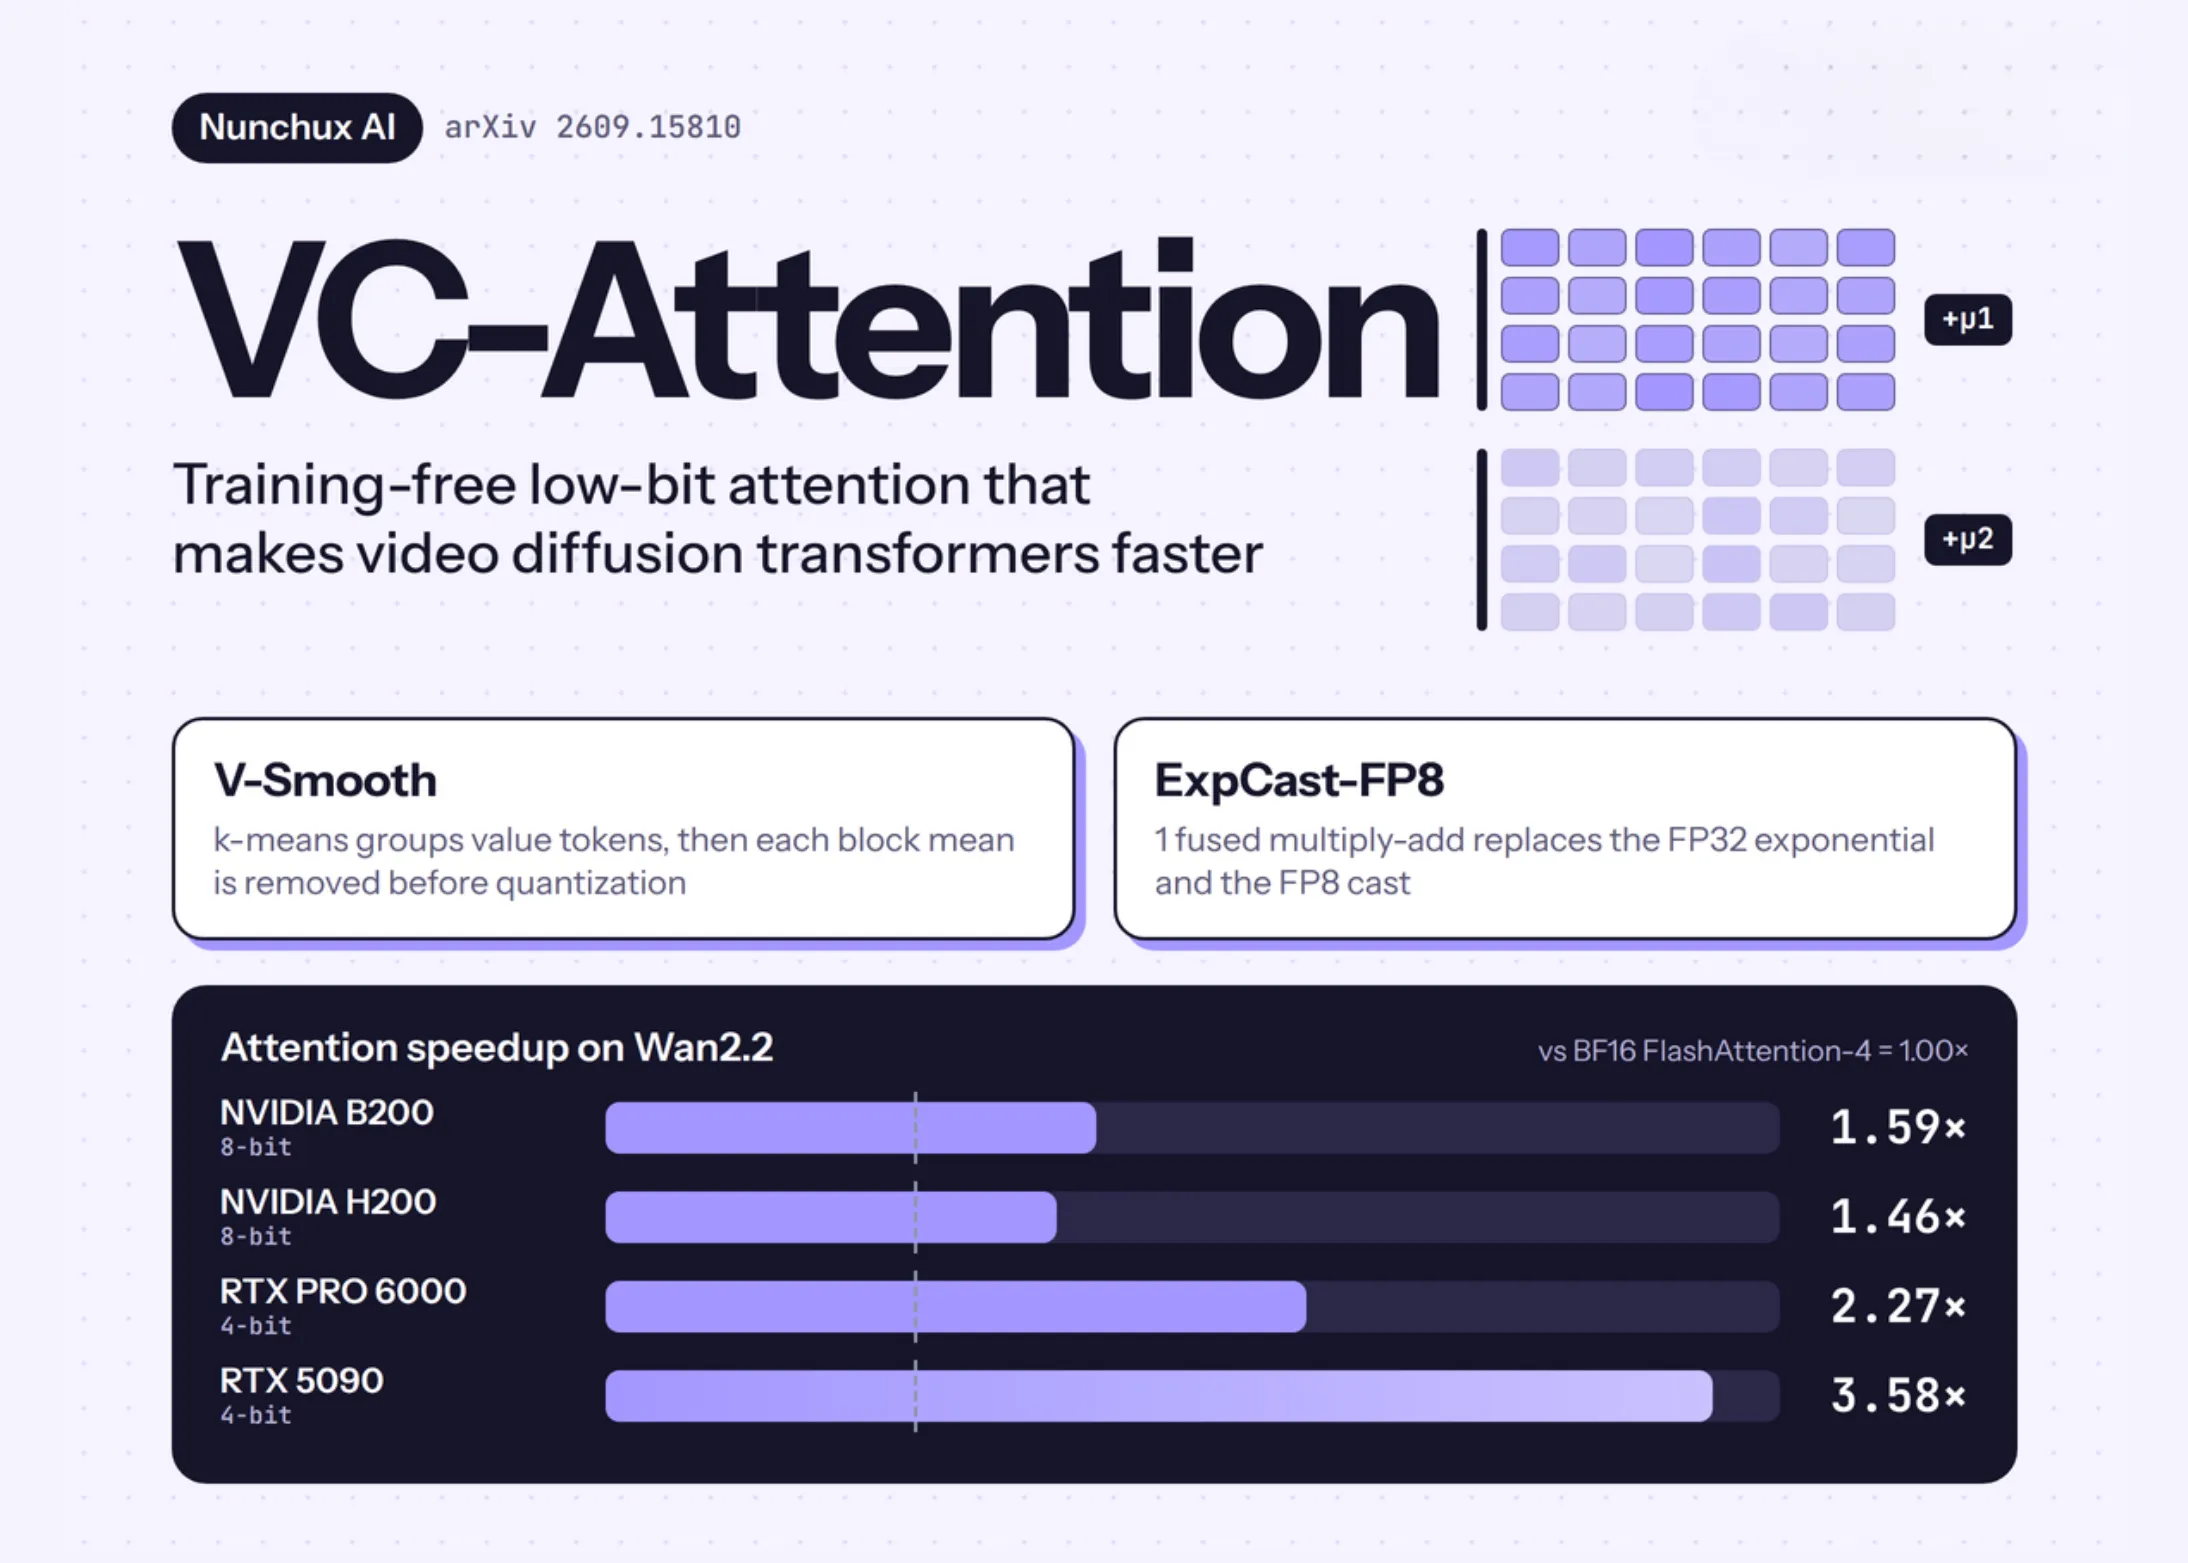
Nunchux AI launched VC-Attention to speed up video diffusion models without retraining. It uses low-bit quantization and replaces the slow softmax stage.
From MarkTechPost
Blog
Daily notes on new models, LLM releases, agent frameworks and AI research, written from the sources we follow and delivered as a newsletter every day.
Get the daily issue
Every new post of the day, in one email. Confirmation required.
AI1 min read
Nunchux AI launched VC-Attention to speed up video diffusion models without retraining. It uses low-bit quantization and replaces the slow softmax stage.
From MarkTechPost
AI1 min read
Learn how to leverage NVIDIA’s cuDNN Frontend Graph API to build custom kernel fusions, autotuning engine configurations, FP8-style epilogues, scaled dot-product attention, dynamic shapes, and CUDA graph captures. This practical tutorial...
From MarkTechPost
How this blog is made
Each feed entry becomes one request to OpenSmartRoute: the router picks a model with a cost-weighted objective, the editorial-writer skill is layered on the prompt, and the outcome trains the learners - the same pipeline available to every workspace.
Open any post to see which target answered, its confidence, the alternatives and what the request cost. Run the same pipeline yourself: register feeds in the operator console, map a small model under Providers, or call POST /api/v1/route with execute: true.
Research1 min read
A new Latent-Attention Masked Autoencoder (LAMAE) was developed for learning patient-level representations from multimodal cardiac data. Pretrained on MIMIC-IV, LAMAE outperforms modality-specific models and achieves improved performance across multiple clinical tasks, even with single-modality inputs.
From arXiv cs.AI
AI1 min read
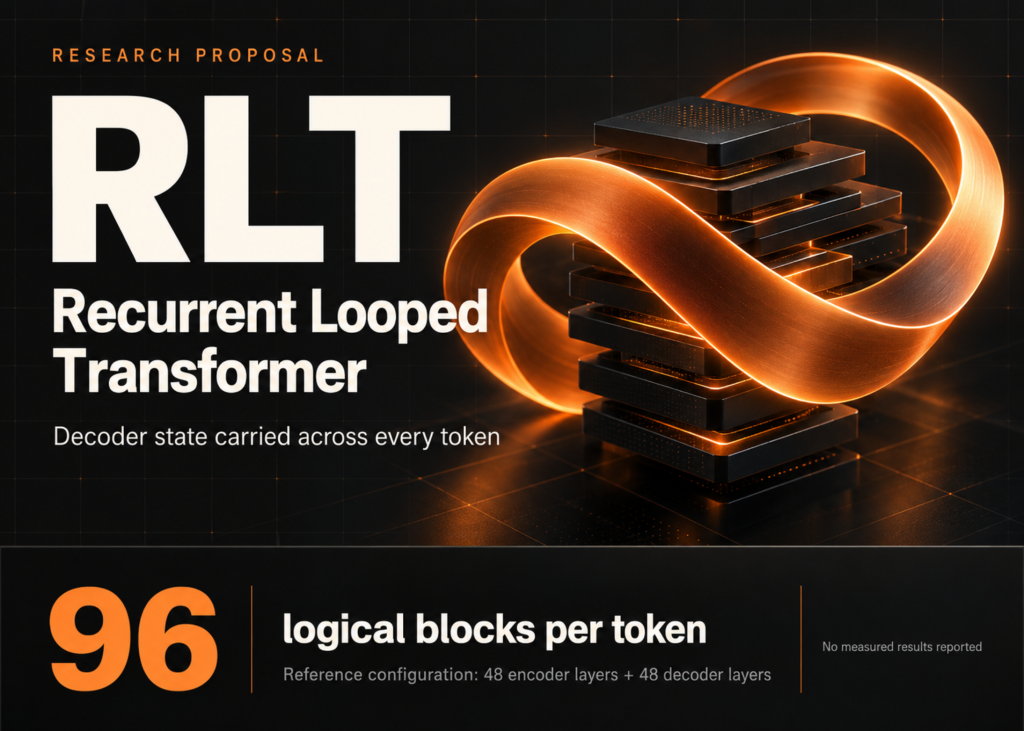
A new architecture, Recurrent Looped Transformer (RLT), developed by a Princeton researcher, allows for unbounded temporal depth in decoder-only LLMs by carrying decoder state across all tokens. This design addresses limitations in traditional attention mechanisms and offers a potential path to improved reasoning capabilities.
From MarkTechPost
Research1 min read
DRG-MAPPO, a new multi-agent reinforcement learning framework, achieves a 87% win rate in cooperative air combat simulations. The system utilizes graph-based relational modeling and dynamic role assignment to improve tactical coordination and collaborative execution.
From arXiv cs.AI
LLMs1 min read
Hybrid language models use attention and recurrent states with distinct roles; attention handles retrieval, recurrence influences output generation. Interventions clarify their functions.
From arXiv cs.CL
Research1 min read
EXAONE Finance introduces an attention-free architecture for financial forecasting, replacing self-attention with linear-time operators and improving robustness to missing data across diverse asset classes.
From arXiv cs.AI
Research1 min read
BioSync combines multiple physiological measurements into a continuous biomarker using a transformer-based architecture, evaluated on synthetic cohorts with promising results.
From arXiv cs.AI
LLMs1 min read
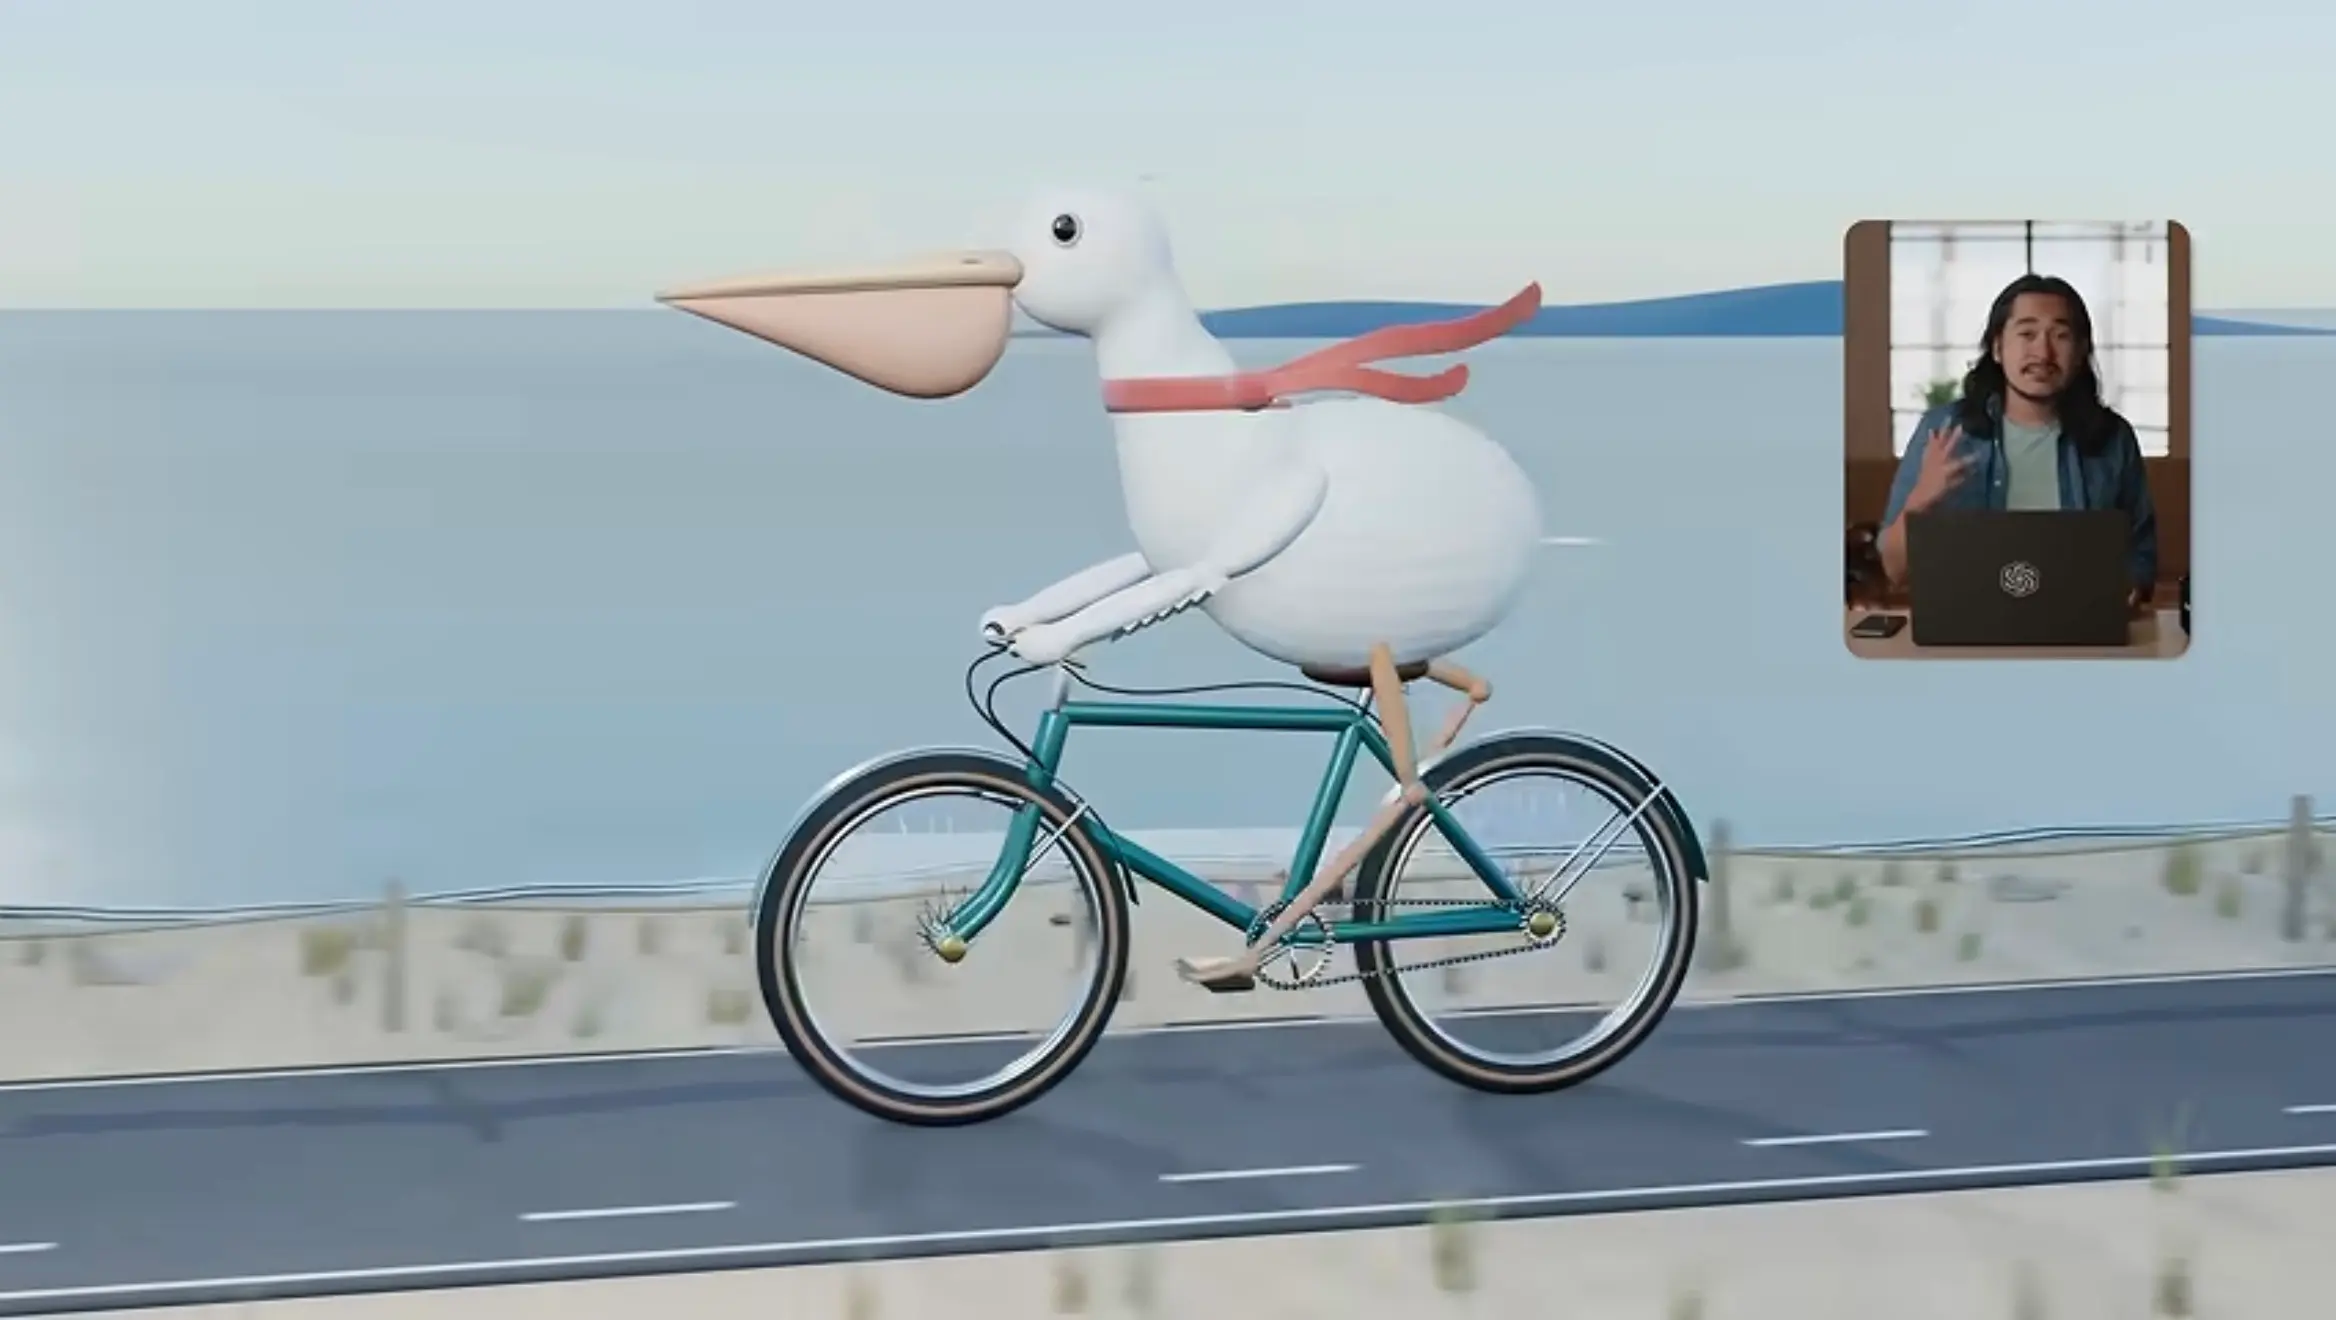
GPT-6 Astra demonstrates improved attention to detail, understanding, and output complexity, especially in 3D modeling tasks, compared to previous models.
From Simon Willison
Agents1 min read
Z.ai released GLM-5.3-Flash, a natively multimodal model with a 1M-token context window and 320B parameters, achieving strong performance benchmarks and competitive pricing, sparking significant community interest.
From Latent Space
LLMs1 min read
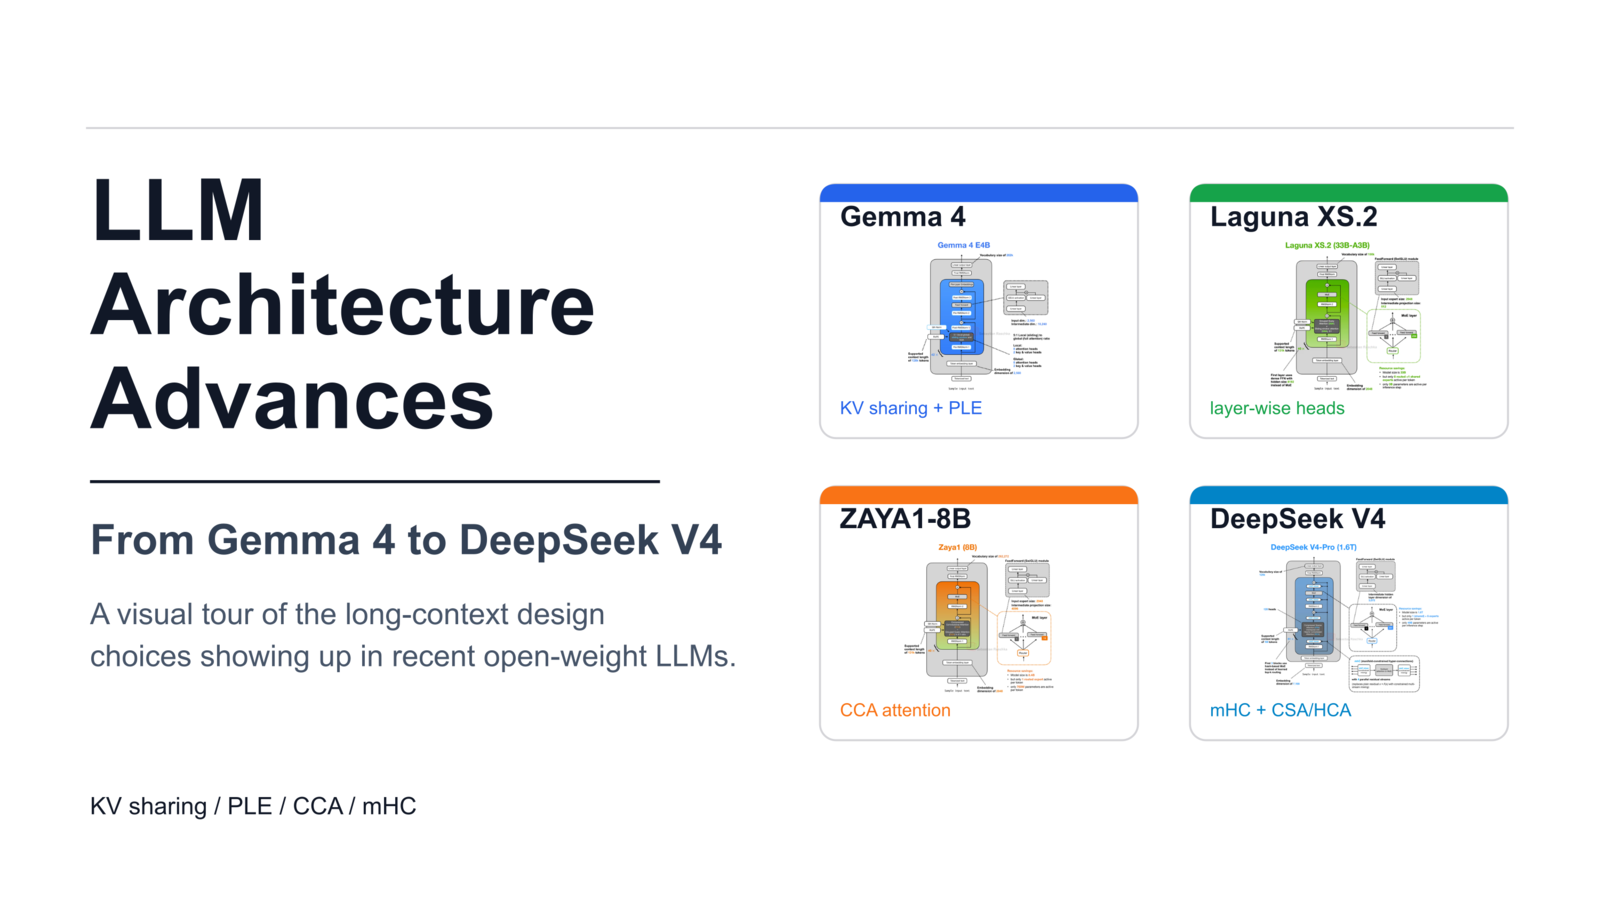
From Gemma 4 to DeepSeek V4, How New Open-Weight LLMs Are Reducing Long-Context Costs
From Ahead of AI (Sebastian Raschka)
LLMs1 min read
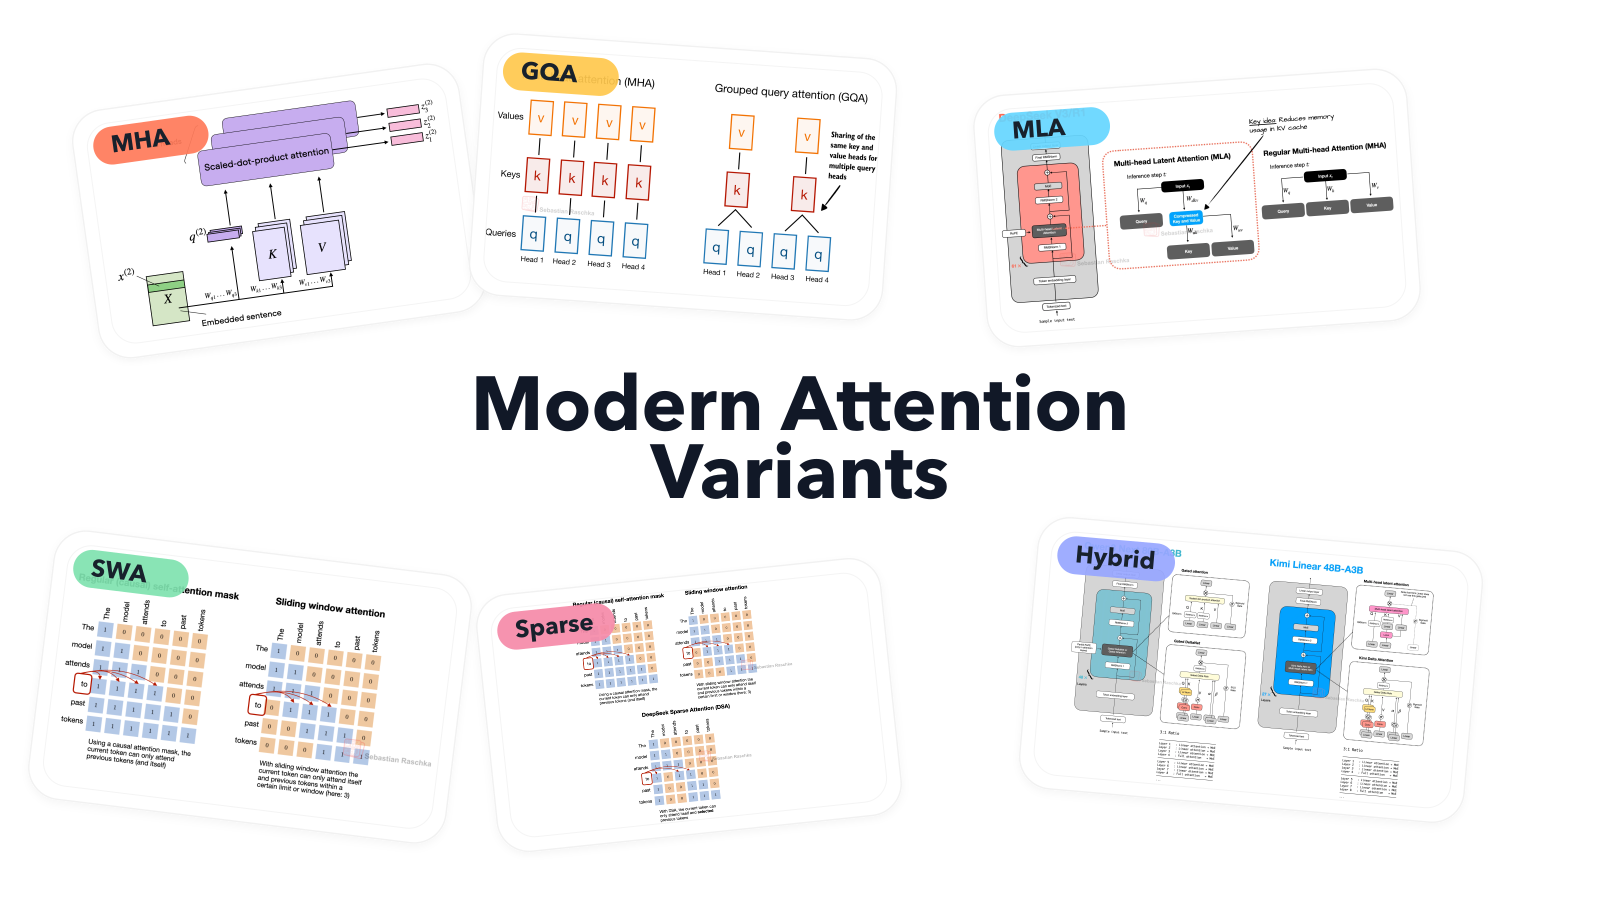
From MHA and GQA to MLA, sparse attention, and hybrid architectures
From Ahead of AI (Sebastian Raschka)
Posts are drafted from public feeds by models OpenSmartRoute routes to - the same router, skill and metering customers use - and always link to the original source. Corrections: support.
Archive (34)