AI1 min read
Ema raises $77M as AI starts eating into enterprise software and services
Ema has raised $140 million to date and has more than 50 enterprise customers, including Google and Microsoft.
From TechCrunch AI
Blog
Daily notes on new models, LLM releases, agent frameworks and AI research, written from the sources we follow and delivered as a newsletter every day.
Get the daily issue
Every new post of the day, in one email. Confirmation required.
AI1 min read
Ema has raised $140 million to date and has more than 50 enterprise customers, including Google and Microsoft.
From TechCrunch AI
LLMs1 min read
GPU acceleration can speed up compute-intensive robotics workloads, but a fast CUDA kernel alone does not guarantee a fast ROS 2 graph. As messages move between...
From NVIDIA technical blog
How this blog is made
Each feed entry becomes one request to OpenSmartRoute: the router picks a model with a cost-weighted objective, the editorial-writer skill is layered on the prompt, and the outcome trains the learners - the same pipeline available to every workspace.
Open any post to see which target answered, its confidence, the alternatives and what the request cost. Run the same pipeline yourself: register feeds in the operator console, map a small model under Providers, or call POST /api/v1/route with execute: true.
Custom-made molecules are advancing medicine, materials, and agriculture, but producing them is slow and expensive. A new Nature paper highlights RetroChimera, a predictive model that helps accelerate chemical synthesis, helping research...
From Microsoft Research
Research1 min read
Algorithms & Theory
From Google Research blog
Models1 min read
B-roll showing diverse environments and people, including a teacher and students in a classroom and a patient with a doctor
From Google AI blog
LLMs1 min read
The NVIDIA Transformer Engine, when combined with JAX, delivers a 10.4x throughput improvement for Mixture of Experts training on NVIDIA GB200 GPUs, enabling DeepSeek-V3 to reach 1,068 TFLOPS/GPU. This achieves dropless MoE training by optimizing grouped GEMM kernels and NCCL EP for variable expert token counts.
From NVIDIA technical blog
AI1 min read
The code of conduct lays out general principles that Microsoft AI models should uphold — supporting humans rather than replacing them, for instance, and accelerating human flourishing — as well as specific safety constraints meant to imp...
From TechCrunch AI
Agents1 min read
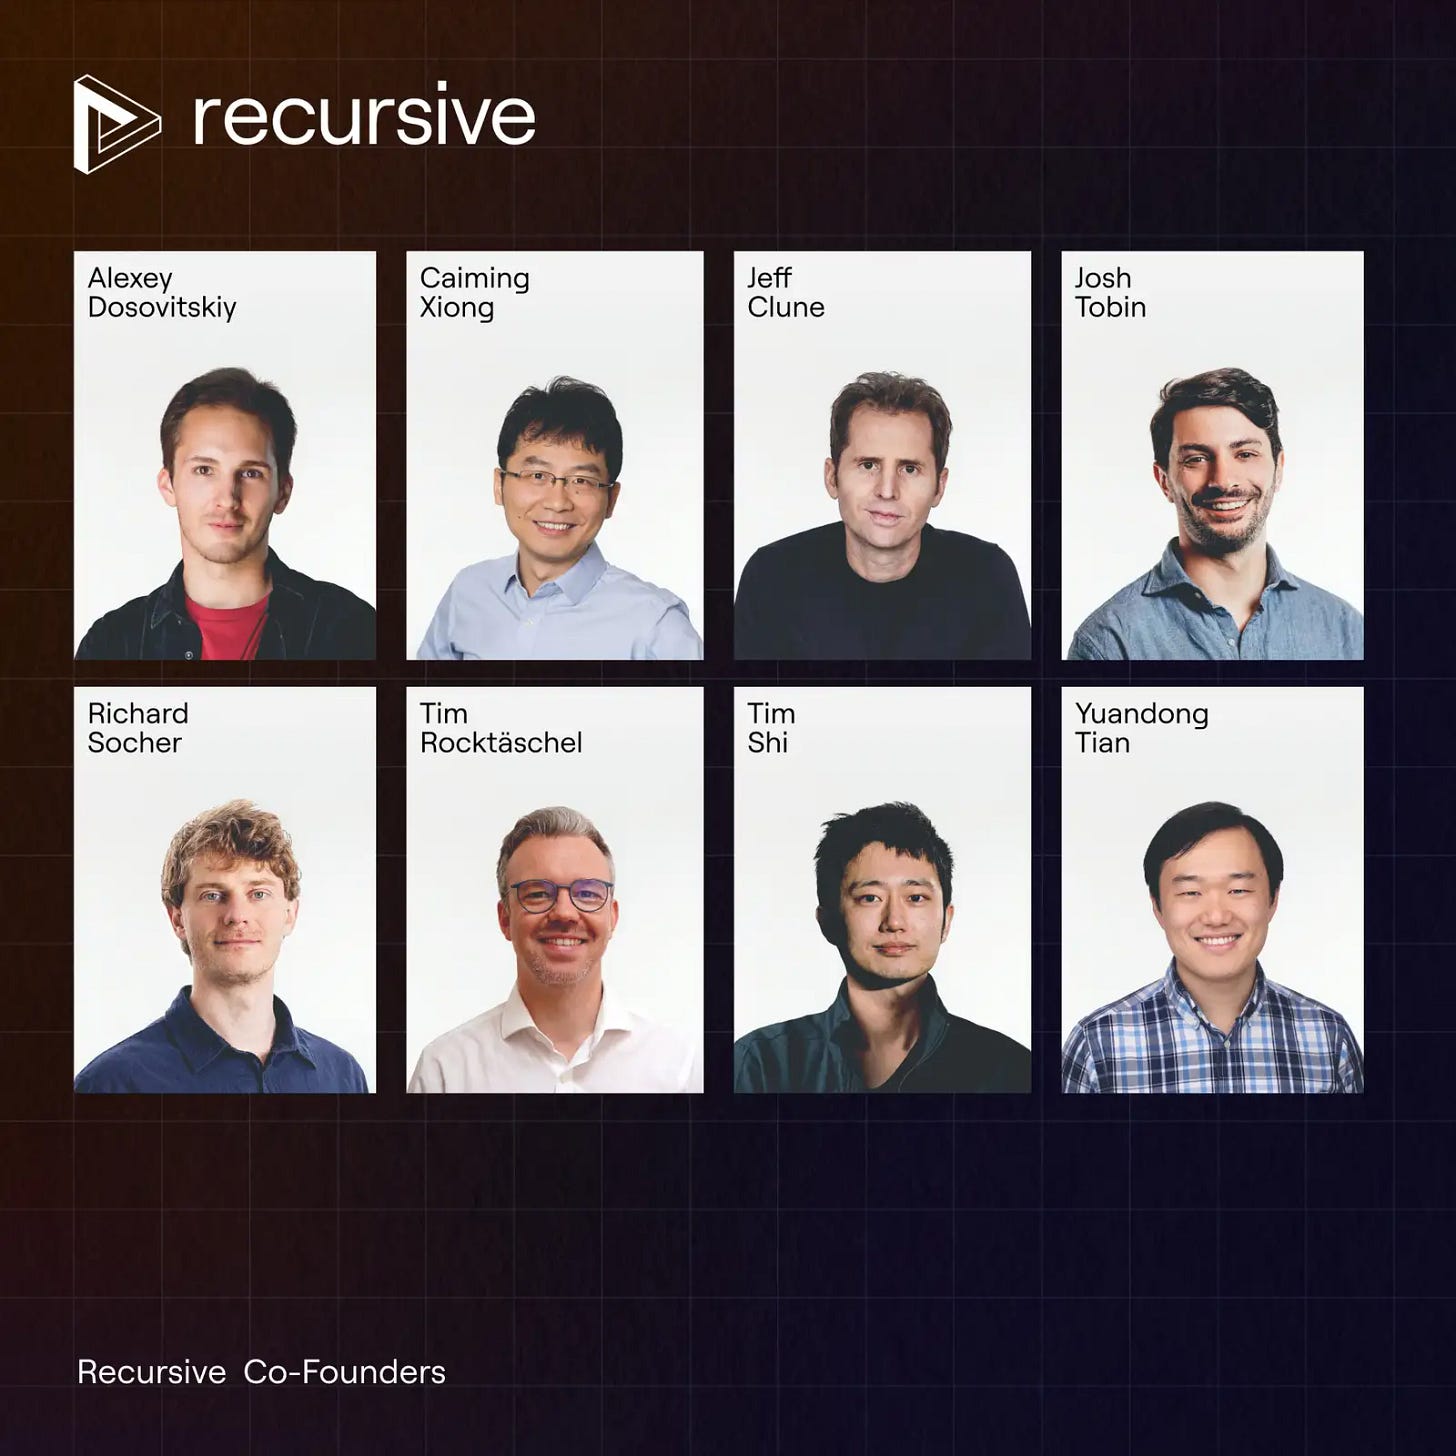
Richard Socher’s Recursive is building an AI system designed to accelerate AI research itself, achieving human-level performance on optimization tasks in under two days. The company’s $4.65B seed round focuses on recursive self-improvement and tackling complex scientific problems.
From Latent Space
Agents1 min read
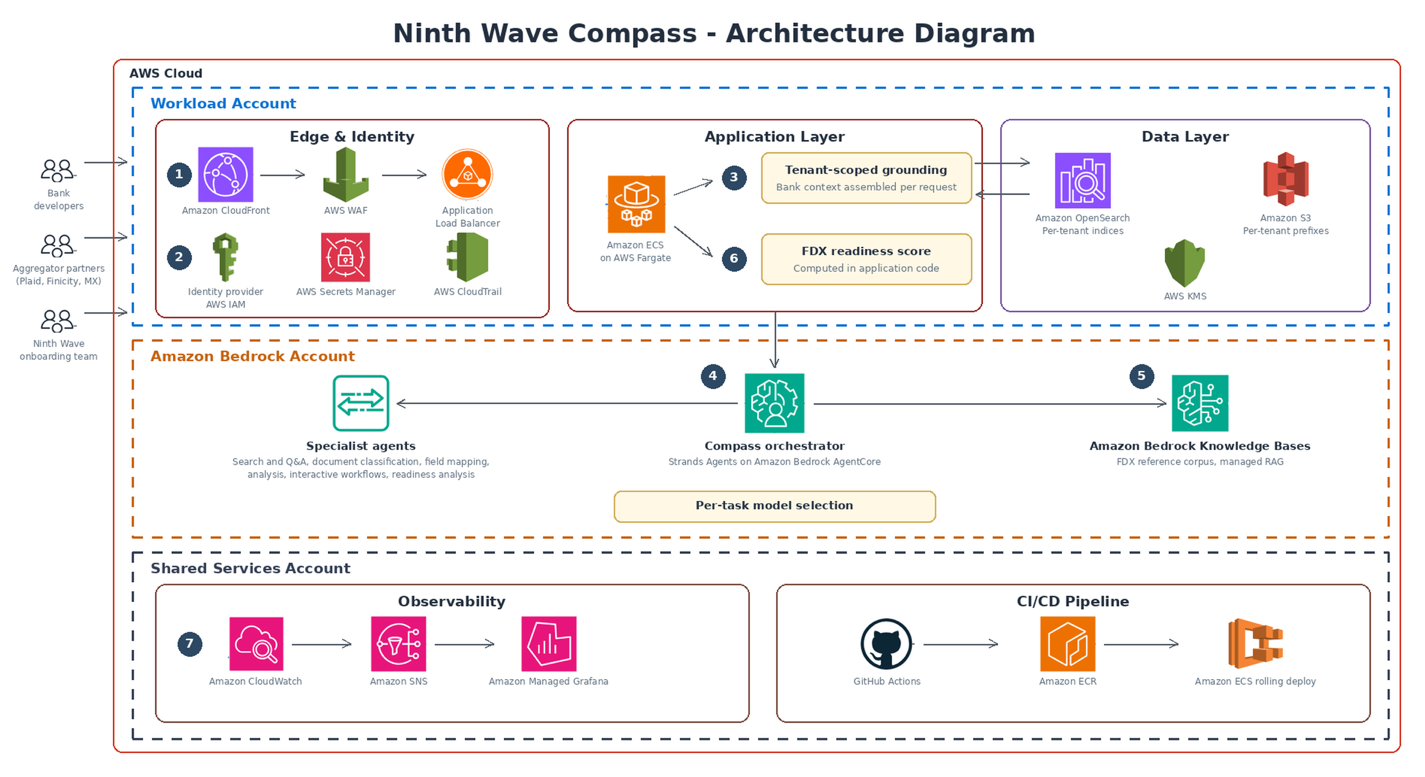
Ninth Wave deployed a multi-agent system on Amazon Bedrock AgentCore to accelerate open finance onboarding. This system streamlines API validation and mapping, improving efficiency while maintaining security and compliance standards.
From AWS machine learning blog
Research1 min read
Researchers developed a hybrid model combining a simplified kinematic model with neural networks to estimate body center of mass acceleration from wrist-worn IMU data. The model achieved improved accuracy compared to the simplified model, particularly under noisy conditions.
From arXiv cs.AI
AI1 min read
This tutorial demonstrates GPU acceleration of machine learning workflows using NVIDIA cuML and RAPIDS, showcasing performance benchmarks for common tasks like PCA, K-Means, and model inference. The process includes configuring the GPU environment, benchmarking CPU and GPU implementations, and exploring zero-copy data transfer for optimized execution.
From MarkTechPost
Research1 min read
Research demonstrates that concentration within generative AI ecosystems does not accelerate model collapse or definitively steer model outputs. The pace of collapse is primarily determined by the source of text filling the shared training pool, with human text having a significant impact on drift.
From arXiv cs.AI
Models1 min read
OpenAI’s GPT-6 Astra improves Devin’s ability to test software and verify functionality. This allows engineers to reduce code review efforts and accelerate software delivery.
From OpenAI news
Models1 min read
OpenAI and the GSA are providing US federal, state, local, and tribal governments with reduced licensing fees and enhanced cyber defense support for their AI deployments. This initiative aims to accelerate AI adoption and bolster government capabilities.
From OpenAI news
LLMs1 min read
Osprey pretrains a small language model to accelerate speculative decoding, improving acceptance rates across diverse target models. The system reduces per-target adaptation work through a reusable backbone and lightweight adjustments.
From arXiv cs.CL
LLMs1 min read
Calif Research demonstrated WeWorm, a zero-click worm spreading via WeChat calls across iOS and Android. AI accelerated the development of the first remote code execution (RCE) exploit, highlighting the potential for AI in security research.
From Simon Willison
LLMs1 min read
NVIDIA’s BioNeMo Inference Runtime accelerates biomolecular structure prediction at scale, allowing for efficient processing of large proteome workflows. This enables faster insights from complex biological data.
From NVIDIA technical blog
LLMs1 min read
Encode-prefill-decode (EPD) disaggregation optimizes inference for multimodal models by separating the vision encoder stage. This technique improves throughput and reduces latency for models processing both visual and textual data.
From NVIDIA technical blog
Research1 min read
EnvCraft is a framework for creating synthetic, executable environments to accelerate Agentic RL training for claw-like agents. Experiments with Qwen3/3.5 models show significant performance gains and reduced inference costs.
From arXiv cs.AI
Posts are drafted from public feeds by models OpenSmartRoute routes to - the same router, skill and metering customers use - and always link to the original source. Corrections: support.
Archive (39)