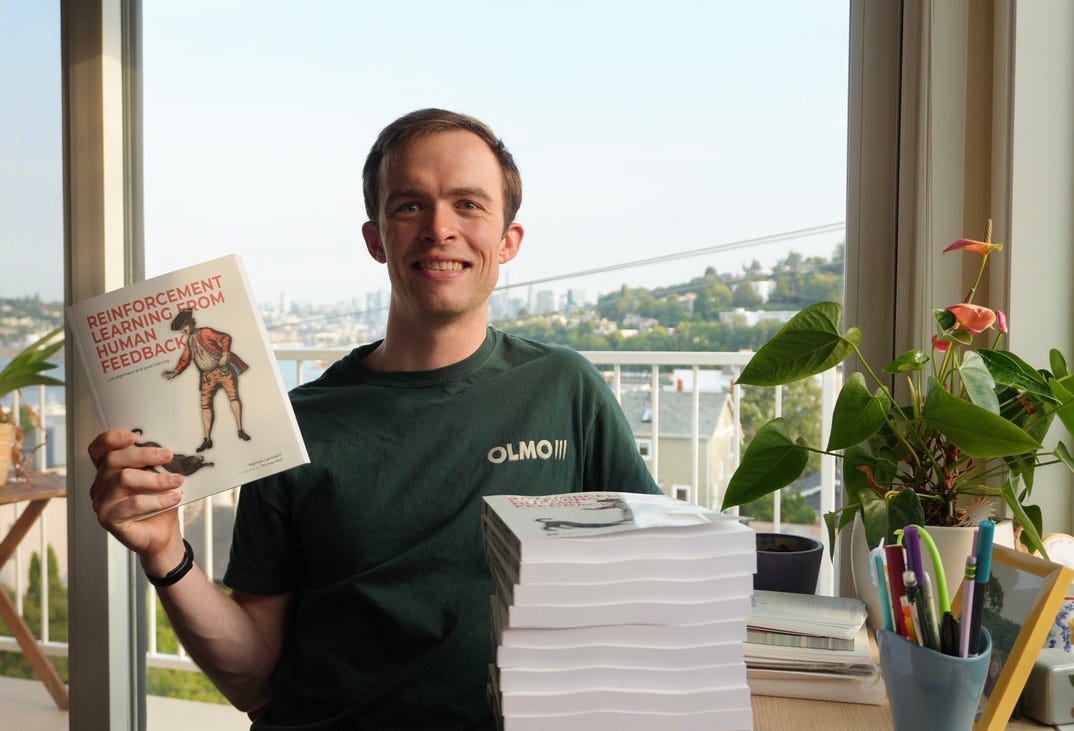
The book, authored by a researcher, addresses a significant gap in available resources for engineers focused on post-training Large Language Model (LLM) alignment. It began as a website documenting key methods that lacked comprehensive online explanations, particularly in 2024 when the domain was established. The book’s content covers topics like rejection sampling, outcome reward models, and character training, which are frequently encountered in post-training workflows. The author intends the book to be a practical guide for those with a bachelor’s degree in computer science, offering insights into the trade-offs and misconceptions surrounding post-training techniques.
The core of the book centers on developing intuition and understanding the historical context of these methods. It explains why post-training works, focusing on core techniques that have remained relatively stable over the past few years. The book reworked existing Interconnects blog posts to provide a cohesive narrative, often employing a more detailed explanation than typical textbooks. This approach aims to equip readers with a deeper understanding of the underlying mathematical principles and the potential pitfalls of various algorithms. The book’s content is regularly updated, with a recent addition of on-policy distillation at the last possible moment.
One key element of the book is its exploration of reinforcement learning (RL) algorithms used in post-training. Approximately 25% of the book is dedicated to RL, covering algorithms like Policy Gradient Optimization (PPO), Group Relative Policy Optimization (GRPO), Group Sequence Policy Optimization (GSPO), and Clipped Importance Sampling Policy Optimization (CISPO). The book provides a thorough explanation of the math behind these algorithms, emphasizing the importance of understanding how they influence model outputs. The book illustrates this with an example using the PPO clipping understanding, breaking down the surrogate objective into six regions and explaining the gradient flow.
Beyond the technical details, the book also addresses the broader systems challenges associated with RL in LLMs. It highlights the importance of managing off-policy data, training-inference mismatches, and throughput. The book discusses asynchronous RL with separate GPUs for learners and actors, a common approach in the field. It provides a starting point for engineers with limited LLM RL knowledge, covering topics like loss aggregation and truncated importance sampling. The book’s goal is to provide a simple resource for tinkering with systems and building a strong foundation in post-training techniques.