Amazon SageMaker HyperPod now works with Qumulo to support training models across different AWS regions. This setup allows teams to keep datasets in one region while training in another. It avoids the costs and delays of copying petabytes of data.
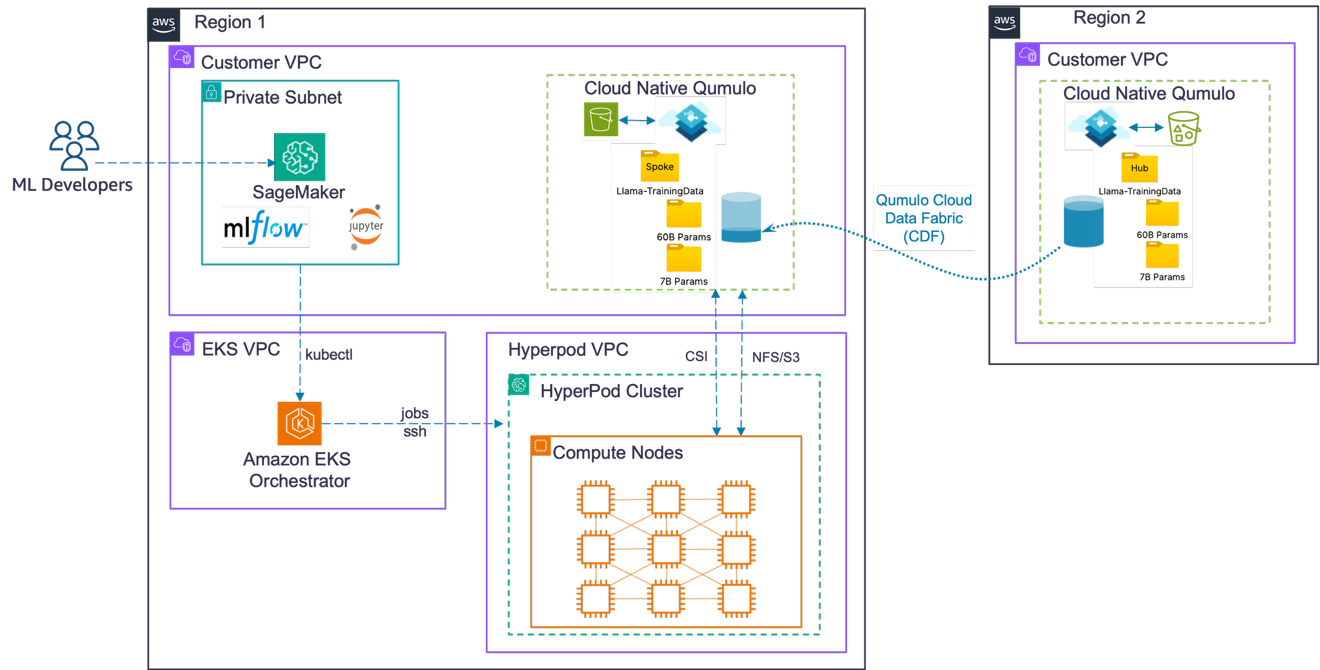
The solution uses Qumulo’s Cloud Data Fabric (CDF) and NeuralCache. CDF projects a single dataset to multiple regions and caches data locally. NeuralCache predicts which data blocks will be needed next and preloads them. This makes remote data access almost as fast as local storage.
In a validation test, a training job ran on two clusters: one in US East (Ohio) with the data, and one in US West (Oregon) reading data remotely. The job used a large language model with 16 GPUs. After a short warmup, the remote cluster matched the local cluster’s throughput.
During the initial phase, GPU utilization was 80-90 percent. After warmup, it reached 98-100 percent. The setup kept performance high without copying data or changing code. This approach reduces costs and improves training speed across regions.
The architecture involves a hub cluster in one region storing the dataset and spoke clusters in other regions accessing it over VPC peering. NeuralCache predicts data needs, and CDF manages data transfer and caching. This setup works even with network links over 100 ms latency.
This development helps teams train large models faster and more cheaply across regions. It also simplifies managing datasets and reduces the need for data duplication. Teams can now run high-performance training jobs remotely without performance drops.