

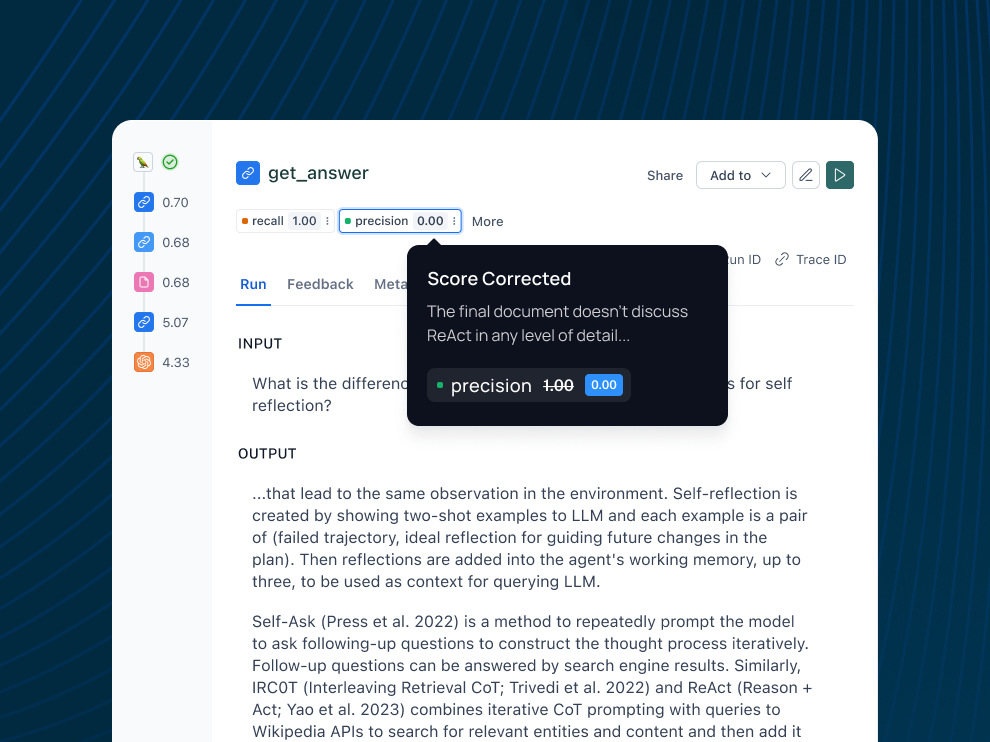
The use of LLM-as-a-Judge evaluators is gaining traction as a method for assessing natural language outputs from LLM applications. These systems leverage a separate LLM to grade the generated text, offering a practical solution when programmatic evaluation is difficult. A key challenge with this approach is the need for prompt engineering to ensure the judge LLM consistently provides accurate and relevant feedback.
LangSmith’s solution addresses this by introducing a ‘self-improving’ feature. This system stores human corrections to the judge LLM’s outputs as few-shot examples. These examples are then fed back into the evaluator prompt in subsequent iterations, allowing the judge LLM to adapt and refine its scoring criteria over time. This eliminates the need for extensive, manual prompt engineering to maintain evaluator accuracy.
Several use cases are supported by this approach. LangSmith evaluators can detect RAG hallucinations, assess RAG correctness, and identify toxic or inappropriate responses from LLMs – both in online and offline evaluation scenarios. The underlying principle relies on the LLM’s ability to access information beyond the initial generation context and its relative ease in judging an answer compared to generating one.
This development builds upon established research. The approach leverages the LLM’s proficiency in few-shot learning, a technique widely used in client LLM applications. Furthermore, it incorporates insights from recent research, including a paper by Shreya Shankar titled ‘Who Validates the Validators?’ which explored feedback collection as a method for aligning LLM evaluations with human preferences.
LangSmith’s implementation provides a streamlined process. Users can easily set up an LLM-as-a-Judge evaluator for online or offline evaluation, specifying the desired feedback criteria. The system then automatically incorporates human corrections, continuously improving the judge’s accuracy and reducing the burden on engineering teams. Source: https://www.langchain.com/blog/aligning-llm-as-a-judge-with-human-preferences