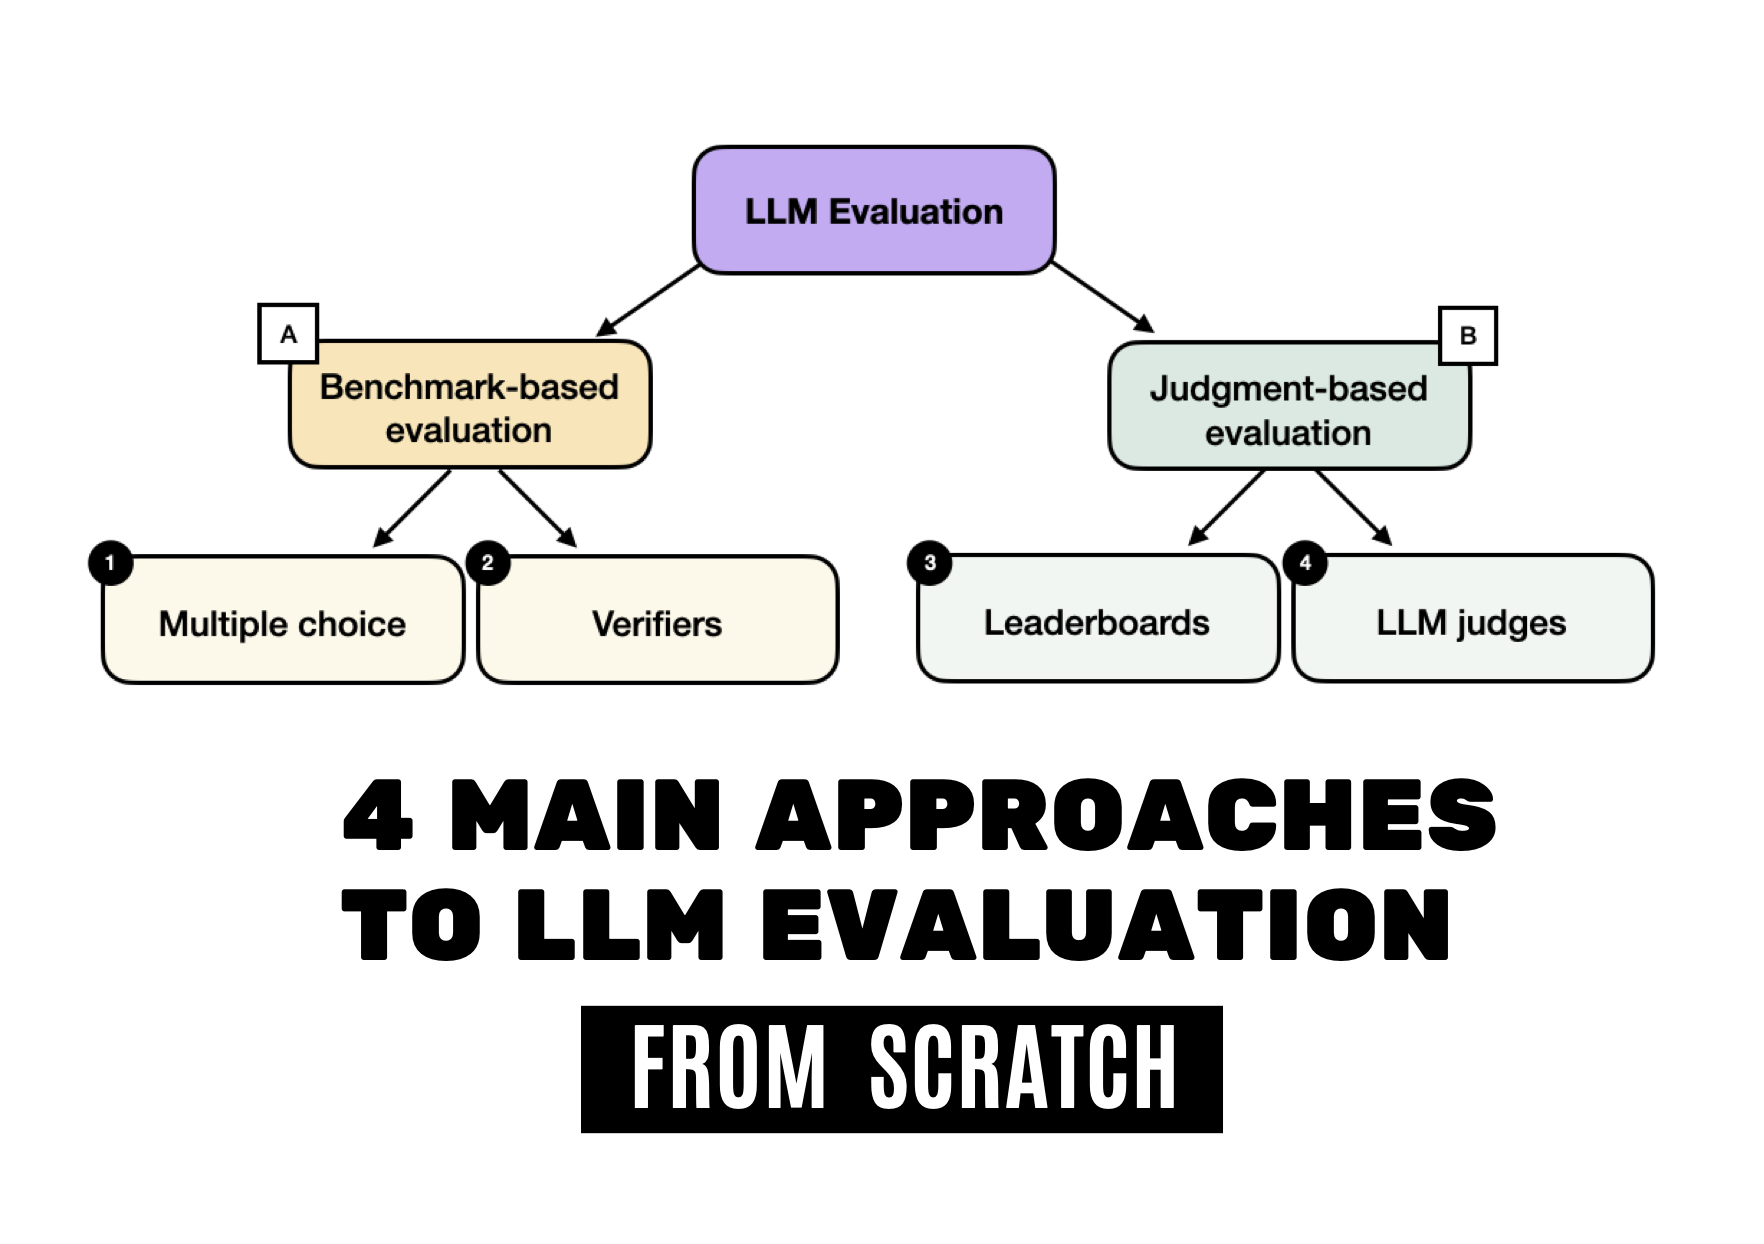
Multiple-choice benchmarks, such as MMLU, are widely used to measure knowledge recall in a quantifiable way similar to standardized tests.
The MMLU dataset consists of 57 subjects and approximately 16,000 multiple-choice questions. Performance is measured by accuracy, the fraction of correctly answered questions.
Verifiers, leaderboards, and LLM judges represent other common evaluation categories often found in research papers and model cards.
Raschka provides from-scratch code implementations for these methods using pure PyTorch. A specific example involves loading a Qwen3 0.6B model that requires about 1.5 GB of RAM.
Source: https://magazine.sebastianraschka.com/p/llm-evaluation-4-approaches