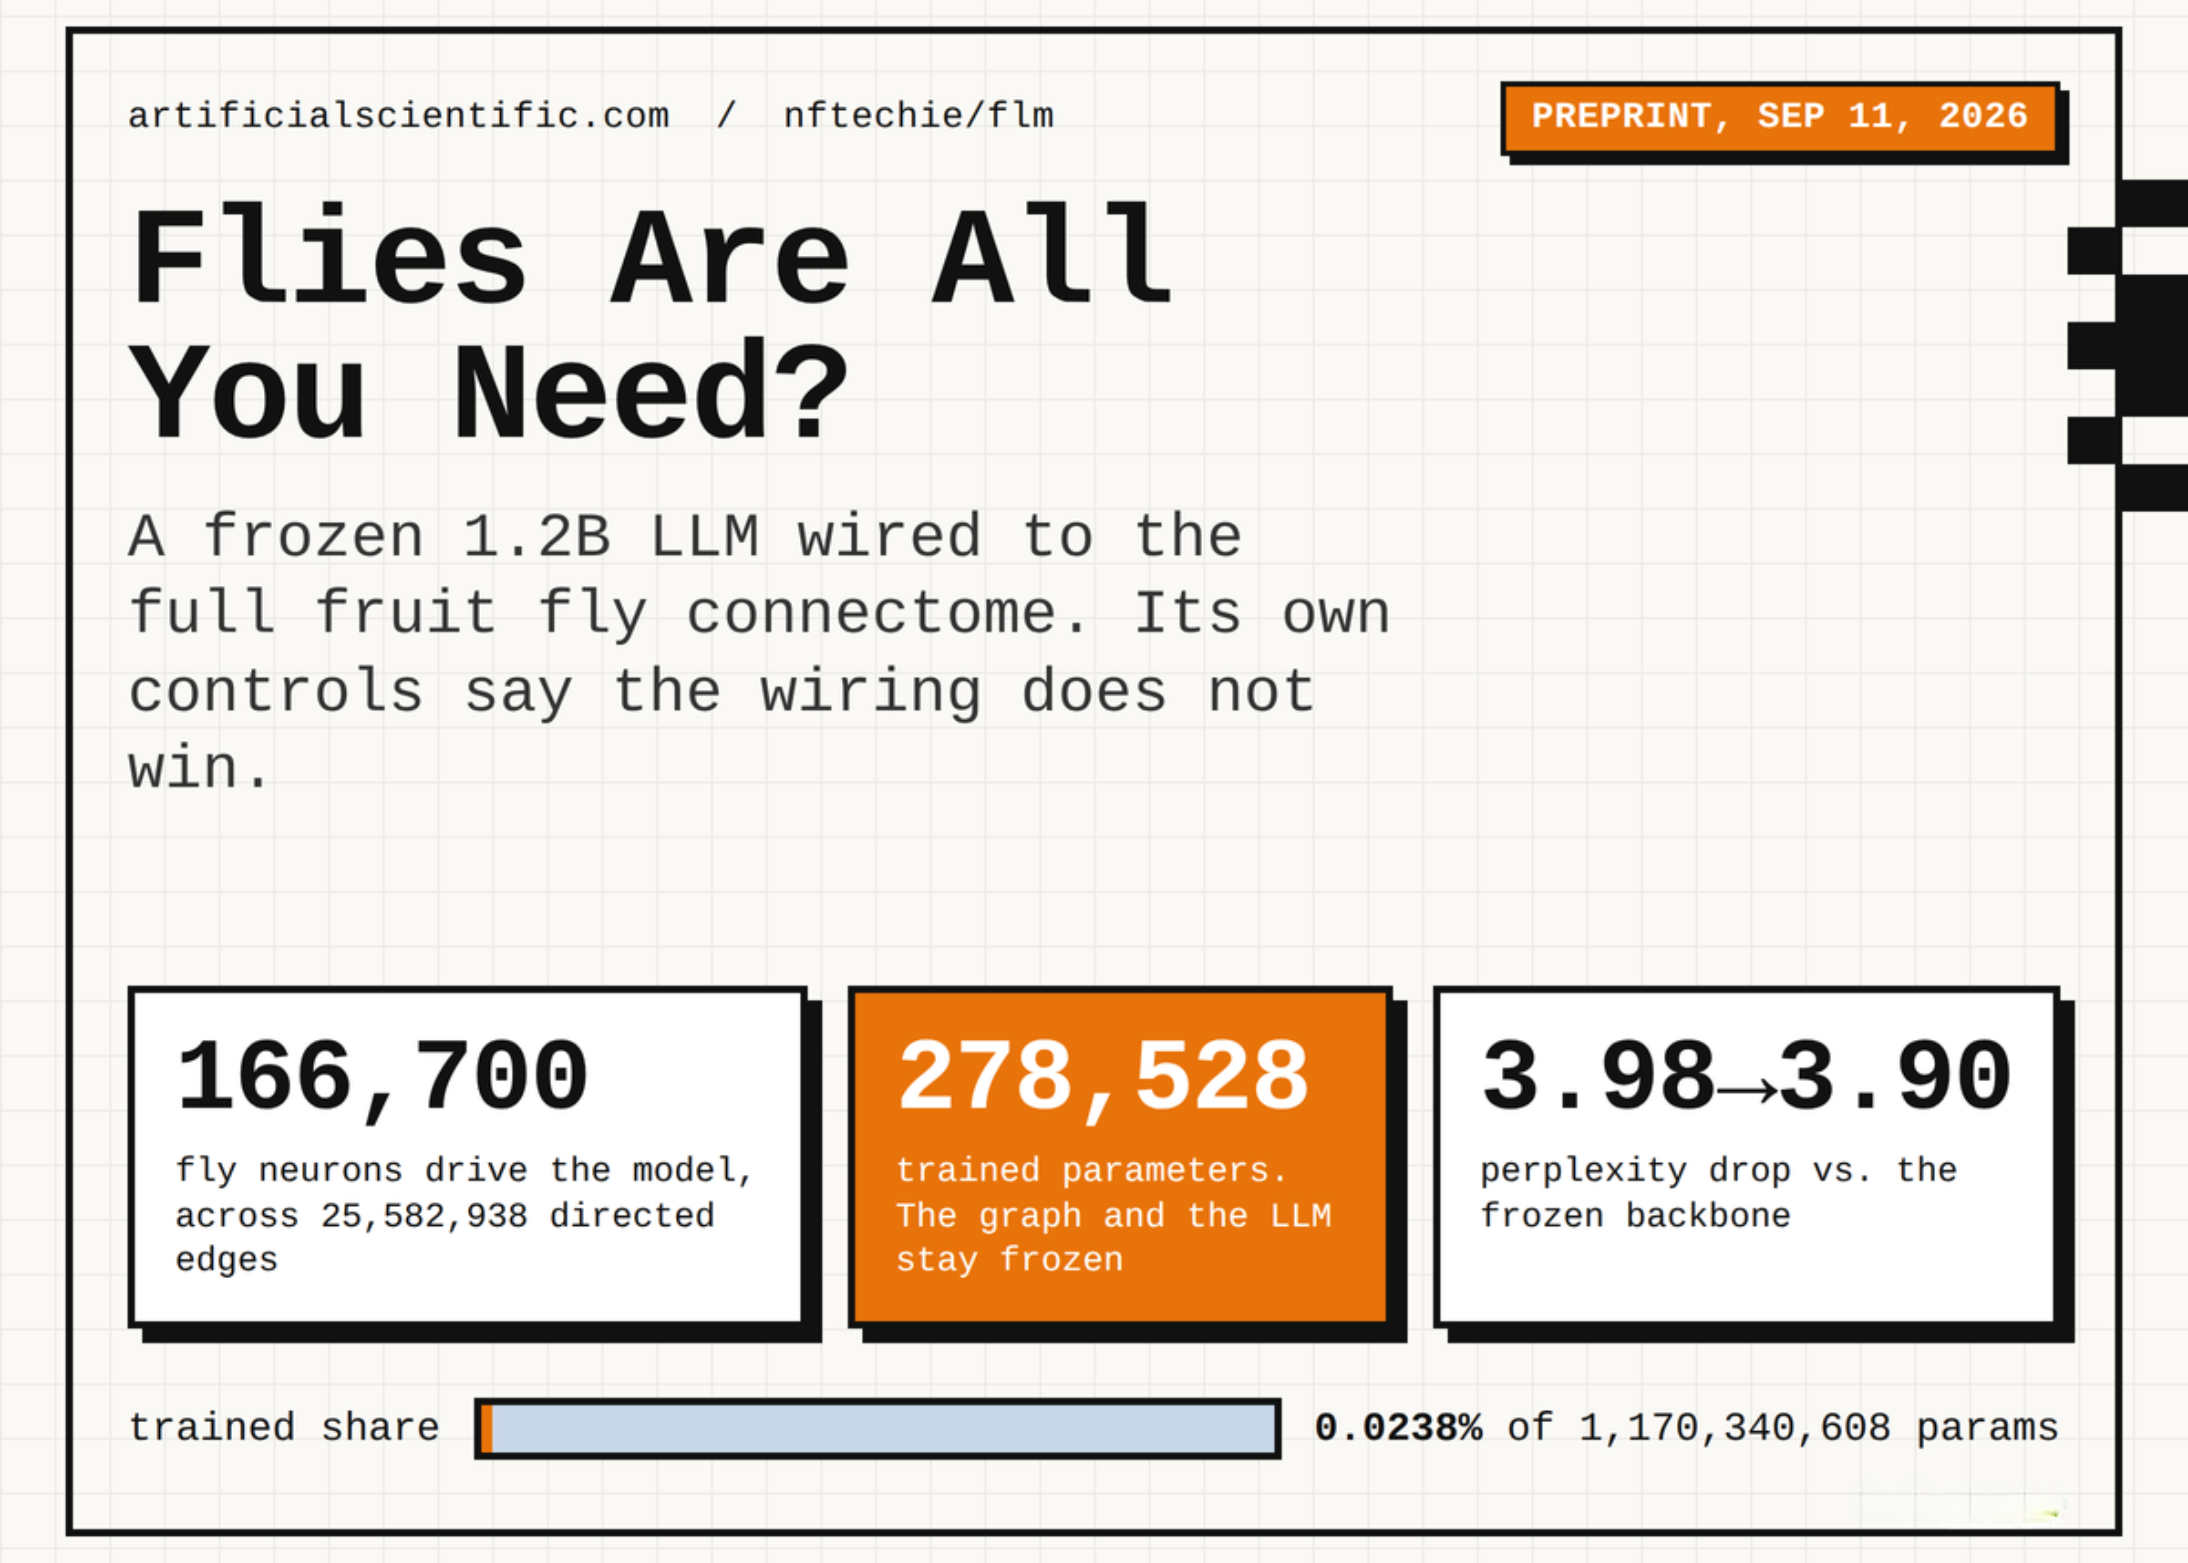
The Fly Language Model (FLM) represents a novel approach to language modeling, utilizing the complete retained MaleCNS v1.0 fruit fly connectome within a frozen LiquidAI LFM2.5-1.2B-Instruct backbone. The project, developed by nftechie, presents a public chatbot, designated as the world’s first Fly Language Model, built on the GPF (Generative Pre-trained Fly) architecture. Initial results indicate a parameter-matched control without the fly graph performs slightly better than the FLM.
Key aspects of the FLM design include a reservoir computer utilizing all 166,700 nodes and 25,582,938 directed edges of the MaleCNS graph. The graph, the backbone, and the random input and output projections are fixed. Only 278,528 parameters are trained, representing 0.0238% of the 1,170,340,608 backbone parameters. The system employs a 2,048-dimensional token embedding compressed to 128 channels via a fixed Gaussian projection. Each reservoir node receives one channel with a random sign, and the whole graph updates using a tanh function.
Testing on a set of 32 SmolTalk dialogues revealed a reduction of 0.0222 nats per token (perplexity 3.98 to 3.90) for the FLM readout. However, a direct-input control, lacking the graph, achieved a better result of 0.000488 nats per token across three seeds. Further investigation showed that removing the residual exactly (setting W to zero) reproduced the backbone’s per-token losses, confirming the graph’s participation. Relabeling node identities without retraining maintained near-baseline NLL, indicating the readout’s alignment with the learned interface, not the fly topology.
Analysis of state retention revealed a contraction of initial-state differences at most 0.6 per token, with a bound of 0.00605 after 10 tokens and 0.0000366 after 20. Despite the extensive 166,700-node connectome, long-range memory remains dependent on the frozen backbone. The research report cites ngxson/fly-hf, a previous prototype using a 49,393-cell subset, to provide context.