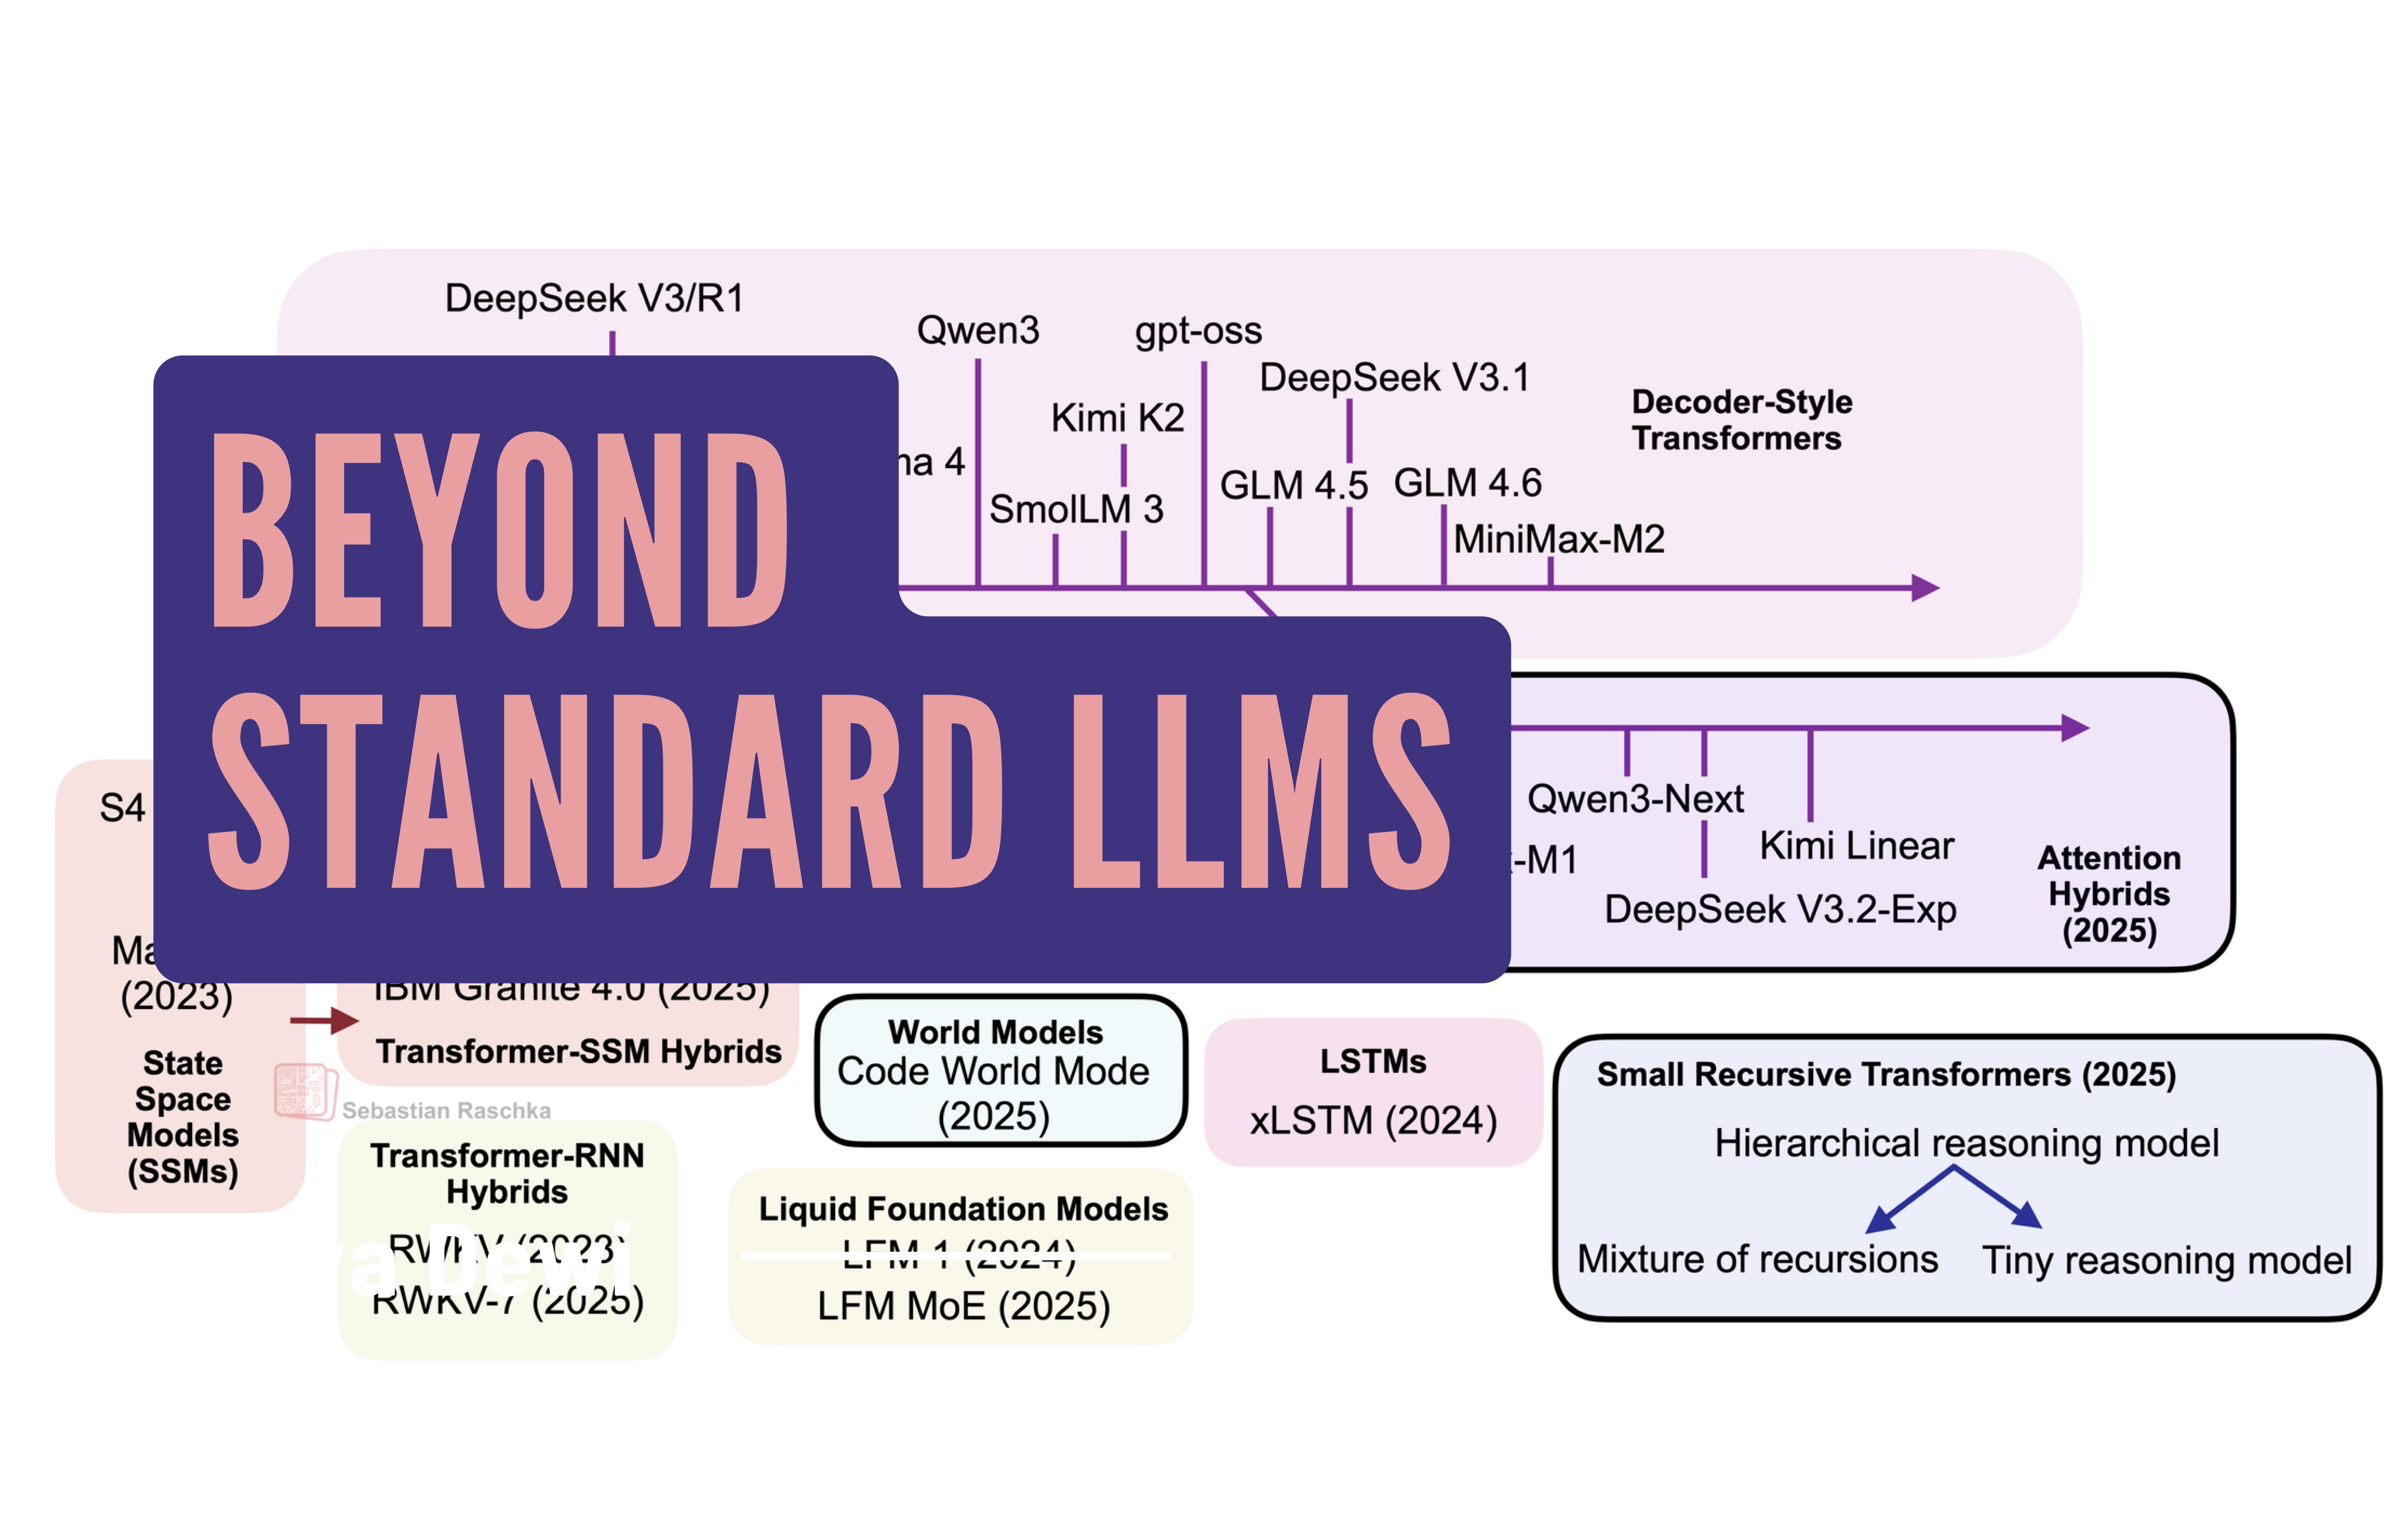
From DeepSeek R1 to MiniMax-M2, the largest open-weight LLMs remain autoregressive decoder-style transformers based on the original multi-head attention mechanism. However, alternatives such as text diffusion models and linear attention hybrid architectures have emerged to address efficiency or performance limitations.
Linear Attention Efficiency
The standard scaled-dot-product attention mechanism scales quadratically with sequence length because it computes an n-by-n attention matrix. Recent work has revived linear attention mechanisms to avoid this quadratic cost by approximating the attention calculation using kernel feature functions.
Other Architectural Alternatives
Beyond linear attention, other architectures include code world models designed to improve modeling performance and recursive transformers. While transformer-based LLMs remain state-of-the-art for text and code, these alternatives offer different trade-offs for specific use cases.
Source: https://magazine.sebastianraschka.com/p/beyond-standard-llms