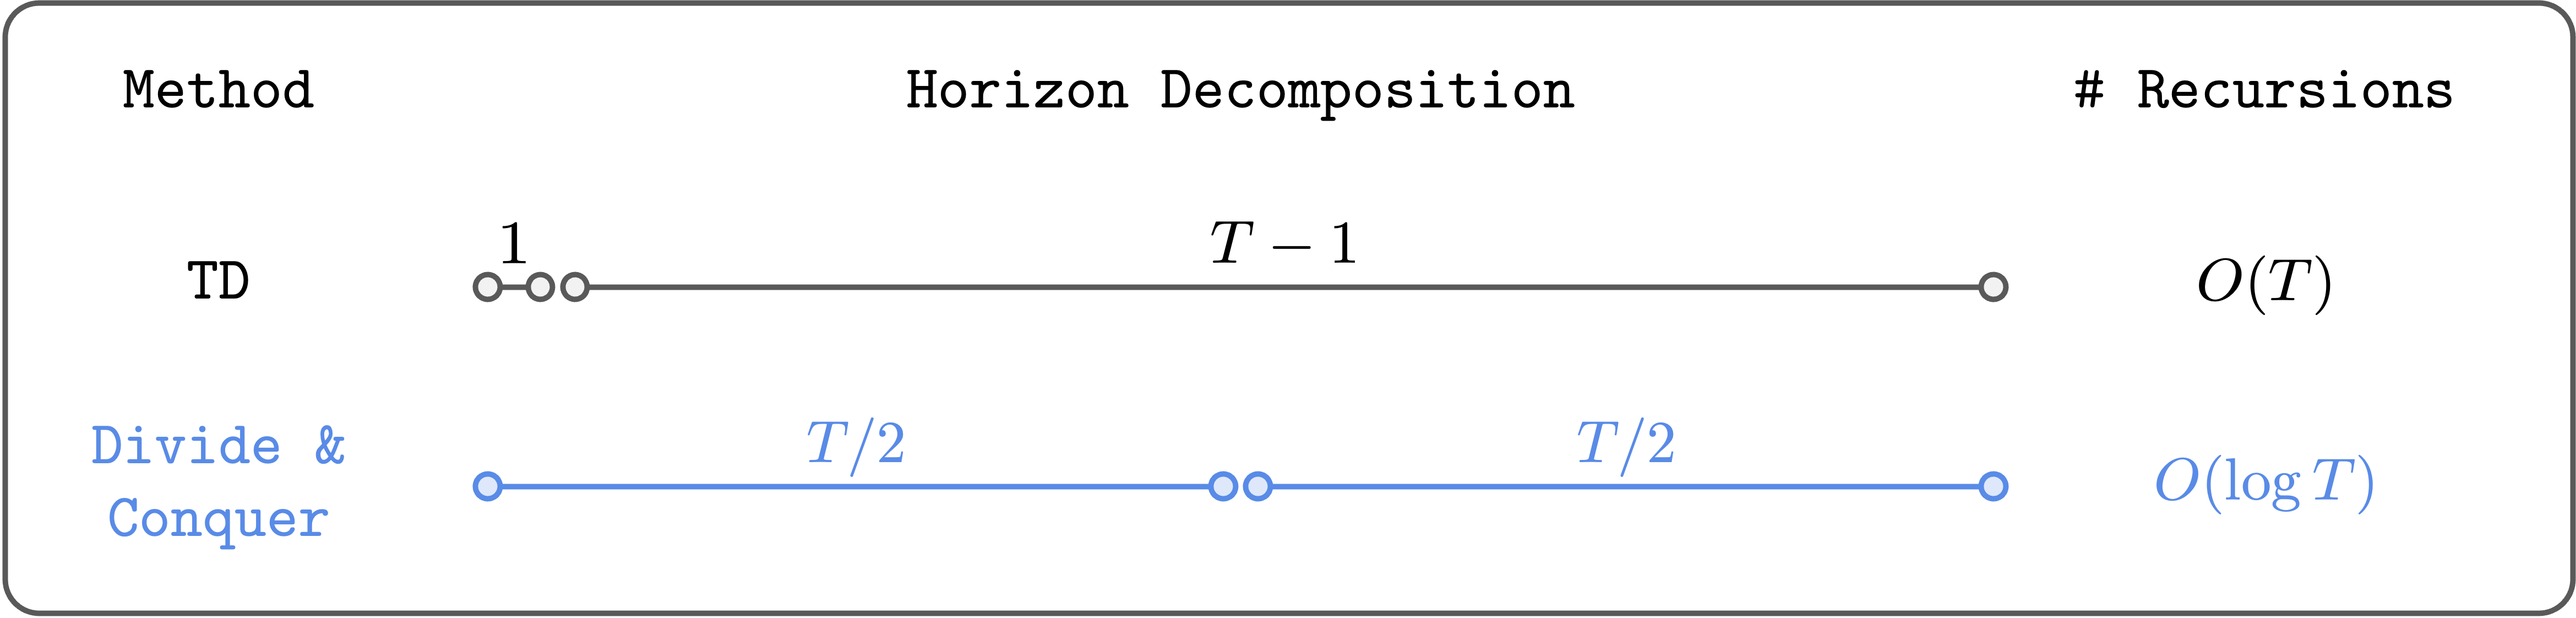
A new reinforcement learning algorithm uses divide and conquer instead of temporal difference learning.
Traditional methods struggle to scale because errors accumulate over long task horizons.
The team co-led by Aditya achieved progress in goal-conditioned reinforcement learning.
This paradigm splits trajectories into segments to update values without bootstrapping errors.
They applied this to tasks requiring a policy to reach any state from any other state.
The method relies on a transitive Bellman update rule based on shortest path distances.
Source: http://bair.berkeley.edu/blog/2025/11/01/rl-without-td-learning/