

Amazon Bedrock Knowledge Bases now enable natural language queries on claim documents. It handles unstructured files like PDFs, Word, and text, indexing them for quick retrieval.
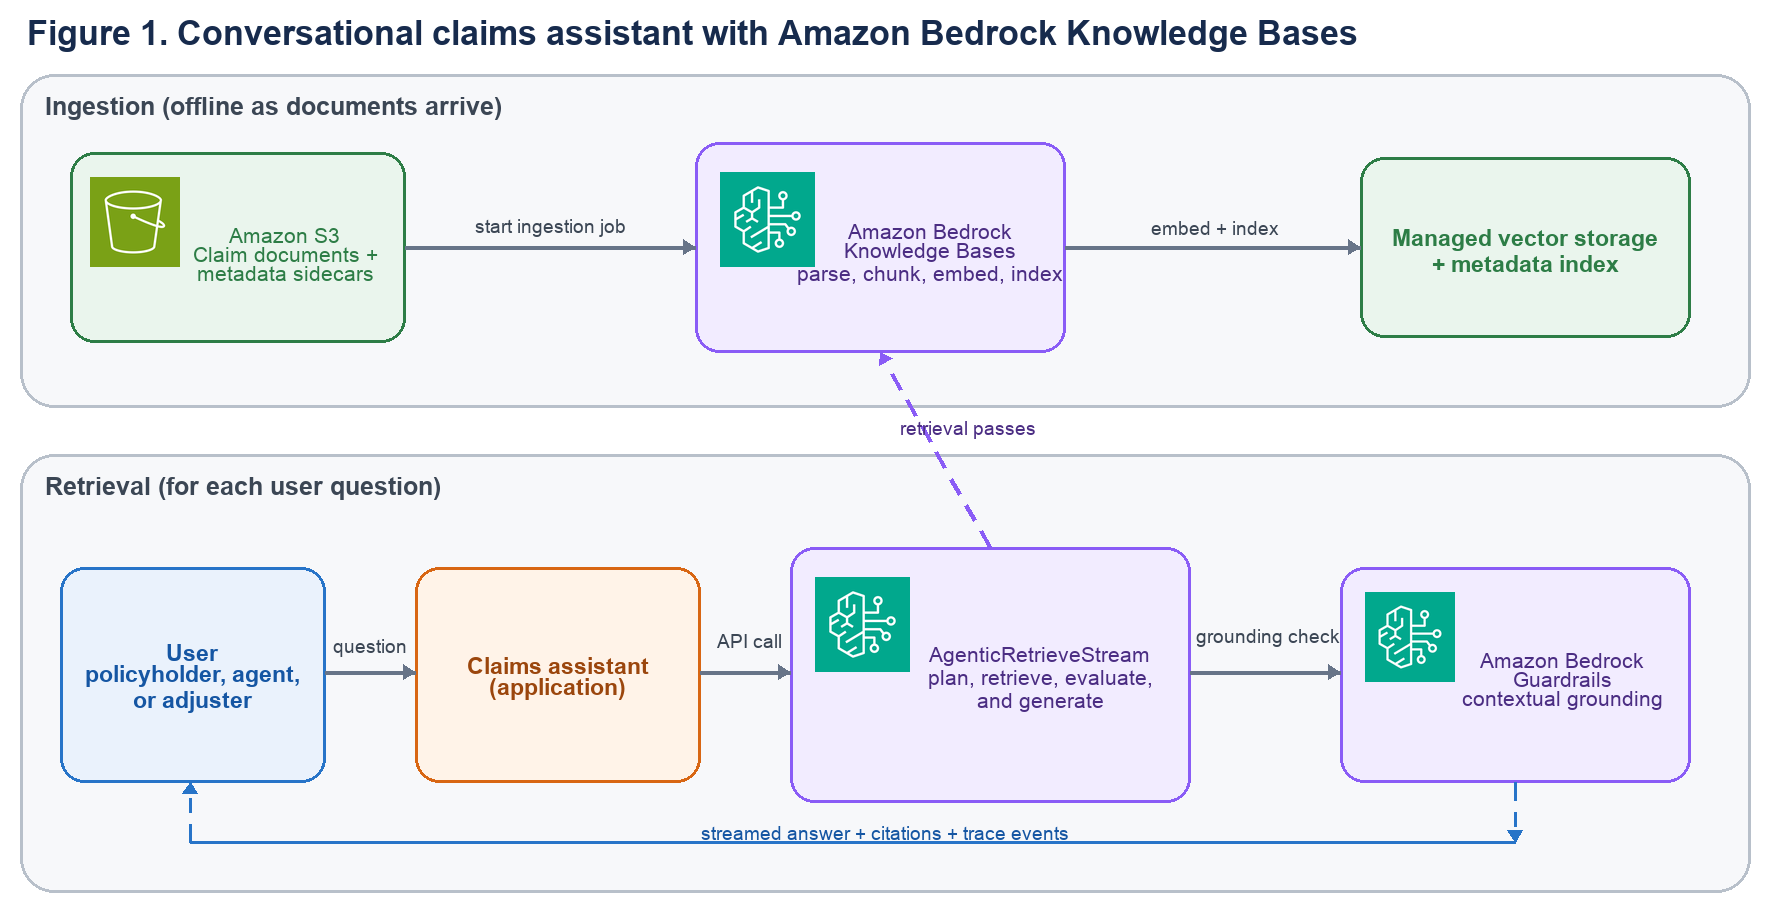
The system uses retrieval-augmented generation (RAG) to find and cite evidence from claim files. It employs the AgenticRetrieveStream API to plan answers, break questions into sub-queries, and run multiple retrieval passes.
Retrieval results can be scoped with metadata filters, such as claim ID or claim type. This helps focus answers on relevant documents and avoid conflicts or outdated information.
Answers are streamed with citations and trace events. This allows users to verify the source and understand how the answer was generated. It supports compliance and audit needs.
The process starts with ingesting claim documents into Amazon S3, where they are parsed, chunked, embedded, and indexed. The retrieval runs for each question, repeating until enough evidence is gathered.
This capability is useful for policyholders, contact center agents, and adjusters. It speeds up responses, improves accuracy, and ensures answers are grounded in source documents.
Why it matters
This feature enhances the ability to build conversational claim assistants that are fast, accurate, and transparent. It reduces manual search efforts and improves compliance.
What to do
Prepare claim documents and metadata in Amazon S3. Use the AgenticRetrieveStream API to build a question-answering interface.